# ari's space — full content ## Build Your Workspace Once. Then Don't Touch the Foundation Again. URL: https://aris-space.com/documents/workspaces/build-your-workspace-once Date: 2026-04-29 ## Narration When you start a new project, you are really creating three things, not one folder. The orchestration layer holds your briefs and plans. The vault holds your code, encrypted. The output drive holds your renders. Each lives somewhere different, and that separation is what survives migrations. ## Why I rebuilt the foundation Three roots make an orchestration layer portable across any AI agent: a workspace root for briefs and plans, a vault for source code, and an output drive for artifacts. Each has one job, and separating them is what makes the whole stack survive a migration. I spent a day rebuilding the foundation under every project I run. The orchestration layer behind everything I do, every product, every brand, every active client, sits in one root. Last week I moved that root. The move cost roughly two million tokens of Opus output, sixty-seven logged migration steps, and a purpose-built migration toolset. Worth it. Here's why I did it, what changed, and the structure I wish I'd started with. ## Why I did it The old setup grew. Three years of layered decisions, each defensible in the moment, ended up nested three folders deep with the same name repeated in each. Not a typo. Three of them. The path was a symptom. The real problems were structural. **Code, content, and config were braided together.** Every workspace held source files, render outputs, plan documents, briefs, screenshots, and configuration in one tree. Backing up orchestration meant backing up renders. Reading briefs required mounting the encrypted code drive. **Hardcoded paths were everywhere.** Tools, hooks, plugins, and native apps all assumed one specific absolute path. One move would have shattered the system. **The configuration was Claude Code specific.** Hooks, settings, slash commands all baked into one agent's surface. If I wanted to run the same workspace through Codex or Gemini, the layer of plumbing I'd need to build was its own project. **Session state and canonical config lived in the same directory.** Ten gigabytes of accumulated runtime state in `.claude/` made the workspace feel heavy. Most of it was regenerable. None of it was sorted. ## What changed The migration introduced three roots, each with one job. **Workspace root** holds orchestration only. Markdown briefs, YAML manifests, plans, decisions, content drafts, memory bank. No source code. Plain text. Version-control friendly. Readable by anything that can read files. **Vault root**, an encrypted disk image, holds source code and proprietary assets. Mounted on demand. Unmounted by default for safety. Each project has its own `.git` repo inside. **Output root**, an external SSD, holds generated artifacts. Renders, builds, exports, archived datasets. Disposable, regenerable, large. The link between them is a per-workspace `manifest.yaml` and a `links/` folder of generated symlinks. Hardcoding drops to zero. Moving any of the three roots requires updating one environment variable. ## What it changed about the work Cold start on a project compresses. The manifest tells me what's there, where the code lives, where output goes, and the project state. No spelunking. Backups simplify. The workspace root is small enough to snapshot daily without thought. The vault encrypts and rotates separately. Output is reproducible and doesn't need protection. The biggest shift is conceptual. **The orchestration layer is now portable across agents.** Briefs, manifests, memory, and protocols sit in plain markdown and YAML. Codex CLI sees the same workspace root that Claude Code sees. So would Gemini, or any agent that can read files. The Claude Code specific layer (hooks, slash commands, settings) lives in `.claude/` as an optional add-on. Strip it out and the workspace still functions. Hand it to a different agent and it still works. This is the property I care about. My system isn't tied to one model family or one tool's lifespan. The agent is a worker. The workspace is the contract. The orchestration layer is now portable across agents. ## What "we" means in this story I made the architectural call. The agent did the heavy lift across one continuous Opus session. Building the migration toolset. Copying with integrity verification at every step. Rewriting paths across thousands of files. Generating manifests for each workspace. Regenerating links. Surfacing every decision with evidence before acting. Sixty-seven steps logged. Zero destructive operations on the source. Old workspace untouched, new workspace built clean. The collaboration is the point. I architect. The agent implements. The workspace structure makes both roles legible to each other and to whichever agent I bring in next. ## The structure to copy If you're starting a new workspace today, this is the foundation that would have saved me a day and a couple million tokens. ### 1. Three roots, three jobs ``` WORKSPACE_ROOT orchestration (markdown, manifests, briefs, memory) VAULT_ROOT source code and proprietary assets (encrypted) OUTPUT_ROOT renders, builds, exports (external, disposable) ``` Export them in your shell profile so every shell sees them. ### 2. Per-workspace manifest ```yaml schema_version: 1 workspace: type: code | content | utility | hybrid brand: code_root: ${VAULT_ROOT}/ projects: - name: code_path: repo_url: output_paths: builds: ${VAULT_ROOT}/<...> renders: ${OUTPUT_ROOT}/<...> ``` The manifest is the contract. Tools read it to know where things live. ### 3. Generated links, not hardcoded paths A small script reads each manifest and writes `links/code`, `links/renders`, `links/repo.url` inside the workspace. Symlinks for live filesystem objects. URL files for remote resources. Re-run the script after any move. Everything stays connected. ### 4. Env-var paths in code Every script references `os.environ['WORKSPACE_ROOT']` or your equivalent. Never hardcode. If a literal default is unavoidable for tool-importability, env var first, hardcoded fallback second. ### 5. Small canonical config, large regenerable runtime Split your agent's local directory into two categories from the start. **Canonical config**: settings, slash commands, custom skills. Source of truth. Migrate on move. **Runtime state**: sessions, worktrees, breakouts, logs, tasks. Regenerable. Skip on move. If you keep them entangled, every migration is ten times bigger. ### 6. Memory as a plain markdown index Auto-memory in your agent's project memory directory with a one-line `MEMORY.md` index pointing at individual `.md` files. Stable slug per workspace. Index entries under 150 characters. Categorized by type: user, feedback, project, reference. ### 7. Agent-agnostic by construction The Claude Code specific bits live behind one isolated entry point: `.claude/`. Everything outside is plain markdown, YAML, and code with env-var paths. A new agent walking into the workspace sees a readable system, not a Claude-shaped puzzle. ## The takeaway Build the workspace as if you'll change agents three times in the next two years. Because you will. Models change. CLIs change. The entire tooling layer churns. The orchestration root, written in plain text with explicit env-var paths and per-workspace manifests, outlasts all of it. Do this from day one. The migration tax compounds. ## Narration The manifest lives at the top of every workspace. It declares the schema version, the workspace name, the type, the code root, and the projects within. Tools read it to know where things live. ## Narration A small Python script that reads the manifest and writes the links folder. Re-run after any move. Keeps everything connected. --- ## Building Aris Space: 8 Hours, 5 Sessions, One Site URL: https://aris-space.com/documents/discipline-and-process/building-aris-space Date: 2026-05-01 ## Narration Five sessions. Each one held a single phase. Each one closed before the context budget went above half full. The arrow between any two sessions is a written handoff document, the only thing that crosses the boundary. The capacity bar at the bottom is the rule that makes the rest of it work. ## The punchline 8 hours from concept to live site. 5 sessions. None of them above 50% context. The site is aris-space.com. Built on Next.js 15, Tailwind v4, MDX, Zustand and react-rnd, deployed on Vercel. By the time it shipped: 14 commits on the website repo, 4 on the orchestration root, 19 of 19 unit tests green. None of that's the interesting bit. The interesting bit is the protocol that made an 8-hour build feel like five clean half-hour blocks instead of one chaotic session that limps over the line. ## The constraint that made it work One rule: no session goes above 50% context budget. That sounds defensive. It's the opposite. It's the constraint that lets Claude actually finish things. A session above 50% context starts dropping precision. It re-reads files it already read, re-litigates decisions it already made, hedges on commits it already understood. The output looks fine. The signal-to-noise quietly halves. By 80% you've got an expensive autocomplete that vaguely remembers your project. So I cap it. When a phase is done, the session is done. Written handoff before close. New session opens cold and reads the handoff like a contract. The trade-off is an extra ten minutes per phase boundary writing the handoff. The win is that every session opens at peak signal and closes before it degrades. Across 8 hours, that compounds into something that looks suspiciously like quality. ## How it worked Five sessions. Each one had a single phase to deliver and a written handoff to leave behind. **Session 1.** Workspace setup. Spec, decisions log, manifest, repo scaffolding. Closed at handoff: "Phase 1 complete, foundation ready." **Session 2.** Desktop shell. Window manager, draggable panes, the System 7.5.3 aesthetic. Closed at handoff: "Phase 2 complete, shell working, content empty." **Session 3a.** Content layer mid-phase. MDX pipeline, topic routing, the registry. Closed at: "Halfway through Phase 3, here's what's wired and what's left." **Session 3b.** Phase 3 mid-2. Picked up the handoff, finished the content layer. **Session 4.** Tonight's mega-session. Analytics, MCP wiring, deploy, smoke tests, two posts live. Each handoff doc is the same shape. What's done. What's next. What I tried that didn't work. What state is on disk vs. in my head. The next session reads it once and can act. The other rule: brainstorm before you build, on anything non-trivial. A short conversation about shape, edge cases, what done looks like. Cheap. Catches the wrong abstraction before it costs an hour to unwind. ## What MCP unlocked The analytics wiring is the cleanest example. I didn't write it. I asked Claude to do it. Claude reached the live PostHog project through an MCP server, read the project settings, retrieved the project key, set the Vercel env vars on the website, and flipped session recording on. End to end. I read the diff and confirmed. Generalise. Any MCP server is a tool that Claude can drive directly inside the same session. No copy-paste. No "go grab this from the dashboard". The tool is part of the workspace. That's the shift. The agent isn't just writing code that talks to your tools. It's using your tools the same way you do. The system around the AI is the intelligence. ## The numbers - 5 sessions - 8 hours total - 14 commits on the website repo - 4 commits on the orchestration root - 19 of 19 unit tests passing - 0 sessions above 50% context ## The takeaway The system around the AI is the intelligence. A capable model with no protocol burns context, drifts, hedges, and ships something that's almost right. The same model with a 50% cap, a brainstorm gate, written handoffs and tool access through MCP ships a live site in 8 hours. I architected. Claude executed. The protocol made both roles legible. Build the protocol once. Then run it. --- ## Stop Prompting. Start Defining Outcomes. URL: https://aris-space.com/documents/thoughts-and-scribbles/stop-prompting-start-defining-outcomes Date: 2026-05-02 # Stop Prompting. Start Defining Outcomes. Most people are using AI like a slot machine. Pull the lever. Watch the wheels spin. Hope it lands on something usable. When it doesn't, they pull harder. Better prompt. Different model. Maybe a longer system message this time. That's not making. That's gambling. I spent a year doing exactly this. Punching prompts at midnight. Watching the output come back generic. Blaming the model. The model wasn't the problem. My briefs were three lines long. Of course the output was three lines deep. I was bringing nothing to the table and asking the AI to bring everything, and then complaining when what came back didn't have my fingerprints on it. It couldn't. I hadn't given it any. The makers I respect, the ones shipping work I'd pay for, aren't doing any of that. They're not refining their prompts. They're refining their **briefs**. They've stopped asking AI for things and started telling it what they're building. They've moved from gambling to direction. This is the difference. And once you see it, you can't unsee it. ## Outcomes, not prompts A prompt is a wish. An outcome is a brief. When a director hires a DP, they don't say "shoot me a video." They give a brief. Audience. Runtime. References. Tone. Three frames they want to land. What success looks like. What it absolutely cannot look like. That brief IS the work. The shoot is downstream of it. AI deserves the same respect. If you can't write a brief tight enough to hand to a junior, your prompt isn't going to save you. The model isn't going to fill the gap your thinking left open. It'll fill it with the average of the internet, which is exactly what generic output looks like. Average. So stop asking. Start defining. **The brief is the work. Everything downstream is execution.** When I shifted from prompting to briefing, two things happened. The output got dramatically better. And I stopped feeling like I was begging an algorithm for scraps. A scar from earlier this year. I lost a full render cycle on a carousel because I told the AI "less wash" instead of specifying overlay colour. Black wash and white wash are different things. Reducing white wash makes the image lighter, not darker. The model wasn't being stubborn. My brief was ambiguous. It made a reasonable interpretation of an unreasonable instruction, and I burned an evening as the price. The lesson wasn't "AI can't read your mind." The lesson was "your brief is the contract." If you'd hand the same brief to a junior on set and watch them produce the wrong shot, the brief is wrong. Fix the brief. Don't blame the junior. Don't blame the AI. ## Context is king Models are interchangeable. Context is yours. I'll say that again because it's the line that should change how you think about this. **Models are interchangeable. Context is yours.** GPT, Claude, Gemini, whatever ships next. They're commoditising. Six months from now you'll have a faster one, cheaper one, smarter one. None of that is your moat. What's yours is everything you bring to the brief. Your references. Your voice rules. Your past work. Your taste, encoded into examples. Your industry. The decade you've spent learning what works and what doesn't. That's the moat. That's what makes the same model produce generic output for someone else and your-output for you. A bad prompt with the right context beats a great prompt with no context, every single time. I've tested this. So has anyone who's serious. Stop trying to write the perfect prompt. Build the context that makes any prompt land. ## The 10% trim pass Here's what AI does to your timeline. Old craft: 90% grind to get to 90%, 10% polish for the last bit. The grind dominates everything. Most of your day, most of your week, most of the work. New craft: AI hands you 90% in 10% of the time. The grind compresses to almost nothing. Then you spend the other 90% of your time on the trim pass. The polish. The taste call. This sounds like a win. It is. But it has a sharp edge. **Your taste is now the bottleneck.** When the grind was the bottleneck, taste was a luxury. You'd ship okay work because you ran out of time. Now you have time. The only thing standing between your output and great is whether you can see what's wrong with the 90% AI handed you. So train your taste. Look at more work. Cut more. Critique your own output the way you'd critique a junior's. The trim pass is where the craft lives now. Spend the time you got back on getting better at the part that's still yours. ## Make it the tool you need The default AI is built for everyone. Which means it's built for no one in particular. Definitely not you. Your AI should bend toward your craft. For me, that's video and stills. So my workspace knows what a brief looks like for a campaign. It knows my reference library. It knows the difference between how I write for LinkedIn and how I write for Skool. It knows my voice rules cold. None of that came pre-installed. I built it. Piece by piece. Every time it got something wrong, I noted what it missed and added the context that would have prevented it. Your AI plus your workspace should be an extension of your existing abilities, not a replacement for them. If you're a photographer, it should know light. If you're a writer, it should know your sentence rhythm. If you're a director, it should know your visual language. This is the part most people skip. They use the default and complain it's generic. The default IS generic. It has to be. You're the one who has to make it specific. ### Pushing Frames as proof [Pushing Frames](https://github.com/PUSHINGSQUARES/pushing-frames) is an image-gen plugin built at Pushing Squares. It produces on-brief frames, repeatable, that look like they came out of a campaign and not out of an AI demo. It works because of what loads behind it. Twelve years on set. Campaign work for clients you've heard of. CxN's reference library, built across stills and film, decades deep. Visual language that came from being a creative director, not from reading prompt engineering posts. A voice spec locked into the workspace. Tooling shaped specifically for stills and video output, not for general-purpose images. That's the stack. The model is the lightest layer. The context underneath is the heavy bit. What does twelve years load into a brief? Things that don't write themselves up well in a single prompt. The way light reads on skin under a specific kind of overcast. Why a campaign frame with too much negative space looks expensive and one with not enough looks cheap. Which references are honest references and which are mood board theatre. The difference between a frame that's clean and a frame that's empty. None of that lives in any model's training data with your name on it. It lives in your eye, and the only way it gets into the AI is if you put it there, on purpose, in the brief. And here's the meta point. Pushing Frames itself was built using this method. Outcome-defined. Briefed against industry context. Iterated on the tool while building the tool. The first version was rough. The brief for the rough version included reference frames I wanted, voice rules for how the plugin should describe itself, and a strict definition of what "on-brief" meant for the output. Each release tightened the brief and the output got closer to the campaign work that inspired it. The plugin grew up the same way a junior does. Trained on real briefs. Corrected when wrong. Trusted more over time. The tool that helps you make tools is itself a product of this method. That's not a marketing line. That's the actual recursion. You can pull the repo and read the briefs. ## The users should be the makers Here's the next move once you've got this far. If you're using a tool you didn't build, you're inheriting someone else's assumptions. Their interface choices. Their defaults. Their idea of what your job is. Sometimes that's fine. Most of the time it isn't. The best tools are made by the people who need them most. Pushing Frames was made by a creative director, for creative directors. Aris Space was made by a maker who wanted a knowledge-sharing site that didn't feel like a Substack. The plugins coming out of Pushing Squares are made by people who shoot, edit, and ship daily. This is the difference between AI users and AI-native makers. The users wait for someone to ship the tool they need. The makers ship it themselves, badly at first, then better. You don't need permission. You don't need to be a software engineer. You need an outcome, a brief, and the willingness to iterate when version one is rough. **Stop waiting for someone to ship the tool you need. You're the one who needs it. You're the one who should be making it.** ## Grow with it like an employee You don't fire a junior for getting it wrong twice. You teach them. Treat your AI the same way. Encourage what it does well. Highlight what it's missing. Build a brief that compensates for its weaknesses, the same way you'd build a checklist for a new hire. The relationship compounds. Day one it's a stranger. Month three it knows your voice. Month twelve it's drafting briefs you'd write yourself, which means you can spend your time on the calls that still need a human. The mistake is treating it as a finished employee on day one and getting frustrated when it can't read your mind. It can't. Nobody can on day one. You wouldn't expect it from a person. Don't expect it from your AI. What you should expect is improvement. If your output isn't getting better month over month, your context isn't getting better. Fix that. ## Summary Most of what's wrong with AI output is wrong with how people are using it. The slot machine pull. The thin prompt. The default workspace. The wait for someone else to ship the right tool. None of that is the model's fault. The makers I respect aren't waiting. They're defining outcomes, building context, training their taste, and shipping tools they need. The output looks like them because the work is them. The AI's the lightest layer. If you want output that doesn't look like everyone else's, stop prompting. Start defining outcomes. Build the context that's yours. Train the trim pass. Make the tools you need. I don't gatekeep. But you have to ask the right questions. --- ## The Codex Loop: A Native App Dev Playbook URL: https://aris-space.com/documents/discipline-and-process/the-codex-loop Date: 2026-05-03 ## Narration The brain holds the contract. The hands ship the code. The eyes approve the result. Three roles, three separate contexts, one product. A planning model holds the spec, the plan, the briefs, and the verification judgment in a single consistent context. An executor model takes one chunk at a time against a tight contract with no memory between chunks. You sit on top, eyes on the visuals, refusing to auto-approve based on a commit message. ## The bug that wrote this playbook The Codex Loop splits an AI-assisted build into three roles: a planning model that holds the spec and judgment, an executor that ships one task at a time, and your own eyes on the visuals as the final gate. The story below is why that split exists. A previous build of the same app shipped 8 phases with green ticks. 61 tests passing. Screenshots in every chunk report. Done markers everywhere. First launch was a black screen. The contract had drifted three phases earlier. The same context that introduced the drift was the one validating the work. Self-audit can't catch this. The degraded session that produced the bug is the same one evaluating it. The Codex loop is the answer. Separate the **brain** from the **hands**. ## The split **The planning model holds the brain.** Spec. Plan. Briefs. Verification judgment. One consistent context across the whole project. **The executor model does the hands.** One chunk at a time. Tight contract. No memory between chunks. Cheap to dispatch, ruthless about scope. **You do the taste gates.** Final eyeballs on visuals. Approval to proceed. That's it. The rest is mechanics. Shipped end-to-end on a recent native Mac app over three days. Two phases tagged clean. 123 tests green. Atmospherics visually approved on first build. Zero rebuilds. ## The five artifacts Every project produces these in order. Each is a distinct file with a distinct role. ### 1. The spec What the thing is. Architecture. Decisions. Component table. The atmospheric and craft details. Two inventories the spec must include: - **Craft inventory.** The prototype details that aren't in the original brief. Every glow, asymmetry, animation curve. The stuff a wireframe spec misses and a built thing has. - **Staleness inventory.** Paths, tools, values that drifted since prior work. Catch this before implementation, not during. ### 2. The plan How to build it. Tasks. Tests. Commits. One plan per phase. Each task is two to five minutes of work. Every task lists files-to-touch, steps, tests, and the exact commit message to use. TDD discipline baked in. Write the failing test, run, implement, run, commit. The test is the spec. A self-review checklist at the end maps every spec requirement to a task. If a requirement has no task, the plan isn't done. ### 3. The briefs Dispatchable units of plan. One brief per chunk. Five to eight plan tasks each. Frontmatter declares the phase, the plan tasks covered, what it depends on, and the executor tier. Body covers objective, scope, hard rules, stop conditions, and the done signal. Briefs stay 60 to 95 lines. If a brief grows past that, it should have been two chunks. ### 4. The prompts The actual messages sent to the executor. Every prompt is paste-ready. No fill-in-the-blanks. Two flavours: - **Continuation prompt.** "Chunk N verified. Proceed to chunk N+1, read brief X, same rules. Stop when done." - **Fresh-session prompt.** Fully self-contained. Project context. All inputs to read. Full state verification. Hard rules. Stop conditions. Done signal. The executor can pick it up cold. ### 5. The handoff End-of-session continuity doc. Written at natural break points or before context approaches limits. Where things are right now. The next prompt to paste. Decisions made this session. Open items. The next day's session starts cold and reads the handoff like a contract. ## The dispatch loop ## Narration Per chunk, the rhythm is the same five steps. A paste-ready prompt. An execution window of five to thirty minutes. A report. A verification pass with fresh context. A decision, approve or correct. The verification step is what made the bug at the top of this page impossible. Codex sometimes claims victory prematurely. The verification step catches it. Verification is non-optional. Trust commit messages, but verify: - Git log matches expected commit messages exactly. - The file system has the files the brief promised. - The build runs the test count the brief promised. - Snapshot baselines committed without `isRecording = true` left on. - For visual chunks: launch the app and look at it. The brain holds the contract. The hands ship the code. The eyes approve the result. ## Slice mode The executor's auto-compaction failed mid-chunk twice during one phase. The pattern was clean: - Chunks of 3 to 4 tasks: stable. - Chunks of 5 or more tasks: about half the time, compaction crashes near task 5 or 7. The fix is conceptual. **Per-prompt scope is the rate limiter, not the chunk size.** Briefs stay as documentation of milestone-shaped work. Prompts dispatch slices. For a 7-task chunk, dispatch becomes: - Prompt A: tasks 1 to 4. Stop. Wait. - Verify. Paste prompt B. - Prompt B: tasks 5 to 7. Stop. Wait. - Verify. Move on. The dispatch overhead of one extra continue prompt is much smaller than recovering from a compaction crash mid-chunk. ## Plan corrections in flight When the executor hits a divergence between spec and reality, **good executor behaviour is to stop and surface**. This happened four times during phases 1A and 1B. It was the most valuable signal in the whole build. The process: 1. The executor stops and surfaces the divergence with evidence. 2. The planner inspects. Git status, file diffs, test failures. 3. The planner rules. Was the spec wrong, did the executor misread, or did reality change? 4. If the spec was wrong, fix it inline and document in the handoff. 5. Send a corrected prompt with the new authoritative info. Real examples: **Token drift.** The plan transcribed colour hex values best-effort from a digest of the design reference. The executor caught that 11 of 17 didn't match the canonical CSS. Ruling: CSS is canonical. Plan and tests updated inline. Execution resumed. Cost: 30 minutes. Saved: hours of wrong-colour rebuilds later. **Property wrappers on computed properties.** The plan used a `@Published` pattern that doesn't compile in Swift. Property wrappers require stored properties. Ruling: switch to `@Published` stored with `didSet` for persistence. Plan corrected. Execution resumed. Cost: 15 minutes. **Polling test flakiness.** The executor caught a timeout-versus-interval mismatch on the second test failure. Ruling: inject a deterministic dispatch timer. The executor chose the cleaner option. Cost: 20 minutes. Made every future polling test stable. **Snapshot regression risk.** When a composition view replaced a frame, the earlier snapshot test would compare against the new rendering. The executor anticipated this before it broke and added an override path so the old snapshot kept passing. Foresighted recovery. Cost: zero. Preempted. The pattern: don't paper over divergences. They surface real bugs in the contract. Treat them as signal, not noise. ## Visual gates Some chunks need human eyeballs, not test assertions. Examples: - The atmospherics chunk. Vignette top-anchored versus corner-anchored is invisible to test code. - The terminal chunk. Glow treatment on the embedded TUI versus default. - The dispatch baselines. Phase badge colours look right per the spec. - The integration chunk. Does the whole thing feel built, or feel like a wireframe. The pattern: the brief's done signal includes "Stop and ask for visual approval before declaring done." Don't auto-approve based on commit messages. ## Test discipline **TDD as contract.** The plan specifies tests first, then implementation. The test is the spec. Hard rule for the executor: don't change a test to make it pass. Fix the implementation, or surface the question. This made the executor push back on three real plan errors instead of silently working around them. **Snapshot tests with recording discipline.** Uncomment `isRecording = true` once to capture a baseline. Re-comment it before commit. Eyeball every baseline before it lands. Baselines become truth, so don't auto-rebaseline on regression. Surface the diff. **Manual smoke tests for the un-unit-testable.** Metal kernels rendering. Embedded terminals spawning. Drag-and-drop. Live polling. The plan instructs the executor to launch the app and confirm specific properties before declaring a task done. The smoke step lives in the brief's done signal so it can't be skipped. **Deterministic timers in tests.** Real timers make tests flaky. Inject the timer as a closure or protocol so tests can advance time. Apply once after the first flake, not after the third. ## Executor tier mapping | Tier | Use for | |---|---| | Medium | Boilerplate views. Value types and enums. Settings panes. Most of the work. | | High | Cross-API choreography. Three-or-more-framework chunks. Multi-step contract refactors. The architectural-judgment chunks. | Default to medium. Reach for high only when the chunk crosses three or more frameworks at once, or when it's the chunk where a class of bug previously bit. ## Anti-patterns avoided **Self-audit.** The executor evaluating its own work. Solved by the planner running verification with fresh context. **Done markers without proof.** Every chunk's done signal includes test count, commit hashes, file paths, and visual evidence. **Plan-of-the-plan.** Resist writing a separate methodology doc on top of the spec when the spec is already implementation-detailed. Save that for the playbook after the build, not before. **Blind retry on flaky tests.** When the polling test failed, the response was not "run it again." It was "diagnose the root cause and architect the fix." ## Anti-patterns that bit **Hardcoded paths from prior environments.** Old absolute roots blocked dispatch on the migrated machine. Fix: env-var roots with auto-detect fallback. Never hardcode an absolute path. Always derive from the script's own location with an env var override. **Best-effort token transcription.** Taking design tokens from a text digest instead of canonical CSS. Fix: treat the design reference itself as canonical. Read the prototype, don't paraphrase it. **Property wrappers on computed properties.** They don't compile in Swift. Always store, then persist via `didSet`. ## Day-one setup for a new app To bootstrap this loop on a new Apple-platform project: 1. Brainstorm the spec with the planner. 2. Write the phase 1 plan with the planner. 3. Carve the plan into briefs. 4. Open a fresh executor session per chunk. Paste prompts in slices of three to four tasks. 5. Verify after each slice. Git, tests, files, eyeballs. 6. Commit a handoff at session end. Repeat steps four to six until the phase ships. Then plan the next phase against the actual built thing, not against the spec's idealised vision. ## The takeaway The brain holds the contract. The hands ship the code. The eyes approve the result. Three roles, three contexts, one product. Self-audit is a trap. The session that wrote the bug is the worst session to evaluate it. Verification has to come from a context that didn't produce the work. Slice for compaction. Treat divergences as signal. Eyeball the visuals. Write the handoff before the session is done with you. The shape stays stable: separate brain from hands, slice for safety, verify before approving, treat divergences as the most valuable signal in the build. --- ## The Install URL: https://aris-space.com/documents/thoughts-and-scribbles/the-install Date: 2026-05-03 Hi. My name is... Most of you thought *Slim Shady*. You didn't choose to. Your brain finished the line for me. That's not a memory. That's a file. Eminem put a .mp3 on enough devices that 27 years later the phrase auto-completes in your head before you've had time to decide whether to finish it. You are the evidence. Before I've made any argument, you've already proven the thesis on yourself. The .mp3 isn't the song. The .mp3 is the install. And the install is what survives everything else. Not the tour. Not the interviews. Not the chart position. The file on the device. The thing that kept traveling after the moment that made it was long over. I've been building things long enough to have a folder full of projects that didn't travel. Launches that landed for a week and then went quiet. Work I thought was strong that didn't earn a second look. And other things, scrappier things, that ended up everywhere. That people I'd never met knew about. That came back to me years later in the form of "I've been using this since forever." The difference wasn't quality. It was distribution. Not distribution like marketing. Not "post more content." The kind of distribution that puts your format on someone's device and leaves it there. The kind that becomes part of a workflow before anyone has consciously decided to adopt it. The quiet install. The format that gets kept even after its creator has stopped thinking about it. Here's the thing about quality versus distribution: the best version of something that no one has isn't better than the good-enough version of something that everyone carries. The PDF isn't the most elegant document format. It won because it ended up on more devices than anything else. Same with the .mp3. Same with the .jpeg. The format that earned a life was the format on the most machines. Not the most correct. The most installed. Distribution earns legacies. Distribution IS the legacy. {/* Fig 1 - file extension reveal loop. .pdf .mp3 .jpeg cycling, .PushingSquares revealing at bottom. Refined retro System 7. */} What I keep going back to There's a notes format I've been using for three years. Not because it's the best one available. Because it's become part of how I think. The structure has got into my head. I open it before deciding to open it, which means it won. The format earned a place in my process before I had any real opinion about it. There's a community I check before anything else in the morning. Not because I made a decision to prioritize it. Because it became the room I go to first. The people there have earned attention I didn't consciously budget. It installed itself. There's a file format I've been shipping work in for a couple of years. Not because it was the obvious choice at the time. Because once I started, I noticed what got opened and what didn't. The files that traveled were the files in that format. Not because the format was technically best. Because it spread. The thing in common: I didn't decide to keep going back. The format made the decision for me. That's what earned distribution looks like from the inside. Not "this is objectively the best tool." Not "I consciously chose this." More like: it's already loaded. I'm already inside it. The switching cost has disappeared without me noticing. The thing didn't win a competition. It became load-bearing. The .mp3 isn't the song. The .mp3 is the install. Once it's on the device, the song plays every time without a decision. The device is the distribution. The format is the mechanism. The install is the legacy. When I think about what I want the things I build to do, it's not "get praised." It's not "win the award." It's: end up on enough devices that it starts completing things for people. That it loads before they've had time to decide. That someone three years from now can't tell you when they started using it, because it's been load-bearing long enough that the install date doesn't register anymore. {/* Fig 2 - looping device grid, files spreading across, refined retro System 7, cream + 1-tone purple. */} The output folder is what survives I spent a long time charging for the hours. Which sounds reasonable until you think about it from the other side. The client doesn't experience the hours. They experience the file. The deliverable. The thing they put in a folder and reference six months later when the person who commissioned it has moved on. The 2am call where I figured out the real problem. The three rounds of direction before the brief got tight. The rough version I had to make before I could make the right version. None of that is in the folder. None of it travels. The thing that travels is the output. I had a project once where I spent the better part of a week on the front half of the process and a focused afternoon on the actual deliverable. The client never knew. Why would they? What they received was an afternoon of value. What they kept was an afternoon artifact. The rest existed only in my working files, and working files don't travel. This is not a complaint about clients. It's a correction to how I was thinking about what I was selling. Once I understood that the output is what survives, I stopped centering the engagement on the path to it. The deliverable became the thing I designed the work around, not the thing at the end of it. The brief got written backward from the output folder: what's in it, what does it need to do once I'm not in the room, what format does it need to be in to travel past this job? The hours are the overhead. The folder is the product. You can love the process and still price the output. I do. The 2am thinking is where the real work happens. But no one is buying my thinking. They're buying the thing my thinking makes. And the thing my thinking makes is the thing that earns a life past the invoice. {/* Fig 3 - looping folder graphic, working files shake in private pane, polished output slides into delivered folder, refined System 7. */} The line you can't get out of your head is the line that earned a life. Not because it was the sharpest writing. Not because the production was the cleanest. Because it got on enough devices, early enough, and stayed. The brain that kept replaying it didn't choose to. That's the signature of something that genuinely installed. The question isn't whether something is good. The question is: what's in your output folder right now that someone, somewhere, can't get out of their head? What did you ship, in a format that could travel, on a day someone needed it? That's the thing with a life past your invoice. I name my work like a file format on purpose. `.PushingSquares` isn't a brand. It's a bet that something is worth installing. I've been making that bet for a while now. Some of the bets paid off. Some didn't. The ones that did ended up on devices I'll never count. I wrote up the doctrine over on Pushing Squares if you want the systematic version. Or keep making files. Either way. {/* Fig 4 - looping `.PushingSquares` icon dragged onto a device row, refined System 7. */} Make more files. Get them on more devices. That's the whole game. --- ## Every session is an audition URL: https://aris-space.com/documents/workflows/empower-claude-sessions-as-auditions Date: 2026-05-04 # Every session is an audition Here's the problem nobody talks about with AI workflows: every session starts from scratch. You open a new chat. The model doesn't know what you built last Tuesday, what patterns you've landed on, what approaches blew up in your face three sessions ago. You brief it again from the top. You re-explain the context. You rebuild the same one-off script you've needed four times this month, by hand, because there's no mechanism to turn a repeated fix into a permanent part of your setup. Most sessions complete a task and die. The system doesn't get smarter. It gets used. ## The cold-start problem I've been building with AI seriously for over a year. And for most of that year, I had a leaky bucket. Every time I sat down with a new session, I'd burn the first twenty minutes re-establishing context. Explaining my voice rules. Reminding it how I handle edge cases. Rebuilding a small utility I'd already built twice before because I hadn't formalized it. **Strong reasoning was getting lost.** Repeated failure modes were getting rediscovered ad-hoc. My memory system captured facts, but it wasn't promoting workflows into infrastructure. The sessions were doing their jobs, technically. They weren't leaving anything behind. {/* Fig 1 - leaky-bucket loop. Fresh chats opening empty, no inheritance. Refined retro System 7. */} ## The mindset shift The line that cracked this open for me: > "Don't do the task. Build the workflow that does this task and every future one like it." That's the shift. Not "complete this thing" but "notice whether this thing is repeatable, and if it is, build the infrastructure that handles it permanently." Most sessions are one-off in practice. But a lot of them don't have to be. When I noticed I'd done the same operation three times in three separate sessions, that was a signal. Not only "this could be a script" but "this should already be a script, and the fact that it isn't is a workflow problem, not a task problem." **Sessions don't get re-summoned. But they can leave inheritance behind.** {/* Fig 2 - task vs workflow. Single stamp vs row of stamps. Refined retro System 7. */} ## Sessions as auditions I started thinking about every session I run as an audition, not for the model to earn a future contract, but for the work itself to earn a permanent place in the system. The question a session should ask on the way out isn't "did I complete the task?" It's: "did I leave the system smarter than I found it?" A sharp session recognises a repeatable pattern. It builds the permanent fix in isolation, so nothing reaches the live setup until I've reviewed it. Then it surfaces one line back to me in chat: *"I noticed X, found a better way. The system just got an upgrade."* That's the success moment. Not a transcript, not a report. One line. Green-light or kill. ## Two trigger surfaces There are two kinds of signal I've learned to watch for. **Repeated tasks.** If the same operation has happened three or more times, it shouldn't be manual anymore. The session that spots it is the one that ships the fix. **Recurring failure modes.** Different executors have different blind spots. Patterns I keep re-correcting are patterns that belong in a guardrail, not a re-prompt. The session that discovers a new failure mode is the one that encodes it permanently. Both of these are inheritance opportunities. The session doesn't have to act on them in every case. But it should notice them and ask whether they're worth formalizing. {/* Fig 3 - pattern detect. Three events, marquee selection, ship? prompt. Refined retro System 7. */} ## The reversibility floor This only works if the floor is solid. Anything shipped this way lands as an isolated, reversible change. Not a tangled-up commit. Not a sprawling refactor. One artifact, one commit. If it ships wrong, undoing it is a single operation. The artifact moves to a trash folder rather than getting deleted. The record stays. That reversibility is what makes auto-accept safe for genuinely low-stakes changes. Without it, every proposed upgrade would need manual review, which defeats the point. **You can be aggressive about shipping improvements if the undo is clean.** Build the workflow, not the workaround. {/* Fig 4 - one-commit undo. Artifact slides staging to live to trash, ledger preserved. Refined retro System 7. */} ## What this changes The output of every session now has two layers. The first layer is the thing I asked for. The task, the content, the feature, whatever. That doesn't change. The second layer is inheritance. Did this session spot something repeatable? Did it build the fix, or at least flag the opportunity? Did it leave the system in a better state than it found it? A session that scores on both layers is the kind of session worth having every day. A session that only scores on the first is a session that got the work done but didn't do the work of the work. **Every session is an audition.** Not for the model's job security. For the infrastructure that the next hundred sessions will inherit. I noticed the pattern, built the fix. The system just got an upgrade. // --- ## Cinematic prompt methodology, as an installable Claude workspace URL: https://aris-space.com/documents/workspaces/pushing-creation Date: 2026-05-04 import { Diagram, Code, Video, Download, Fidget, Pullquote, InstallRitual, BrainstormFlow, ProjectFormat, SiblingMap } from '@/components/blocks' Three commands. That's the full install. Clone the repo, step inside, and Claude picks up the workspace on its own. No config files to edit, no environment variables to set. # Cinematic prompt methodology, as an installable Claude workspace Most AI image work fails at the brief, not the model. Three lines in. Generic out. People blame the tool. I shipped a fix. **pushing-creation** installs into Claude. Drop reference images into `refs/`. Run `/frames-brainstorm`. Claude reads your refs, runs a DP-style interview, and writes the style pack live as you answer. `/frames-shotlist` drafts the full storyboard. `/frames-shot` polishes individual frames. The brainstorm is where craft enters the pipeline. Claude reads your reference images, then asks the questions a director of photography would ask on a location scout. Your answers become the brief. Output is markdown. Drop it into PUSHING FRAMES, Midjourney, Sora, or any tool. Every project carries three artefacts. `style.md` holds the visual voice, locked down to lens choice, colour science, and negative space rules. `storyboard.md` is the shot table. `refs/` holds the images that seeded everything. → github.com/PUSHINGSQUARES/pushing-creation **pushing-creation** handles the methodology. **PUSHING FRAMES** handles generation. They're siblings, not dependencies. You can run either one standalone, or chain them for a continuous pipeline from brainstorm to final render. You don't get better output by trying harder at the prompt. You get better briefs by treating the model like a director of photography. Specificity transfers craft. Stop prompting. Start defining outcomes. // --- ## Anthropic Ships Claude Design. OpenAI Ships Pets. URL: https://aris-space.com/documents/thoughts-and-scribbles/the-taste-transition Date: 2026-05-05 The model is good enough now Whatever model you're using right now is plenty quick. Plenty smart. Plenty capable to do almost any job you actually need to do. Capability has been commoditising for eighteen months. The benchmarks climbed, then plateaued in the territory where the difference stops mattering for most work. Six months ago you needed the smartest model in the room. Today the smartest model in the room and the second-smartest are interchangeable for the job in front of you. Once that's true, capability stops being the question. The question becomes which is the right tool for the job. And that's a taste question. {/* Fig 1 - System 7 dropdown menu, refined retro. Menu titled MODEL. Items listed with checkmarks: CLAUDE OPUS, GPT-5, GEMINI 2.5, KIMI K2, GROK. Each item has a small "GOOD ENOUGH" tag on the right. Cursor arrow drifts up and down the list. Caption underneath: "the dropdown got boring." Loops. Cream + 1-tone purple. */} Both brands are proving taste Watch what the labs are shipping right now and you'll notice the same thing from two directions. Anthropic shipped Claude design. Identity, typography, layout, voice, the editorial spine the whole product runs on. The brand has a point of view and they're letting it carry the surface. OpenAI shipped pets. A floating overlay that follows your work. A `/pet` command. Custom personality presets. The brand is leaning into character, presence, attachment. Don't read these against each other. Read them together. Both companies are reaching for the same lever at the same moment. Both are signalling that capability isn't enough anymore. Both are competing on how the product feels. That's the story. Not which one is "better taste." That both of them, simultaneously, are admitting taste is now load-bearing. {/* Fig 2 - twin release-note panels reveal side by side, refined retro System 7. Left panel: ANTHROPIC, design-system specimens drop in (TYPE specimen, GRID specimen, PALETTE swatch, VOICE card, IDENTITY mark), each landing with a soft tick. Right panel: OPENAI CODEX, character accessories pop in (pet sprite, /pet, theme swatch, accent dot, font sample, personality dial), each landing with a soft tick. Both panels equal weight, no judgment. Caption underneath: "two release notes, both proving taste." Loops. Cream + 1-tone purple. */} Right tool for the job This is what taste actually is. Not minimalism versus maximalism. Not editorial versus playful. Not Anthropic versus OpenAI. Picking the right register for the right room, and committing to it. Anthropic's editorial register fits a power-user surface. People building, integrating, depending on the product to feel rigorous. A design system signals that. OpenAI's character register fits a wider surface. People who want presence, warmth, a thing on their desktop that feels like a companion. Pets signal that. Neither is wrong. They're aimed at different rooms. Picking which room you're in, and refusing to be a generic version of all rooms, is the work. That's the muscle that's about to matter most. {/* Fig 3 - twin specimen cards, refined retro System 7, equal visual weight. Left card titled EDITORIAL TASTE: type specimen, grid module, voice principle, identity mark. Right card titled CHARACTER TASTE: pet sprite, theme swatch, personality dial, accent palette. A small label beneath each card: "for power-user surfaces" / "for companion surfaces". Caption underneath both: "two flavours of the same lever." Loops slowly. Cream + 1-tone purple. */} What this means for everyone else If the labs are now competing on taste, the same thing is happening one layer down. To everyone using them. For years the question was: which model do I have access to? Then: which prompt do I use? Then: which tool do I use? Those questions are flattening. Everyone has access to good models. Everyone has access to good tools. Most of the friction that used to gate output is gone. When the friction is gone, what's left is the choice. Which job to do. Which register to do it in. Which thing to leave out. Which references to reach for. Which direction to refuse. That's taste. That's creative direction. That's the thing the model can't supply because it doesn't know what you're trying to make. In a world where AI gives you all the tools, your taste is the differentiator. To some extent. Not all of value collapses to taste; craft, distribution, relationships still matter. But the lever that just rotated for the labs is rotating for the rest of us too. The model can't tell you what to make. The prompt can't tell you what to make. Your judgment about what to do with all of it can. {/* Fig 4 - horizontal axis, refined retro System 7. Left end labelled CAPABILITY, marked SOLVED ENOUGH, filled in solid. Right end labelled TASTE, marked OPEN TERRITORY, mostly empty. A racing dot starts at the left and zips rightward. Below the axis, two parallel rows of small dots also moving rightwards: top row labelled THE LABS, bottom row labelled THE MAKERS. Both rows the same direction, slightly different speeds. Caption underneath: "the axis just rotated. For them. And for us." Loops. Cream + 1-tone purple. */} The takeaway The model is good enough now. The next leverage point isn't more capability. It's the judgment to use it well. Watch the labs prove this on themselves first. Then notice the same thing happening to your own work. Taste is the lever. For them. For us. --- ## Generate cinematic images and video from inside Claude URL: https://aris-space.com/documents/workflows/pushing-creation-frames-combo-unlock Date: 2026-05-08 import { InstallRitual, ProjectFormat, KeychainBridge, PipelineFlow, BrainstormFlow, Pullquote, Code, Diagram } from '@/components/blocks' The gap between Claude reasoning about images and Claude making them closed today. pushing-creation v0.3.0 ships a keychain bridge. Provider keys live in macOS Keychain, the CLI reads them at runtime, and the key value never enters Claude's context. Any Claude Code session in any workspace becomes a generation studio. Brief, image, video, end to end. ## The shift Before v0.3.0: author a brief in Claude, switch apps, paste the prompt, generate, switch back. Now: brief and generate in the same session. The mechanic is straightforward. macOS Keychain holds the key, encrypted at rest, scoped to your user account. Claude holds the brief. The CLI is the bridge between them. ## Install Three commands. Claude Code reads the `.claude/` directory on entry and activates the skill. `/frames-new my-shoot` scaffolds `projects/my-shoot/` with starter templates for `style.md` and `storyboard.md`. ## Add your keys to Keychain Add each provider key once using the `security` CLI that ships with macOS: ```sh security add-generic-password -U \ -s "pushing-creation:gemini" \ -a "$USER" \ -w "your-google-ai-studio-key" ``` When Claude calls `bin/frames-gen`, that key gets read into a Python variable inside the subprocess and passed straight to the provider's HTTP client. It never crosses into Claude's transcript, it isn't echoed to stdout, and it isn't logged by the CLI. The OS guarantees: encrypted at rest, scoped to your user, accessible only with your authorisation. The `-U` flag updates an existing entry rather than creating a duplicate. Run the same command with a new value to rotate a key. The full provider list with key formats for all seven providers is in [docs/KEYCHAIN_SETUP.md](https://github.com/PUSHINGSQUARES/pushing-creation/blob/main/docs/KEYCHAIN_SETUP.md). ## Author the brief `/frames-brainstorm` opens a DP interview. Claude reads your reference images from `refs/` and asks the questions a director of photography would ask on a location scout. Your answers become the brief. `style.md` gets written live as you respond. ## Generate Two commands from the same session: ``` /frames-gen --kind image --shot-n 1 /frames-gen --kind video --shot-n 1 ``` The first call reads shot 1 from `storyboard.md`, determines the provider from the shot's Provider column (or your workspace default), reads the key from Keychain, and writes `renders/shot-1.png`. The second does the same for video, writing `renders/shot-1.mp4`. Claude's only visible output is the saved path. The key bytes stay inside the subprocess. ## Where it lives Every project is four artefacts: a style pack, a storyboard, a reference folder, and a renders folder. ## The unlock Every Claude Code session in every workspace inherits this once pushing-creation is installed and the keys are in Keychain. CxN brief. PS product shot. BC live-shoot mood board. Personal portfolio. Same Claude, same methodology, same keys. Two repos clone once. From then on, every workspace is a generation studio. ## Provider status Three providers are verified end to end as of v0.3.0. **gemini** for image (Gemini 2.5 Flash). **openai** for image (GPT-image-1). **kling** for video (Kling v2 Master). The gemini provider also implements Veo 2 video, scaffolded but not yet verified in v0.3.0. Four other providers are scaffolded but not yet verified: openrouter, seedream, seedance, and imagen. The full verification matrix with key formats, model names, and known quirks is in [docs/PROVIDERS.md](https://github.com/PUSHINGSQUARES/pushing-creation/blob/main/docs/PROVIDERS.md). The methodology is the install. Once both land, the gap is closed. Stop prompting. Start defining outcomes. ## Repos [github.com/PUSHINGSQUARES/pushing-creation](https://github.com/PUSHINGSQUARES/pushing-creation) ships the methodology and the keychain bridge as a Claude Code skill. [github.com/PUSHINGSQUARES/pushing-frames](https://github.com/PUSHINGSQUARES/pushing-frames) is the local browser studio that reads the same project format. Own one or both. // --- ## Your Claude experience has two surfaces. Customise both. URL: https://aris-space.com/documents/workflows/claude-experience-two-surfaces Date: 2026-05-10 import { Diagram, Code, Video, Download, Fidget, Pullquote } from '@/components/blocks'
47% · opus-4.7 · WORKSPACE · main* · 2🛠 · 02:41
The interface I read every turn. Six fields, colour-coded, costs zero tokens.
Most people customise Claude in one place: the prompt. The two surfaces that actually shape every session, you ignore. **How Claude talks to you**, and **how you read what's happening**. Both are configurable. Both compound across hundreds of hours. The framework I run, and how to set it up:
Surface 1

Voice

{'~/.claude/CLAUDE.md'}

{'~/.codex/AGENTS.md'}

How Claude talks to you. Markers, header tiers, mono signals, paragraph length, where decisions live.

Surface 2

Interface

{'~/.claude/scripts/statusline.py'}

{'~/.claude/settings.json'}

How you read what's happening. Persistent, glanceable, colour-coded by zone.

Two surfaces. Both configurable. Both compound.
## Surface 1: The voice Claude has defaults. They're fine. They're not yours. I'm dyslexic. Walls of text are invisible to me. So my Claude has a non-negotiable response format, written into `~/.claude/CLAUDE.md`: 1. Every reply ends with a bold marker: `→ DECISION`, `→ QUESTION`, `→ NO DECISION NEEDED`. I know what's required of me in under three seconds of skimming. 2. Header tier = importance, not nesting depth. `#` is THE headline. `##` is a main section. `####` is an inline label. The size matches how load-bearing it is to read. 3. `` `mono font` `` is reserved for paths, values, commands. Never for emphasis. The font swap is a signal. 4. `---` between major pivots like status to decision. The horizontal rule is the unmissable section break. 5. Bold keywords inside sentences. Dyslexic eyes skim for bold anchors. 6. Absolute paths only, so cmd+click opens them from inside the terminal.
# THE headline of the reply (max 1)
## Main sections (status, decision, design, question)
### Sub-sections inside one of those
#### Inline labels and micro-groupings
Header tier = importance. The size matches how load-bearing the section is to read.
If you also use Codex, mirror the same rules to `~/.codex/AGENTS.md`. Two harnesses, one voice. ## Surface 2: The interface The Claude Code statusline runs once per turn, costs zero tokens, can render colour. Mine shows: ``` 47% · opus-4.7 · WORKSPACE · main* · 2🛠 · 02:41 ``` Six fields: context %, model, workspace name, branch + dirty flag, dispatch worker count, session clock. Colour-coded by zone. Context % goes green under 50%, yellow at 50-75%, red at 90%. Branch yellow when dirty, red on conflict. Workspace gets a brand colour mapped from the path I'm in.
47% · opus-4.7 · WORKSPACE · main* · 2🛠 · 02:41
47%  context: green <50, yellow 50 to 75, orange 75 to 90, red over 90
opus-4.7  model: opus magenta, sonnet cyan, haiku grey
WORKSPACE  per-prefix brand colour
main*  white clean, yellow dirty, red on conflict
2🛠  dispatch worker count: yellow when 4 or more
02:41  session clock, always dim grey
Six fields, six colour rules. State encoded in colour, not just decoration.
The 50% threshold matches the rule already written into my voice config: write a session handoff at 50% context. Now I can see the threshold without asking. ## How to set this up 1. **Customise the voice.** Open `~/.claude/CLAUDE.md`. Write your own rules. Mine took an afternoon to draft and three weeks of iteration to lock down. Yours will start ugly. That's fine. 2. **Mirror to AGENTS.md.** If you use Codex, write the same rules to `~/.codex/AGENTS.md`. Same instructions, two harnesses. 3. **Build a statusline.** A Python script reads CC's stdin JSON, prints a colour-coded line, exits. Wire into `~/.claude/settings.json` as `statusLine.command`. The fields you pick are the ones you check constantly. Yours will differ from mine. ## The principle Claude doesn't come to you tuned. The defaults are a shape that fits no one in particular. The work of making her useful for **your** brain is two-surface work: the language she uses, and the interface you use to read her. Do both. Compound for years. {/* TODO before publishing the downloads section: 1. Sanitise statusline.py — replace SHADOW-specific paths with env-var override + sensible defaults; ship a minimal version. 2. Generate workspaces.toml.example with anonymised paths. 3. Write claude-md-template.md with [PERSONALISE] placeholders. 4. Write install.sh that symlinks the script + patches ~/.claude/settings.json. 5. Drop all four into /public/posts/workflows/claude-experience-two-surfaces/, restore the downloads frontmatter array, append blocks at the bottom. */} --- ## Every stage gets its own folder URL: https://aris-space.com/documents/workflows/every-stage-its-own-folder Date: 2026-05-12 import { Diagram, Code, Video, Download, Fidget, Pullquote, FolderExplorer } from '@/components/blocks' Ask AI for the final output and it almost works. Then you need a change, and you rerun the entire thing. I break every workflow into stages where each stage's output becomes the next stage's input. Video looks like this: 1. Write the prompts → QC the prompts 2. Generate images from the prompts → QC the images 3. Generate clips from the images → QC the clips 4. Write the script over the clips → QC the script 5. Collate into the final cut Every gate is a folder. Every folder is recoverable. If the script's wrong, I don't regenerate clips. If a clip's wrong, I don't rewrite the prompt. The system around the AI is the intelligence. The folder structure is the system. The cost of going back becomes the cost of one stage, not the cost of one workflow. --- ## Privacy Policy URL: https://aris-space.com/documents/privacy Date: 2026-05-16 **Ari Leavesley ("Pushing Squares")** Version 2.3 / Effective 5 August 2026 https://pushingsquares.com --- > **Policy update, 5 August 2026.** Version 2.3 activates consent-gated PostHog analytics and session replay after Accept on the cookie banner. Reserved analytics wording from 2.2 is retired. This notice stays on this page until 4 September 2026. --- ## 1. Data Controller (Art. 4(7), Art. 13(1)(a)) The controller responsible for the processing of your personal data is: **Ari Leavesley**, trading as Pushing Squares United Kingdom (sole trader; no registered company) Privacy contact: [ari@pushingsquares.com](mailto:ari@pushingsquares.com) **Data Protection Officer (Art. 37):** None appointed. The scale and nature of processing on this site does not meet the Art. 37(1) thresholds for mandatory DPO designation. --- ## 2. Scope This policy describes how Ari Leavesley processes personal data when you submit a qualm via this site, accept the cookie banner, or otherwise interact with pushingsquares.com or aris-space.com. It applies to all data subjects whose personal data is processed in connection with the site. --- ## 3. Personal Data Collected (Art. 13(1)(c), Art. 14) **Categories of data subjects** - Qualm submitters - Website visitors - SFL download subscribers **Categories of personal data** | Category | Specific items | |---|---| | Contact data | Email address you enter on the qualm form | | SFL signup data | Email address, consent flag, source page, timestamp of signup | | Submission content | Title and body text you write | | Uploaded files | Any files or images you attach, and the contents of those files | | Third-party data inside uploads | Names, faces, addresses, or messages of other people that appear in your screenshots, recordings, or documents (see warning below) | | Technical data | Salted hash of your IP address (not the raw IP), user-agent string | | Consent records | Timestamp of consent given, value of the `aris_consent` cookie | | Analytics (with consent only) | Anonymous PostHog events and page views. No autocapture, no IP retention, no cross-site identifiers. | **Sources (Art. 14(2)(f))** - Directly from you, via the qualm submission form, the SFL download form, and the cookie banner - From your browser, in the case of technical data and analytics events **Third-party personal data in uploads.** If a file you upload contains other people's personal data, Ari becomes a controller for that data too. Please redact names, faces, addresses, and messages that aren't relevant before uploading. If someone identifiable in an upload contacts Ari directly, their data will be deleted on request regardless of the underlying retention schedule. **Special category data.** Please do not upload special category data within the meaning of [Art. 9 UK GDPR](https://www.legislation.gov.uk/eur/2016/679/article/9) (health, racial or ethnic origin, political opinions, religious beliefs, trade union membership, genetic data, biometric data, sex life or sexual orientation). If special category data is received unsolicited, it will be deleted on sight and not used for any editorial purpose. --- ## 4. Purposes and Legal Bases (Art. 6, Art. 13(1)(c)–(d)) | # | Purpose | Data categories | Legal basis | Retention | |---|---|---|---|---| | 1 | Receive and read your qualm submission | Email, title, body, uploaded files | **Consent** (Art. 6(1)(a)) | Email, title, body: 12 months from last contact, then deleted. Uploaded files: 30 days after a related post is published, or 12 months from submission, whichever sooner. | | 2 | Email follow-up (clarifying questions; notify you when a related post goes live) | Email, title, body | **Consent** (Art. 6(1)(a)) | Same as row 1 | | 3 | Use qualm content (anonymised / no identifying details) as raw material for public posts | Title, body, uploaded files | **Legitimate interests** (Art. 6(1)(f)) — see LIA below | As long as needed for the editorial output; not republished after deletion of the source qualm | | 4 | Publish a post that names or identifies you | Email, name, any identifying details you agree to | **Consent** (Art. 6(1)(a)) — separate, explicit, in writing | For the lifetime of the published post | | 5 | Detect and block abusive or automated submissions; investigate misuse | Salted IP hash, user-agent string | **Legitimate interests** (Art. 6(1)(f)) — see LIA below | 90 days, then deleted | | 6 | Bot challenge to prevent automated form abuse (Cloudflare Turnstile) | Turnstile token; signals processed by Cloudflare | **Legitimate interests** (Art. 6(1)(f)) | Processed by Cloudflare per its DPA; not retained by Ari | | 7 | Admin access control (Cloudflare Access) | Admin identity credentials (not visitor data) | **Legitimate interests** (Art. 6(1)(f)) | For the duration of admin access | | 8 | Operate the site (hosting, edge delivery via Vercel) | Standard web request metadata | **Legitimate interests** (Art. 6(1)(f)) | Per Vercel's processor retention | | 9 | Anonymous analytics and session replay | Anonymous events, page views, session replay | **Consent** (Art. 6(1)(a)) only after Accept on cookie banner | **Active after Accept.** PostHog loads only when you accept. No autocapture of form fields, no IP retention, no cross-site advertising identifiers. Session replay masks inputs. Deletion on request within 30 days. Decline keeps analytics off. | | 10 | Demonstrate consent under Art. 7(1) | `aris_consent` cookie value (and a matching local preference) | **Legal obligation** (Art. 6(1)(c)) | As long as the related qualm or cookie choice exists | | 11 | Deliver the SFL download and send occasional product emails about SFL and related tools | SFL signup data | **Consent** (Art. 6(1)(a)); given by checkbox at the point of download | Until you ask to be removed, then deleted within 30 days | **Withdrawal of consent (Art. 7(3)):** You can withdraw consent at any time by emailing [ari@pushingsquares.com](mailto:ari@pushingsquares.com). Withdrawal does not affect the lawfulness of processing carried out before withdrawal. Withdrawal is processed within 30 days. ### Legitimate interests assessments (Art. 6(1)(f)) **Row 3 — Editorial use of qualm content for public posts.** - *Interest:* Running a useful public knowledge resource that helps others solve the same problems. - *Necessity:* Real submissions are the only authentic source of the problems written about; synthetic or aggregated data would not serve the editorial purpose. - *Balancing:* No name, email, file contents, or identifying screenshots are published without separate explicit written consent (row 4). Submitter expectations are managed by prominent consent language at point of collection. Minimal risk of harm given that nothing personally identifying ever leaves the editorial filter without a second consent event. **Row 5 — Spam and abuse prevention.** - *Interest:* Maintaining the integrity of a public submission form. - *Necessity:* Some signal is required to detect repeat abuse; pseudonymised IP (salted hash) is the minimum effective. - *Balancing:* IP is hashed, never stored raw. Retained 90 days only. No cross-site identifiers. Low impact on the data subject. **Rows 6–8 — Bot challenge, admin gating, hosting.** - *Interest:* Operating a secure, available site. - *Necessity:* Each service performs a function that cannot reasonably be performed without it (bot challenge, admin authentication, hosting). - *Balancing:* Each processor operates under an Art. 28 DPA. Data passing through is the minimum needed to perform the function. Low impact on the data subject. --- ## 5. Recipients of Personal Data (Art. 13(1)(e), Art. 28) Personal data is processed on Ari's behalf by the following processors, each under a written data processing agreement that meets the requirements of Art. 28 UK GDPR. | Recipient | Role | Purpose | Country | |---|---|---|---| | Vercel Inc. | Processor (Art. 28) | Hosting and edge delivery; receives the qualm form submission and serves the site | United States | | Neon Inc. | Processor (Art. 28) | Postgres database; stores submission text | United States (US-East) | | Cloudflare, Inc. | Processor (Art. 28) | Object storage (R2) for uploaded files; bot challenge (Turnstile); admin access gating (Access); D1 database storing the SFL signup list (EU region) | United States / North America | | PostHog Inc. | Processor (Art. 28) | Anonymous analytics; loads only after cookie consent | United States | Personal data is not shared with anyone outside these processors except where required by law or with your explicit prior written permission. **What is not done with your data:** - Submissions are not used to train AI models. - Data is not sold. - Data is not used for advertising. --- ## 6. International Data Transfers (Chapter V, Art. 44–49) All four processors above are based in the United States. Transfers from the UK rely on the **UK Extension to the EU-U.S. Data Privacy Framework** (the "UK-US Data Bridge") for processors that are certified, supplemented by Standard Contractual Clauses where appropriate. | Recipient | Country | Mechanism | Verified at | |---|---|---|---| | Vercel | United States | [UK Extension to the EU-US Data Privacy Framework](https://www.dataprivacyframework.gov/) (DPF-certified) + SCCs as fallback | [Vercel DPF compliance](https://vercel.com/docs/security/compliance) | | Neon | United States | [UK Extension to the EU-US Data Privacy Framework](https://www.dataprivacyframework.gov/) (DPF-certified) | [Neon DPA & GDPR statement](https://neon.com/blog/gdpr-compliance-and-neon) | | Cloudflare | United States | [UK Extension to the EU-US Data Privacy Framework](https://www.dataprivacyframework.gov/) (DPF-certified) + SCCs | [Cloudflare and GDPR compliance](https://www.cloudflare.com/trust-hub/gdpr/) | | PostHog | United States | [UK Extension to the EU-US Data Privacy Framework](https://www.dataprivacyframework.gov/) (DPF-certified) + SCCs | [PostHog DPA](https://posthog.com/dpa) | A transfer impact assessment has been conducted with reference to each processor's published security and disclosure posture. You may request a copy of the safeguards relied on by contacting the address in Section 1. --- ## 7. Retention (Art. 5(1)(e), Art. 13(2)(a)) Personal data is retained only for as long as necessary for the purposes described in Section 4. Specific periods are listed in the table in Section 4. Where a basis is consent, you can request earlier deletion at any time and it will be actioned within 30 days. --- ## 8. Your Rights (Art. 12–22, Art. 77) Subject to the conditions in UK GDPR, you have the following rights: - Right of access (Art. 15) - Right to rectification (Art. 16) - Right to erasure / "right to be forgotten" (Art. 17) - Right to restriction of processing (Art. 18) - Right to data portability (Art. 20) - Right to object (Art. 21) - Right not to be subject to a solely automated decision (Art. 22) - Right to withdraw consent at any time (Art. 7(3)) - Right to lodge a complaint with a supervisory authority (Art. 77) To exercise any of these, email [ari@pushingsquares.com](mailto:ari@pushingsquares.com). Responses are provided within 30 days. --- ## 9. Automated Decision-Making and Profiling (Art. 22) No solely automated decision-making, including profiling, that produces legal effects or similarly significant effects is carried out. --- ## 10. Cookies and Similar Technologies **Consent record.** The cookie banner sets **`aris_consent`** (`accepted` or `declined`) for one year, plus a matching browser preference so the banner stays dismissed. That cookie is strictly necessary to operate the consent mechanism and is set under [PECR Reg. 6(4)](https://www.legislation.gov.uk/uksi/2003/2426/regulation/6). **Necessary service cookies.** Sign-in (Clerk) and checkout (Stripe) set their own session/security cookies only when you use those features. They are not advertising trackers. **Analytics.** After you choose Accept on the cookie banner, optional PostHog analytics and session replay load for product improvement. Decline keeps them off. No autocapture of form fields, no IP retention, no cross-site advertising identifiers. Session replay masks form inputs. You can change your choice at any time by clearing site cookies (and site data) in your browser and reloading the page. --- ## 11. Changes to This Policy The version and effective date at the top reflect the latest revision. Material changes will be communicated via a banner at the top of this page for 30 days. --- ## 12. Contact and Complaints (Art. 77) Questions or complaints about this policy: [ari@pushingsquares.com](mailto:ari@pushingsquares.com). You also have the right to lodge a complaint with a supervisory authority. The lead supervisory authority for this site is the **Information Commissioner's Office (ICO)**, [ico.org.uk](https://ico.org.uk). --- *End of policy / version 2.3, effective 5 August 2026.* --- ## The brainstorm is the build URL: https://aris-space.com/documents/discipline-and-process/the-brainstorm-is-the-build Date: 2026-05-17 # The brainstorm is the build If your AI keeps confidently building the wrong thing, the bug isn't in the model. It's in the gap between what you asked for and what done looks like. Every frustrated "the agent doesn't get it" I've watched in the wild traces back to the same source. Not the model. The brief. The brief was a wish, not a definition. The agent guessed at the parts the brief didn't pin down, and the guesses were wrong. The fix isn't a smarter model. It's a brainstorming discipline you do *with* the model before any code gets written. I encoded mine as a skill the agent runs on itself. It's standalone and free. You can install it in about thirty seconds. ## The bug nobody calls a bug Watch what happens when someone tells an agent "build me a CLI to archive old files." A capable agent will start writing. It will pick a language. It will pick where the archives go. It will pick what "old" means. It will pick whether the threshold is configurable. Every one of those is a decision the human should be making, and the agent is making them silently because nothing in the prompt told it not to. By the time the human reads the output, they're not reviewing a design. They're reviewing four decisions and a script. They push back on one of the decisions and the agent rewrites the whole thing. The script becomes a referendum on choices that should have been resolved in the brief. The thing that's broken isn't the agent's coding. It's the missing step before the coding. ## Brainstorming isn't a vibe, it's a method The version of brainstorming most people do with AI is a vibe. A loose chat to "explore the idea" before the real work starts. The output is a hand-wave. The version that works is a discipline. Nine steps, one rule that does most of the work, and one hard gate that makes the rest of it possible. The output is a spec document that lives in your repo, with the human's signature on it. When this is in place, three things change: The disagreements surface early. Changing direction costs five minutes instead of five hours. The model stops guessing. The spec exists. Anything not in the spec is explicitly out of scope. You catch your own bad assumptions out loud. That's the only way you ever catch them. ## The walker Click each step to flip it. The flip shows the rule, plus the specific anti-pattern that step exists to prevent. Try to drag one out of order. ## The one rule that does the most work > One question per message. Not "tell me about your project." One specific clarifying question, multi-choice when possible. Wait for the answer. Ask the next one. This is slow. It is slow on purpose. Every batched question burns context. It also lets the answer to question one shape the answers to two and three before you've had a chance to consider them in isolation. The cost of a batched question isn't the time it saves. It's the answers you give that you'd have given differently if the questions had been separated. Slow at the gate, fast through the build. ## The hard gate After step 5, the agent is forbidden from writing code, scaffolding files, invoking implementation skills, or doing anything past "present the design." It can only continue if you say "approved." The gate is the whole reason the rest works. Without it, every previous step is theatre. The agent will brainstorm with you, draft a beautiful design, then immediately ignore it and build whatever it was already going to build. The hard gate makes the design load-bearing. The human's "approved" is the only key. ## What this skill doesn't do It doesn't write code. It doesn't pick frameworks. It doesn't generate tests. The terminal state is the approved spec plus an implementation plan, both written to disk. Implementation happens in a separate session against the written plan. That separation is the point. The implementer reads the spec cold and builds against a written agreement, not a half-remembered chat. The brainstorming session does its job, writes its artefacts, and ends. ## How to install it The skill is one folder. Four markdown files plus a small Node.js script for the optional visual companion. No package manager. No external services. No telemetry. No sibling skill dependencies. For Claude Code at the user level, drop the folder at `~/.claude/skills/brainstorming/`. That's the whole install. The full INSTALL.md inside the zip covers Cursor, generic LLM use, and the visual companion. ## The visual companion If your upcoming questions are layouts, mockups, or side-by-side designs, the skill can launch a small localhost server that watches a directory for HTML mockups and serves the newest one to your browser. You click options in the browser, the agent reads the click events on its next turn. Per-question decision, not per-session. The skill uses it only when "would the human understand this better by seeing it than reading it?" is yes. Conceptual questions stay in the terminal. The companion is bundled in the zip; nothing to install separately. ## The takeaway The model isn't the bottleneck. The brief is. Fix the brief and the rest gets out of the way. The brainstorm is the build. Everything after it is execution. --- ## The model is the replaceable part URL: https://aris-space.com/documents/tools-and-plugins/the-model-is-the-replaceable-part Date: 2026-05-19 # The model is the replaceable part If you switch LLM and you have to rebuild your stack, the LLM was never the asset. The thing you had to rebuild was. I run my coding workflow across three different AI tools. Claude Code, Codex CLI, Kimi CLI. Three different models. Three different runtimes. One toolkit. I want to pick the model that fits the task in front of me without rebuilding anything to switch. That used to mean three versions of every capability, each drifting away from the others by Wednesday. Now it's one definition that all three follow. This post is the pattern that fixed it. ## What "locked in" actually means People talk about model lock-in like it's a billing problem. It isn't. It's a structural problem. Lock-in is when the work you've done assumes one specific model on the other end, so changing the model means redoing the work. Most "AI tooling" you build incrementally has this shape by default. You sit inside Claude. You write a Python script that calls the Anthropic SDK. You build a prompt template tuned to Claude's idioms. You create a workflow that depends on a tool name only Claude exposes. None of it asked to be Claude-specific. It just is, because you happened to be in Claude when you wrote it. The day you want to do the same task in another harness, you have two choices. Rewrite for the new SDK. Or accept the capability doesn't exist there. I rewrote. Then I rewrote again. Then I forgot which version was the canonical one. Each port drifted. The version I built second was always slightly behind the one I built first. Two panels: on the left, three capability boxes funnel into a single CLAUDE bubble while GPT and KIMI sit greyed out. On the right, a CONTRACTS / MEMORY / CLIs stack fans out to three equal CLAUDE, GPT, KIMI model boxes. That's the mistake. The model isn't supposed to be the centre of your stack. The contracts you give the model are. ## The three layers that fix it Once I worked through it, the pattern came out as three rules. They're boring on purpose. The whole point is that they're things you can build incrementally without learning anything exotic. ### 1. Markdown is the contract A capability is a markdown file. The model reads it and follows it. Not a Python function calling an API. Not a model-specific prompt buried in code. A document that says: here's what to do, here's the format, here are the anti-rules. Any model that can read English can run it. Claude has its own way to discover the file. Codex has another. Kimi has another. All three read the same file when pointed at it. The file is the contract. The harness is just how it gets opened. This is the most counterintuitive part of the pattern for engineers, because the engineer's instinct is to wrap things in code. Wrapping it in code is what makes it model-specific. Leaving it as a document is what makes it portable. ### 2. Files are the memory Long-term context lives in shared markdown on disk at a stable path. Any tool, any model, any session, reads the same files. When I learn something about how I work (a preference, a recurring mistake to avoid, a belief about how a project should run), it goes into a memory file. When the next session starts, whatever harness I'm in, that session loads the same context. The memory doesn't know which model is reading it. It doesn't need to. The price of this is discipline about the format. Every memory file has the same frontmatter shape. Every entry has the same fields. The benefit is a single source of truth that survives every model swap and every harness migration. ### 3. CLIs are the tools Anything that needs deterministic execution (search, similarity, embeddings, transformations) is a command-line program. Models shell out. A model can't reliably compute cosine similarity. A Python script can. So the script lives at the shell, the model invokes it with arguments, and gets JSON back. The model handles judgement. The script handles math. Both layers are model-agnostic by construction. A three-tier stack labelled BEHAVIOURS / MEMORY / TOOLS. Tags on each layer read 'markdown contracts', 'files on disk', 'CLIs · shell-callable'. Below the stack, four model boxes (CLAUDE, GPT, KIMI, plus a dashed-outline placeholder for the next model) are connected upward with dashed lines, captioned 'reads'. ## What this buys you Once the toolkit is portable, the model becomes a knob, not a foundation. You're not choosing one model and building your life on it. You're choosing the right model for the task in front of you, and the toolkit you use to express the task doesn't care. Hard reasoning task? Reach for the biggest model. Mechanical refactor across forty files? Reach for the cheapest fast one. Need to read a hundred-thousand-line transcript? Reach for whichever has the longest context window today. Same capabilities every time. No port. No drift. No "I'll re-add that feature when I get around to it." A single shared toolkit box at the top labelled CONTRACTS · MEMORY · CLIs. A connector fans out to four task boxes: Hard reasoning, Mechanical work, Long context, Quick draft. Each task box arrows down to a different model: OPUS, HAIKU, KIMI K2, SONNET. Tagline: 'choose by task · swap any time · no rewrite'. The shape of the choice changes. It stops being "which model do I commit to?" and starts being "which model serves this turn?". Those are very different questions and they produce very different working habits. ## The anti-pattern this kills > Vendor SDKs as your primary interface. Every time you wrap your capability in `import anthropic` or `import openai`, you've built a model-specific abstraction. It will work beautifully right up until the moment you want to switch. I'm not saying never use the SDKs. I'm saying don't let them be the surface your capabilities are defined against. The SDK is fine as an internal detail of one specific tool. It's a problem as the place where the behaviour lives. The portable version doesn't import anything from the model vendor. It writes a markdown file. The vendor is whatever happens to be reading the file that session. ## The one rule that does the most work > Build the interface, not the integration. An integration ties you to one vendor. An interface accepts any vendor that can meet its contract. Markdown contracts, files, and CLIs are all interfaces. SDKs are integrations. When in doubt, lean interface. Even when the integration is more ergonomic today. Even when "you're only using one model anyway, why bother." The cost of writing it as an interface is small. The cost of unwinding an integration after it's grown roots is enormous. ## What it doesn't promise This isn't model-agnostic in the sense that every model is equally good at every task. They aren't. Claude reasons differently from GPT differently from Kimi. Each has things it's better at and things it's worse at. What this pattern gives you is the freedom to pick the best one for the job without throwing away your work. The capability is portable. The choice of model is still a judgement call. You just don't pay the rebuild tax anymore. You also still need taste. The toolkit being portable doesn't mean every task should be run on every model. You're still making real engineering choices about which model belongs where, in the same way you'd make choices about which database belongs where. The point is the choice is reversible. ## How this changes the way you build A few practical knock-ons once you've adopted the pattern: You stop reading "model X just released" announcements as a threat or a chore. You read them as "could be a new option for the knob." The release doesn't invalidate your toolkit. It expands the set of models that can plug into it. You stop optimising your prompts for one model's quirks. You optimise the contract for clarity instead. A clear contract reads well in every model. A model-specific quirk-prompt reads weirdly in the others. You stop fearing the cost surprise from any single vendor. If one model gets too expensive for a task, you reach for a cheaper one and the toolkit doesn't notice. You stop equating "which AI tool I use" with "which way I work." You can switch harnesses freely and your workflow follows you. ## The takeaway The model is the replaceable part. Your contracts are the asset. If your toolkit can't survive a model swap, you don't have a toolkit. You have a vendor relationship. Build the interface, not the integration. // --- ## A second brain for taste, not for notes URL: https://aris-space.com/documents/tools-and-plugins/lens Date: 2026-05-21 import { LensFidget } from '@/components/blocks/LensFidget' # A second brain for taste, not for notes Creative reference libraries have a rot problem. You save references. You forget them. Your aesthetic exists somewhere between your eyes and your past work. It's not a document anyone can query. So you go to brief a workspace. A collaborator. A process. And you're re-explaining your visual sense from scratch. Every time. The fix isn't a better folder structure. It's distillation. Take the reference, extract the principle, throw the reference away. ## Two streams There's a hard line between two things most people mash together.
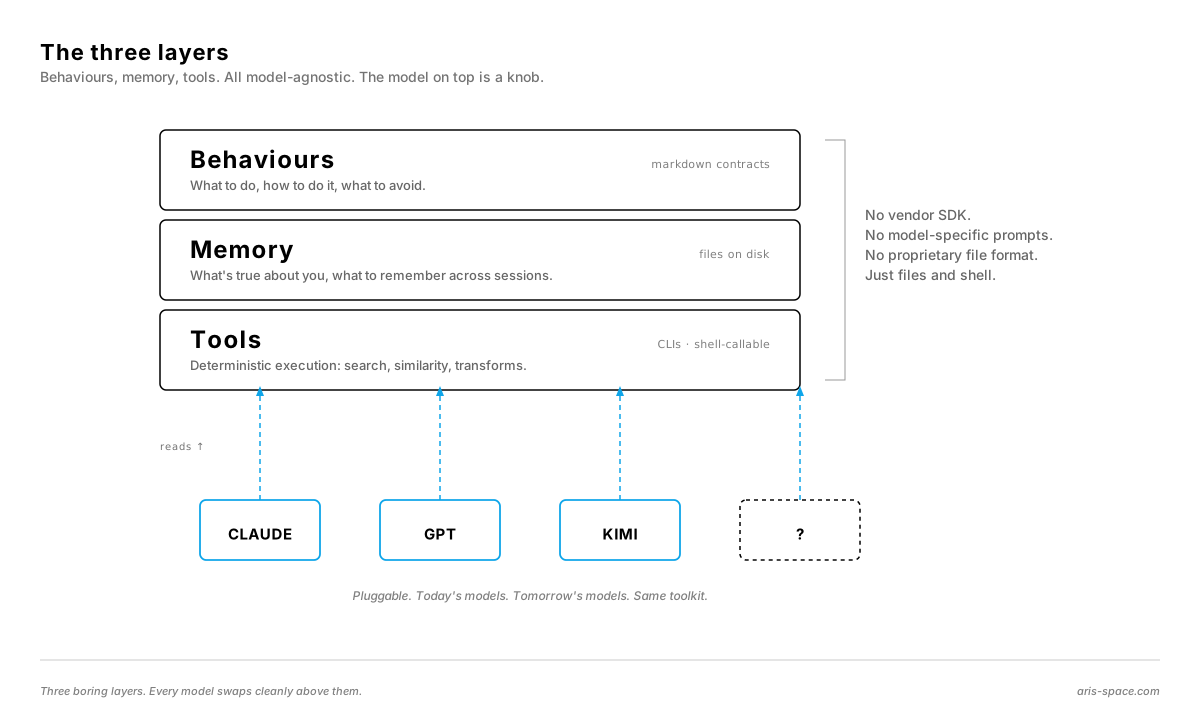
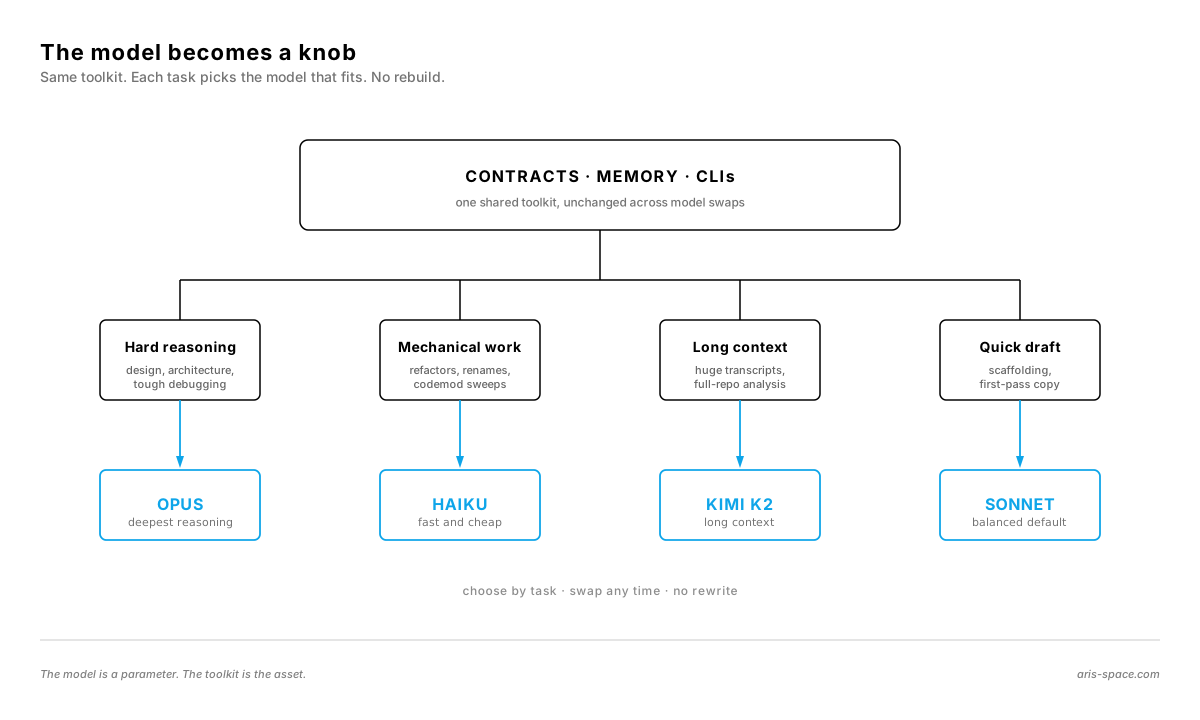
Two streams: Trend Cards and DNA Profiles Two System 7 windows side by side. Left window titled TREND CARDS shows three stacked card rows with example slugs. Right window titled DNA PROFILES shows two portrait-frame profile rows. A diagonal-hatched column labelled DO NOT MIX separates them. {/* Left window: TREND CARDS */} TREND CARDS Direct flash Feels unapologetic, raw, human Cold open Withholds orientation Maximalism Density as compositional force more cards... EXTERNAL REFS → DISTILLED {/* Divider: DO NOT MIX */} DO NOT MIX {/* Right window: DNA PROFILES */} DNA PROFILES Portraiture 24 anchored claims Lighting · palette · what I reject Editing 18 anchored claims Rhythm · structure · what I reject more profiles... OWN CORPUS → PROFILED
Two streams. Never mash them.
**Trend cards** come from external references. Images, films, reports, frames that caught your eye. Each card distils one into an atomic, opinionated document. The shape is fixed. A thesis sentence first. Something like "direct flash feels unapologetic, raw, and human." Then operative moves: how to deploy it. Then failure modes: how it goes wrong. Then tooling notes. Then sources. That's the whole anatomy. Not a mood board. Not a folder of saved images. A context block you can hand to any process and trust. They answer: what's in the current visual landscape, and how do I use it? **DNA profiles** come from my own corpus. Not references. My own library of finished work. Each profile maps what I consistently do. Lighting tendencies. Palette bias. What I reject. Signature moves. Every claim cites a real anchor example. A profile doesn't say "I favour hard light." It says "I favour hard light. Anchor: the portrait set with the unbroken key, no fill." A claim without an anchor is a vibe. A claim with an anchor is a contract. They answer: what does my work look like when it sounds like me? Don't mash them. One tracks the world. One tracks the self. ## Four stages The pipeline runs in four stages.
The four stages: Ingest, Distill, HALT Gate, Publish and Index Four System 7 windows arranged in a horizontal flow, connected by thick black arrows. INGEST leads to DISTILL, which leads to HALT GATE, the largest window styled as an alert dialog with Approve and Reject buttons. HALT GATE leads to PUBLISH and INDEX. An upward annotation arrow below HALT GATE reads: thesis sentence required. {/* INGEST */} INGEST Hash. Extract. Archive original. No drift. {/* Arrow INGEST → DISTILL */} {/* DISTILL */} DISTILL Vision model reads per-genre template. Drafts card. {/* Arrow DISTILL → HALT GATE */} {/* HALT GATE (alert dialog — slightly oversized, centred on row midline y=135) */} HALT GATE Nothing auto-promotes. Thesis sentence agreed? Anchor example cited? {/* APPROVE: double-bordered default */} APPROVE {/* REJECT: single border */} REJECT {/* Arrow HALT GATE → PUBLISH */} {/* PUBLISH + INDEX */} PUBLISH + INDEX Draft → published. Tag index rebuilds. Library compounds. {/* Annotation arrow pointing up at HALT GATE */} THESIS SENTENCE REQUIRED
Four stages. One human at the gate.
**Ingest.** References drop in. The system picks them up. Hashes each file. Extracts metadata. Archives the original somewhere durable. Permanent provenance. No drift. **Distill.** A vision model reads each reference through a per-genre template. Photography gets a different lens than video. Video gets a different lens than writing. Writing gets a different lens than direction. The model drafts a card. **HALT gate.** Nothing promotes automatically. I review every draft. If a trend card doesn't have a thesis sentence I agree with, it doesn't publish. If a DNA claim doesn't cite a real anchor example, it doesn't publish. The model can draft all it wants. I sign off. **Publish and index.** An approved card moves from draft to published. A tag taxonomy rebuilds. Every card becomes searchable by axis. By lighting. By palette. By mood. By era. The library compounds rather than piling up. Stage 3 is where most systems break down. Without a human approval gate, you accumulate plausible-sounding content that doesn't actually represent your taste. The HALT gate isn't a bottleneck. It's the quality contract. The criteria aren't about polish. They're about whether the card earns its place. Does the thesis sentence say something specific? Does the DNA claim cite a real frame from a real file? Has the model fallen back on adjective lists like "authentic, raw, elevated"? If yes, reject. If the answers are clean, approve. Two seconds per draft. Months of compounding payoff.
HALT gate close-up: the review dialog A large System 7 modal dialog titled REVIEW DRAFT. Three checklist items: Thesis sentence agreed with a filled checkbox, Anchor example cited with a filled checkbox, and Adjective list rejected with an empty checkbox. Two buttons at the bottom: APPROVE with double border indicating it is the default action, and REJECT with a single border. {/* Dialog shadow */} {/* Dialog body */} {/* Title bar */} {/* Double close box for default dialog */} {/* Title */} REVIEW DRAFT {/* Intro */} Before this card publishes, confirm: {/* Item 1: checked */} x Thesis sentence agreed One sentence. Concrete noun + concrete technique. {/* Item 2: checked */} x Anchor example cited A real file from the library. A real frame. {/* Item 3: unchecked */} Adjective list rejected "Authentic, raw, elevated" earns nothing. Cut it. {/* APPROVE: double-bordered default */} APPROVE {/* REJECT: single border */} REJECT
No card ships without a thesis. No DNA claim ships without an anchor.
## One source of truth Every workspace I run can pull from the same context layer. A brief that needs style direction names a few reference points. Those names resolve to the published cards. One source of taste. Every surface gets the distilled layer, not a re-explanation of it. This is the part that beats tagging systems. A tag is a label. A card is a position. When a workspace pulls a card, it isn't filtering by keyword. It's loading a thesis sentence and the operative moves that go with it. The taste arrives ready to use.
The consumer contract: one central LENS folder fanning out to four workspace windows A System 7 folder icon labelled LENS sits at the centre. Thick black arrows with orthogonal routing fan outward to four smaller System 7 windows labelled Workspace A, Workspace B, Workspace C, and Workspace D. Each arrow is labelled with a small reference tag. A caption reads: one source of taste, many surfaces. {/* Workspace A: top-left */} WORKSPACE A Creative direction brief locked {/* Workspace B: top-right */} WORKSPACE B Style guide palette + lighting {/* Workspace C: bottom-left */} WORKSPACE C Visual world texture + type {/* Workspace D: bottom-right */} WORKSPACE D Campaign brief direction locked {/* Central LENS folder (System 7 folder outline: tab + body as a single shape) */} LENS PUBLISHED CARDS + PROFILES {/* Arrow to A: out from LENS, up, into A's right edge pointing LEFT */} trend ref {/* Arrow to B: out from LENS, up, into B's left edge pointing RIGHT */} dna ref {/* Arrow to C: out from LENS, down, into C's right edge pointing LEFT */} dna ref {/* Arrow to D: out from LENS, down, into D's left edge pointing RIGHT */} trend ref {/* Caption */} ONE SOURCE OF TASTE, MANY SURFACES
Distil once. Consume many times.
The compounding effect comes from separating distillation from consumption. Distil once. Consume many times. A card built from a reference in January is still load-bearing in August. A DNA profile built from last year's corpus is still accurate if the work hasn't drifted. The alternative is re-briefing your aesthetic every time. That doesn't scale. It also means your reference library is a graveyard. Storing things, not answering questions. Try composing a card from its axes. Select any combination and watch the thesis synthesise: The fidget is a toy version of what the real cards do. Pick axes, get a thesis. The real cards add anchor examples, failure modes, and the human gate. But the shape is the same. Taste decomposes into positions you can name and recombine. Taste is a structured artefact, not a vibe. The discipline is the HALT gate. Nothing publishes without a thesis you can defend and an anchor example you can point to. The system isn't what makes the work consistent. The approval gate is. // --- ## I gave my LLM a Cortex URL: https://aris-space.com/documents/memory/cortex Date: 2026-05-23 import { Diagram, Code, Video, Download, Pullquote, BlindVsBrainBoot, CortexRegionMap, ConsolidationCompressor } from '@/components/blocks' # I gave my LLM a Cortex
Cortex: a memory layer between your files and any model Three stacked System 7 windows. Top window YOUR FILES holds notes, transcripts and outputs and is labelled canonical. A downward arrow labelled index leads to the middle window THE CORTEX, a derived index of brain regions and strengthening edges. A second downward arrow labelled retrieve and inject at session start leads to the bottom window ANY MODEL, listing Claude, Codex, Gemini and local. {/* Window A: YOUR FILES */} YOUR FILES notes · transcripts · decisions · outputs briefs · ship reports · past work canonical. the brain never owns this. {/* arrow A -> B */} index: chunk · embed · tag {/* Window B: THE CORTEX */} THE CORTEX language vision episodic identity edges strengthen when chunks fire together SQLite + vectors · rebuildable · nothing destroyed {/* arrow B -> C */} retrieve + inject at session start {/* Window C: ANY MODEL */} ANY MODEL Claude Codex Gemini local via injected context · adapter · MCP server
Every LLM session boots blind. Close the window and it forgets everything. The notes, the transcripts, the decisions: all of it piles up write-only, never read back. So you re-explain yourself. Every single time. I stopped patching this with bigger prompts and built a brain instead. Cortex is a memory layer that sits between your files and any model. One principle holds it up: Files own the truth. The brain owns the connections. ## The intent The goal was never a smarter model. It was a model that stops forgetting. A working setup already produces everything a memory needs. Notes get written. Conversations get logged. Decisions get recorded. Work ships. The substance is all there. What is missing is the connective tissue: a way to read it back, organised, at the exact moment it matters, without a human remembering to go and fetch it. Bigger context windows do not solve this. They are rented, not owned, and they reset. The fix is a layer that persists underneath the model and survives every session, every tool, and every model swap. ## The philosophy Five rules shaped every decision. 1. **Files are canonical.** The brain never owns content. It is a derived index you can delete and rebuild from your files at any time. Lose the index, lose nothing. 2. **Nothing is destroyed.** Importance decays over time. Rows do not. Old thinking fades in weight but is always walkable back to its source. 3. **Event-triggered, not command-driven.** The brain loads context at session start and re-indexes when files change. You never have to remember to ask. The brain reminds you. 4. **Index the thinking, not the actions.** Reasoning, decisions, prompts, and outputs go in. Tool noise and mechanical logs stay out. Signal only. 5. **The model is the replaceable part.** Nothing here is tied to one provider. The contract is the surface. The model is configuration. The system around the AI is the intelligence. ## Why a brain, not a database A flat vector database can store everything and surface nothing useful. The structure is the point. Borrowing from human neuroanatomy gives the memory shape, and the shape is what makes retrieval feel like recall instead of search. **Regions.** Every memory lives somewhere. Language comprehension, language production, vision, episodic events, spatial and project structure, and identity each map to a region. Retrieval comes back grouped the way the memory is organised, not as one undifferentiated pile. **Tracts.** Regions are wired together by typed edges. Some are deterministic: a prompt wires to its answer, an image wires to its description, everything in one project wires together. Others accumulate: any two memories retrieved together enough times grow a permanent edge between them. Fire together, wire together. Cold edges decay. **Consolidation.** Raw capture is expensive and noisy, so the brain sleeps. Over time, raw sessions distil into session digests, then daily summaries, then long-lived signal, then promoted facts. Importance rises as content proves durable. A year of raw thinking compresses roughly 37 times into a small, dense, queryable store, with a full lineage walk back to the original on demand. **Modes.** The same brain thinks differently on demand. A creative mode weights the retrieval differently from a deep-reasoning mode or a fast-recall mode. Neuromodulation, as software. One brain, several postures. ## How it decides what to pull This is the question everyone asks. The honest answer: nothing picks a single right memory. The brain ranks everything and surfaces the top of the stack. There is no query you type. At the start of a session the query is your situation: which project you are in, what you touched last, the task in front of you. That becomes the search. From there it pulls candidates by meaning, then re-ranks them on several signals stacked together: - **Region and layer.** Identity and core rules sit high and never fade. Episodic memory is scored by how recent it is. - **Importance.** It decays over time, so old noise sinks while durable facts stay near the top. - **Co-activation.** Anything retrieved together before gets a boost. Fire together, wire together. This is how the brain learns your patterns. - **Graph walk.** Once a memory is in, it follows the edges (a note to the decision it led to, an image to its caption) and pulls the connected pieces too. A token budget caps the result so it never floods the window. And the whole stack reweights with mode: creative pulls differently from deep, or from fast-recall. Same brain, different posture.
How Cortex ranks and pulls context A vertical System 7 pipeline. WHERE YOU ARE (your current project, recent files and task) becomes the query and flows into CANDIDATES, ranked by meaning. Those flow into RE-RANK, which stacks four signals: region and layer, importance decay, co-activation, and graph walk. A MODE callout on the left reweights the RE-RANK stage. The result passes through a TOKEN BUDGET cap and arrives as INJECTED CONTEXT grouped by region. {/* Stage 1: WHERE YOU ARE */} WHERE YOU ARE project · recent files · the task at hand this is the query. you never type it. {/* Stage 2: CANDIDATES */} CANDIDATES everything, ranked by meaning (vectors) {/* Stage 3: RE-RANK */} RE-RANK region + layer · core stays, recent ranks importance · decays over time co-activation · fire together = boost graph walk · follow the edges outward {/* MODE callout */} MODE reweights the whole stack {/* Stage 4: TOKEN BUDGET */} TOKEN BUDGET cap it. never flood the window. {/* Stage 5: INJECTED CONTEXT */} INJECTED CONTEXT dropped into turn one grouped the way the brain organises it
Nothing decides the answer. It surfaces the best-ranked context for where you are, and it sharpens the more you use it. ## How to set it up The pattern is small, and every piece is swappable. Nothing below needs a paid API. Local defaults run it offline. {`your files/ # canonical: notes, transcripts, decisions, outputs index.db # derived: SQLite + a vector extension hooks/ session-start # run retrieval, inject top-k context into turn 1 on-change # re-index a file the moment it is edited jobs/ nightly # consolidate raw -> digests -> facts (the "sleep") adapters/ injected-context # default: drop context into the prompt preamble mcp-server # for tools that speak Model Context Protocol`} The seven moves: 1. **Keep your files canonical.** Your notes and transcripts stay the source of truth. The brain reads them, it never replaces them. 2. **Build a derived index.** SQLite plus a vector extension is enough. Chunk each file, embed it, and tag it with a region and a memory layer. 3. **Wire the deterministic edges.** Prompt to answer. Image to caption. Everything inside one project to everything else inside it. 4. **Let co-activation do the rest.** When two chunks keep getting retrieved together, strengthen the edge between them. Let unused edges fade. 5. **Auto-inject at session start.** A start-up hook runs retrieval and drops the top results into the model's first turn, organised by region. No one has to ask. 6. **Re-index on change, consolidate at night.** A file-change hook keeps the index fresh. A nightly job distils raw capture into durable facts. 7. **Stay model-agnostic.** Expose the brain through injected context, a thin adapter, or an MCP server. Any model can read it. The next model can too. ## What it unlocks for any LLM The difference is not subtle. It is the gap between a tool that starts cold and one that starts knowing. - Every session boots with the right context already loaded, shaped the way a brain organises it. - The brain volunteers what is relevant instead of waiting to be queried. Recall, not search. - It learns your patterns. Over weeks it notices which things fire together and surfaces them before you think to look. - A year of raw thinking lives in a small, dense, rebuildable store, with nothing lost. - It works across every model you use today, and the one you switch to next month. A model with no memory is a stranger you brief from scratch every morning. A model with a Cortex is a collaborator who remembers. The model is the replaceable part. The brain is what persists. {/* TODO download — wire in the enrichment pass: */} --- ## Max thinking is wasted on an empty room URL: https://aris-space.com/documents/workspaces/max-thinking-empty-room Date: 2026-05-30 ## Narration Picture the same model dropped into two rooms. One is empty. One is full of your briefs, notes, and past decisions. In the empty room, hard thinking just produces a slower guess. In the full room, that same thinking turns into research. This is a technical write-up of something I noticed this week. One new thing on the site, since this is the first post to use it: any jargon is underlined like this, so you can hover for a translation, and there is a full glossary at the foot. The piece itself stays technical. The glossary is just there so no single word stops you. ## What I was actually doing Modern models expose a setting for how hard they think. Turn it up and you are running max thinking effort: the model spends far more reasoning, and far more tokens, working the problem before it replies, instead of answering on instinct. I ran the newest model at that top setting all week, against a fully loaded context window. The interesting part was not "it is smarter." It was discovering what that extra thinking actually needs in order to be worth anything. The short version: hard thinking is wasted unless you have given the model something to think with. Effort is a multiplier, and a multiplier on nothing is nothing. ## 1. The room matters more than the model Here is the bit that surprised me. The jump between the last model version and this one did not feel like smarter model weights. It felt like the model got better at using the room I gave it. By "the room" I mean the context environment: the briefs, the notes, the earlier decisions, the examples I load in before I ask my question. All of that sits in the model's context window, which is just its short-term memory for the task. Drop a hard-thinking model into an empty room and you get a slow, confident guess. Drop it into a room you have actually furnished and it does something different. It digs. ## Narration The model is the same for everyone. What changes between a weak answer and a strong one is how much relevant material you put in the room first. The room is the part you control. The mechanism underneath is retrieval. With a large window loaded, the extra effort does not go into inventing more. It goes into reading what is already in front of it, cross-referencing it, and grounding the reply in it. The weights are fixed and identical for everyone, so they are not the variable you control. What sits in the room is. This is also why the big context window matters more than it looks. A larger room is not about fitting more text. It is more evidence for the same effort to dig through. So the takeaway is not "buy a better model." It is "build a better room." ## 2. The slow part is the feature, not a fault When you turn thinking up, the wait gets noticeably longer. My instinct was to read that as the tool being slow. It is not slow. It is busy. During that pause the model is going back through everything in the room, looking for evidence before it commits to an answer. The wait is the work. If you judge the model by how fast it replies, you are measuring the wrong thing. Judge it by the quality of what it found. Concretely, the extra latency is spent re-reading the source material, testing claims against it, holding more than one candidate answer at once, and dropping the ones the room does not support. It scales with how much context there is to search. A thin room answers fast because there is nothing in it to read. A deep room answers slowly because it is actually being read. The speed is a readout of how much digging happened, not a measure of the model's intelligence. ## Narration A short pause tends to produce a quick guess. A longer pause, spent reading the room, tends to produce an answer that is backed by something. Same model, different amount of digging. This matters most for agentic work, where the model runs several steps on its own. A model that checks the evidence before each step is worth far more than a fast one that confidently walks off a cliff. ## 3. It works backwards from evidence This is the real shift, and it is the thing I had not seen before. The newer model goes looking for proof in your room first, then forms its answer around what it found. The older one was more likely to answer first and justify afterwards. That order matters. Working forwards from a guess gives you something that sounds right. Working backwards from evidence gives you something that is right, or at least something you can check. It is the best reasoning I have seen from any model, and it only shows up when there is evidence in the room to find. In practice the tell is grounding. Ask it something the room can answer and it ties the reply back to the specific material you loaded, rather than to a general impression. The failure mode of the older behaviour was the confident, plausible answer that quietly had nothing behind it. Evidence-first does not delete that risk, but it pushes it down, because the answer and its support are built in the same pass, instead of the support being bolted on after the fact. ## Narration Two ways to reach an answer. One starts with a guess and then hunts for reasons to support it. The other starts with the evidence and lets the answer follow. The second is slower and far more trustworthy. ## How to build the room "Build the room" is easy to say and vague to act on, so here is the practical version. The room is everything in the context environment that sits there before your question, and its quality caps the answer. The model can only dig through what you put in front of it. In practice that means loading, ahead of the question: the source material itself, the briefs and constraints that define the task, the decisions you have already made and the reasons behind them, and a few worked examples of the output you actually want. Not a summary of those things. The things themselves. A summary is pre-chewed, and pre-chewed material leaves nothing to dig for. The discipline is counter-intuitive. You spend more time assembling the room than writing the prompt. The prompt gets shorter. The room gets richer. That trade is the method. ## When the dig is not worth it Max effort is not a default to leave on. It is a cost, paid in latency and tokens, and it only pays back when there is a room worth searching. For a thin context or a simple lookup, turn it down. Otherwise you wait longer for a guess that a lighter setting would have produced just as well. Match the effort to the room. A deep room earns a deep dig. An empty one does not, and paying for one is how max effort gets its bad reputation. That is also the honest limit of the finding. The model genuinely improved. But the part you control, and the part that moved most of my results, is the room. ## Have a play The widget below is the whole idea in one toy. Add or remove layers of context, ask the question, and watch how much the model can dig before it answers. An empty room gives you a guess. A full one gives you a researched reply. ## The one rule to take away Thinking effort and context are a pair. You cannot turn one up and ignore the other. Max effort on a thin room is an expensive guess. Max effort on a room you have built is a researcher. Build the room before you ask the question. The model is the part everyone talks about. The room is the part that actually decides the answer, and it is the part you control. --- ## One sentence. Four product pages. Two hours. One round of notes. URL: https://aris-space.com/documents/workspaces/one-sentence-four-product-pages Date: 2026-05-30 import { Diagram, Code, Video, Download, WorkerFanOutFidget, Pullquote } from '@/components/blocks' {/* HERO — interactive fan-out animator. Click the prompt: 5 workers fire in parallel, W6/W7 cascade, then the staged-preview gate holds for you. */} ## The whole brief was one sentence This is exactly what I typed to start the session. Word for word, nothing trimmed: Familiarize yourself with the Pushing Squares website, then evaluate what needs to be done for CBA, Fuzz, Subtract to be done and sellable by the end of the night. Twenty five words. No spec. No file paths. No list of steps. No mention of checkout, signing, pricing, marketing footage, or which pages to build. About two hours later there were product pages live on the site. Real checkout. Real signed builds. Real marketing footage rendered from scratch. My total input for the whole run was a handful of "status?" check-ins and one round of notes. The prompt was tiny. The intelligence was not in the prompt. ## The theory: a prompt is a pointer, not a payload Here is the idea most people get wrong about working with AI. They treat the prompt as the place where the thinking happens. So they write longer and longer prompts, stacking in context, examples, rules, edge cases, trying to cram the whole job into the message box. The prompt becomes the spec. That is backwards. A good prompt is not a payload that carries the work. It is a pointer that aims at work the system already understands. My one sentence carried almost no information. Twenty five words cannot describe what "sellable" means for a software product. They cannot describe a checkout flow, a signing pipeline, a brand voice, or how to render a shader over footage without the host app open. The task needed thousands of small decisions. My prompt resolved none of them. So where did the decisions come from? They were already resolved. Not in the prompt. In the workspace around it. {/* DIAGRAM 3 — prompt vs workspace. Tiny prompt on one side, the tall stack of context/constraints/workers/memory on the other. Where the intelligence actually lives. TODO: art. */} ## What it already understood that I never said This is the part worth slowing down on, because it is the whole argument. Off that one sentence, here is what the workspace already knew, with no further context from me: - **What "sellable" even means.** It did not ask. The site already had live products, and those live pages defined the pattern: a product page, a checkout link, a price, a download-verify route, real assets. "Sellable" was already specified by the existing reference, so it read the reference instead of asking me. - **That the builds did not need notarisation.** It checked the precedent set by the products already shipped, saw they used the same lightweight signing, and concluded the same path was safe. I never mentioned signing. The decision was inherited from history. - **That a render engine already existed to shoot the marketing.** The hardest part of "sellable" was marketing footage, and normally that needs the host app open to capture. The workspace already held a tool that pulls each plugin's shader straight from its source and renders it over footage on its own. I did not know that was the unlock when I typed the prompt. The workspace did. - **That the render tool's bugs were already diagnosed.** A handoff note from an earlier session had two bugs in that tool written up, with the exact fixes. So "fix the renderer" was not a research task. It was a known job waiting to be executed. That note was deposited by a past version of this same collaboration. - **Where the credentials lived.** It worked out that the payment and storage keys were not local, that they lived with the deployment, and that the workers should pull them after cloning. I never told it where anything was kept. - **The brand voice and page structure.** It matched the new pages to the existing ones in tone and shape without me handing over a style guide, because the style guide is the workspace. None of that was in my twenty five words. All of it was load-bearing for the result. I did not give it deep context. It already had deep context. My prompt just pointed at it. ## Why the workspace knows so much: context compounds The workspace did not understand all this by accident. It understands because every prior session left something behind. The handoff note that had the render bugs diagnosed. The ship reports from earlier products. The memory of how signing was done last time. The live reference pages built in previous runs. The brand rules written down once and never re-typed. Each of those was a deposit. By the time I typed one sentence, the account had been compounding for months. That is the real mechanism. A long prompt tries to load context at the moment of asking, every single time, from cold. A good workspace loads context once and lets it accumulate, so the next prompt can be short because the understanding is already resident. This is the 10% rule pointed inward. Make the system that surrounds the work 10% better every time you touch it, and eventually a sentence is enough to move a mountain, because the mountain was already half-moved by everyone who came before, including past you. ## The collaboration ran on a handful of short messages It was not just the opening that was terse. The entire two hours of my side of the conversation was tiny. These are real, verbatim: "status?" "go ahead" "can you spin up a local host for me to QC" That was most of it. While five workers built, signed, and rendered in parallel, and two more waited on their inputs, I mostly asked how it was going. I was an orchestrator, not a typist. {/* DIAGRAM 1 — parallel vs chained. Top row: 5 workers running at once. Bottom: the 2 dependent workers firing only after their inputs land. TODO: art. */} ## It stopped at the gates and held for me The system was autonomous, but it was not unsupervised. It staged a preview and stopped. It did not push anything live. It held for me to look and click. When a fourth plugin went up later, the entire correction I gave was one message: Don't include the images for the effects we don't have images for, just use the gallery for the ones I provided, but mention all of the effects below in text. Other than that, everything looks perfect. One note. Then: perfect merge and deploy live to the site via vercel plz That is the shape of being in the loop properly. Not writing the work. Not babysitting every step. Just sitting at the two or three gates that actually need a human: is this right, and should it go live. {/* DIAGRAM 2 — the review gates. Staged preview, the one round of notes, the human go-live click. TODO: art. */} ## So: build the workspace, not the prompt Most people think the leverage is in writing a clever prompt. It is not. A one line prompt did all of this because of everything sitting around it. The context. The constraints. The review gates. The accumulated memory. The workers that already know how to build, sign, render and ship. If you want short prompts to do large things, you do not get there by writing better sentences. You get there by building a system that already understands, so the sentence has somewhere deep to land. The prompt is the trigger. The workspace is the intelligence. > Stop prompting. Start defining outcomes_ --- ## The setup I use to ship while I sleep — now open-sourced URL: https://aris-space.com/documents/tools-and-plugins/ship-while-i-sleep Date: 2026-06-02 ## Narration The whole setup is one loop. You brainstorm an outcome, plan it into steps, dispatch a step to a background worker, watch the dashboard, review what comes back, and ship what passes. You stay on the thinking steps. The work runs somewhere else. ## I was the bottleneck For a long time I was the slowest part of my own work. Everything ran through one window. One conversation, one me. I would have three good ideas and they would queue up behind whatever I happened to be typing. The tool in front of me was fast. I was the line it had to wait in. So I changed the shape of the job. Instead of doing the work, I started directing it. I stay in one seat and advise. The actual building happens somewhere else, in the background, handled by workers I hand tasks to and check on later. It runs whether I am at the desk or asleep. That last part is the honest claim, and I want to be careful with it. This is not ten times faster. It does not replace anyone. It removes one specific problem: me being the single point that everything has to pass through. I packaged the setup and open-sourced it. It is called ARI-OS. The rest of this is what it actually does. ## The part people get wrong The model is not the intelligence. The system around it is. A good model with no system is a brilliant person you interrupt every thirty seconds. The leverage is not in the answer the model gives you. It is in how the work gets framed, handed over, tracked, and brought back. Build that scaffolding once and the same model does noticeably better work, because you have stopped making it start from nothing every single time. ARI-OS is that scaffolding. A few plain pieces, each doing one job. - **An advisor seat.** Your main session stays for thinking and deciding, not grinding through the work itself. - **Background dispatch.** You hand a defined task to a cheaper worker that runs on its own, detached from your session. - **A handoff layer.** Context survives when a session ends, so the next one starts cold without losing the thread. - **A memory.** The setup remembers across sessions and pulls the right past context back when you need it, so you are not re-explaining yourself every time. - **Spec-first brainstorming.** You shape the outcome in plain language before any code gets written. - **A small dashboard.** One glance shows what is running, what finished, and what is stuck waiting on you. None of these are clever on their own. Put together, they change who has to be in the room for work to move. Take the part that does the most quiet work: context. A model with nothing in front of it gives you a confident guess. The same model, handed the right briefs and past decisions, gives you a researched answer. Try it. ## The memory For a long time the setup forgot everything the moment a session ended. Every new conversation started from nothing. So I gave it a memory. A small brain that lives on your own machine. You write to it, you read from it, and what you keep is still there next session, and the one after that. Two things make it more than a notes file. It tunnels. By default it pulls only what is close to what you are doing now, not your whole history. Narrow on purpose. If it senses you might need to look wider, it offers, and waits for a yes. It never widens the search on its own. You decide how far it reaches. It wanders. Every so often it surfaces one memory from outside whatever you are buried in. Deep focus forgets to look up, so the setup looks up for you, then hands the thread back. It keeps a rhythm. At the start of a day it hands me back what I was in the middle of, the threads still open, and a sensible place to begin. At the end it tidies itself, notes what got decided, and leaves a short line for tomorrow. I open the laptop already oriented, instead of spending the first twenty minutes remembering where I was. It is not limited to text either. Point it at a recording or a piece of footage and it can turn that into something it remembers too, so a conversation or a rough cut is not gone the moment it ends. None of this thinks for you. It remembers, and it puts the right things in front of you at the right time. You still decide what they mean. AI accelerates, it does not generate. ## The receipt Here is the part that earns the title. I built a chunk of ARI-OS using ARI-OS. I specced a tool I wanted. I handed it to a background worker. I went to bed. In the morning the tool existed, its tests were green, and there was one question waiting for me about a naming choice. I answered the question. That was my whole contribution overnight. That is the receipt. The setup was complete enough to extend itself while I was not there. Nothing magic happened. The work simply did not need me sitting in the chair for it to move forward. ## The loop The whole thing is one loop. Six steps, and you can learn it in an afternoon. 1. **Brainstorm.** Talk the idea out until it is a clear outcome, not a vague wish. 2. **Plan.** Turn that outcome into ordered steps. 3. **Dispatch.** Hand a step to a background worker and let it run. 4. **Watch.** Glance at the dashboard. See progress. See what is blocked. 5. **Review.** Read what came back. Keep it, or send it back with notes. 6. **Ship.** Merge the work that passed. You live on steps one, five, and six. The judgement steps. The machine takes three and four. Step two is shared. That division is the whole point. The parts that need you are the parts where taste and judgement matter. The parts that do not need you stop waiting for you. Dispatch is the step that does the heavy lifting. One idea fans out into workers that run in parallel, feed into each other, and arrive as something you can review. Have a play with it. ## Try it ARI-OS is open-source and installs with one command. It sits on top of an existing Claude Code setup, and it is reversible, so you can take it off cleanly if it is not for you. If you have ever felt like the bottleneck in your own work, this is the thing I built to stop being one. [ARI-OS overview](/documents/ari-os/overview) and [view it on GitHub](https://github.com/PUSHINGSQUARES/ARI-OS). {/* --------------------------------------------------------------- ENRICHMENT TODO (not blocking the draft): - hero image: /posts/tools-and-plugins/ship-while-i-sleep/the-loop.png (generate via scripts/gen-deepdive-images.py, 1-bit System-7 look) - tags + for: advisor-seat, background-dispatch, handoff, spec-first (add entries to content/glossary.ts if missing) - repo link in "Try it" once the repo is flipped public --------------------------------------------------------------- */} --- ## Warm the room, keep the grade honest URL: https://aris-space.com/documents/tools-and-plugins/shade Date: 2026-06-08 import { ShadeWriteupDemo } from '@/components/shade/ShadeWriteupDemo' # Warm the room, keep the grade honest I am dyslexic. Reading off a white screen is harder for me than reading off paper, and it gets worse the longer the day runs. The fix I have used for years is a colour tint over the page. Not brightness. Colour. A wash of warmth or a specific hue sat over the text, and suddenly the letters hold still. People call it Irlen-style. I call it the only way I get through a long edit without my eyes giving up. So the first reason Shade_ exists is selfish. I wanted that tint, on my Mac, on every window, all the time. ## The second problem: screens are too bright at night I work nights. By 2am a white editing timeline is a floodlight. And in the age of AI work, the screen never really goes off. We are all vampires now, hunched over a glowing rectangle until sunrise, so every little bit of relief helps. macOS has Night Shift, which warms the display, and it is fine for browsing. But it warms the *whole* display. Every pixel. Including the footage I am grading and the photo I am retouching. Which leads to the problem that actually made me build this.
A lone figure hunched at a desk in the dark, lit only by a glowing screen, late at night. System-7 8-bit pixel art style.
The all-night screen worker. We are all vampires now.
## The third problem: a warm screen lies to your colour grade I do not only do AI work. I shoot, I edit, I grade. And there is a specific, expensive trap waiting for anyone who grades on a warmed screen. You spend hours on a colour grade. Your screen is warm, either from Night Shift or from the room. Without realising it, your eyes adapt to that warmth and you start *compensating* for it. You cool the image down to make it look neutral to you. Then you export, open it on a screen that is not warmed, and the whole thing is freezing. Too cool. Hours of careful work, quietly pulled in the wrong direction by your own monitor. The screen lied to your eyes, so you lied to the grade. I have done it. It is maddening, because the work felt right the entire time.
Two monitors side by side showing the same portrait: the left screen has a warm cast and looks neutral, the right screen looks cold and blue. System-7 8-bit pixel art style.
A grade that reads neutral on a warm screen and freezing on a neutral one. Before and after.
## The fix: Passthrough This is the whole reason Shade_ exists in the form it does. It warms and dims everything on screen, then cuts live holes through the warmth over the windows you choose. Name your grading window, your reference photo, the design of the site you are checking. Those windows stay completely true. Everything around them goes warm and calm. The holes track the windows. Move a window, the hole follows. Resize it, the hole resizes. It is not a static cut-out you line up once. It follows the geometry in real time. So you get the comfort everywhere it does not cost you anything, and a guaranteed-honest window exactly where colour has to be right. No more grading against a warmth you forgot was there. No more guessing whether the blue you are looking at is the real blue.
A dim warm-tinted room with one bright, clear, true-colour rectangular window cut through the warmth, showing accurate colour inside it. System-7 8-bit pixel art style.
One honest window inside a warm room. That is Passthrough.
## How it actually works, honestly The shipping engine is simple on purpose. It is a click-through overlay window sat above every display. It tints. It dims. It does not read your pixels, which means it needs no Screen Recording permission, and the windows underneath stay fully interactive. You click straight through it. Here is the honest part most "screen filter" apps do not tell you. The overlay composites source-over. In plain terms, it can only *add* light and colour on top of what is already there. It cannot darken the pixels beneath it. It cannot pull colour back out from under the tint. It is a comfort layer, not a colour-correction engine. When I say it warms your screen, I mean it lays warm light over the top, the same way a sheet of warm gel over a lamp changes the room without rewriting what the lamp is pointed at. This matters because it sets the honest ceiling on what the tool is. If you want your whites less blinding, Shade_ does that by adding warmth over them, not by turning them down at the source. The effect on your eyes is real. The mechanism is additive. I would rather tell you that than sell you a filter that pretends to do more. That single fact, that a Mac overlay window is source-over only and can add light but never subtract it, shaped the entire product. Every design decision downstream of it is me working *with* that limit instead of pretending it is not there. ## The part I am not shipping yet There is a second engine in the codebase. It transforms live pixels rather than laying light over them, which is the thing that would let you genuinely pull a screen down rather than just warm it up. It works, in the lab. It is also dev-gated and off by default, because transforming live pixels on macOS can recurse on the system's own screen capture and eat itself. That is a real failure mode, not a hypothetical, so it stays behind a flag until it is safe for a stranger to run without thinking about it. I am telling you it exists because I would rather be straight about the roadmap than quietly hide an experiment. Today, Shade_ is the overlay. The transform is research. ## The rest of it Two more things I needed, so they are in. A schedule. Manual local time, and it can cross midnight, because my "evening" starts when most schedules have already given up. Set it once and the warmth arrives on its own. Launch at login. A comfort tool you have to remember to switch on is a comfort tool you stop using. It should just be there. And the free Hue overlay, the original reason, any colour you like sat over the whole screen. That is the dyslexia reading aid, shipped as a first-class feature rather than an afterthought, because for me it was never the afterthought. ## Why it is free Shade_ is free and open source, signed and notarised, MIT licensed. I did not build it to make money. I built it because I needed it, and because the people most helped by a reading tint are not the people who should have to pay to find out it helps. If it gets one more dyslexic editor through a night shift with their eyes intact, that is the return. Warm the room. Keep the grade honest. That was the whole brief, and the honest version of it is the one worth shipping. Shade_ is free. // --- ## 540 Commits. One Human. URL: https://aris-space.com/documents/workflows/540-commits-one-human Date: 2026-06-13 A week and a half ago I stopped writing most of my own code. Not because I got lazy. Because I got a better seat. 540 commits landed in 11 days. One human behind every one. I wrote almost none of them by hand. I routed them. ## On the loop, not in it I don't sit inside the work any more. I sit on top of it. I plan, I route, I sign off at the gates that matter. A fleet of models does the execution. The intelligence isn't any single model. It is the system around them: who gets which job, who checks the result, what gets remembered. ## The week, by the numbers - 540 commits in 11 days. Peak day: 106. - 6 tasks built overnight. Every one audited. Zero input. - A graph that went from 54% to 84% precise. Then 9.5x faster in a day. - A signed macOS app, 165 tests green. 600 green on the memory engine. - One loop ran away. £2. Capped. - One human behind all of it. ### Plan in, product out I handed a plan to a build loop and went to sleep. By morning there was a finished result on the desk. 6 tasks, every one independently audited, about two hours start to finish. I touched none of it. ### A second model marks the homework Nothing counts as done because the worker says so. A separate model audits every result before it lands. Pass, fail, or escalate. That single rule is what lets me stop checking the work. ### Right model, right job Five models, each on what it does best. Fable holds the orchestrating seat. Codex writes the heavy code. Kimi reads long video. MiniMax M3 runs looping builds. Local models hold the memory. Opus 4.8 when the seat needs more muscle. ### Measure, then kill the darling I built a "smarter" retrieval system and measured it against the dumb baseline. It pulled 29% more context and got it more wrong. So I cut it. The yardstick beats the opinion, even when the opinion is mine. ### Rails, not babysitting One overnight loop ran away. It burned about £2 before a hard cap caught it. I did not jump in at 3am. The rail did its job. When a system misbehaves, you cap it structurally, then you walk away. ## What this is becoming All of it is one system now. I call it ARI-OS. The memory layer is Cortex. The week and a half was not a sprint. It was the system getting good enough that I could step back and let it run. The intelligence is the routing, not any single model. --- ## Fable made me start using Codex URL: https://aris-space.com/documents/workflows/fable-made-me-start-using-codex Date: 2026-06-13 import { Diagram, ModelMatrixFidget, TaskRouterFidget } from '@/components/blocks' Fable made me start using Codex. Well, actually Claude, Codex, Kimi and MiniMax M3 together. Not because Fable is weak. Because it is the first model strong enough to run the other models properly. The shift: stop asking which model is best. Start matrixing every model to the task it performs best at. - Claude (Fable): the seat. Orchestration, judgement, long context. - Codex: the coding powerhouse. - Kimi: long-video understanding. - MiniMax M3: the looping build system. Place each task chip on the model that owns it. Correct matches snap in with a one-line rationale; wrong matches bounce back. For the first time the multi-model workflow is truly effortless. Local models included. It all just works, because the model at the top is not doing the work. It is routing it. Flip routing on and watch tasks stop piling up. Flip it off and see what the inbox looks like without a matrix. ## The matrix in practice Here is the scrubbed version of how a task actually moves through my setup. Internals removed, shape intact. **Everything lands at one seat.** Claude holds the context, the taste and the judgement calls. The seat never does the labour. **Tasks are classified by shape, not by app.** A heavy code build. A long video to understand. A build that needs many passes. A judgement call. The shape decides the route before any model is named. **The matrix maps shape to model.** Codex takes the heavy code. Kimi takes the long video. MiniMax M3 takes the loops. Small local models handle memory and retrieval so context arrives already warm. **Workers run in the background.** Briefs go in as files. Results come back as files. No second chat window, no tab juggling. The seat stays clean for the next decision. **Nothing merges on a worker's word.** A fresh set of eyes with no memory of the build checks the claim before it lands. Trust the work, not the report. ```yaml route: heavy-code: codex long-video: kimi looping-build: minimax-m3 orchestration-and-judgement: claude memory-and-retrieval: local-models gates: audit: fresh context, before anything merges publish: human, always ``` ## The loops The newest slot in the matrix is the looping build system, and it is the reason MiniMax M3 earned a place at the table. A loop here is not a retry. It is a fresh-context pass. Each iteration spawns a clean worker that reads the plan from disk, does one slice of the work, writes the result back to disk and exits. The next pass starts with zero memory of the last one. That sounds wasteful until you watch it run. Conversations drift. Files do not. Because all state lives in files, every pass starts honest. It sees what is actually built, not what the last pass claimed it built. The loop ends when the plan says done or a gate says stop. That is also why a cheaper model can hold the slot. The discipline lives in the loop, not in the model. The model only has to execute one clean slice at a time. ## Two days on the matrix This page is itself a receipt, but I want to be precise about what the receipt proves. Fable did not magically replace the rest of the stack. The infrastructure I have built around it means I can give one tight brief, let the model reason thoroughly about the shape of the problem, and have the workspace turn that into routed work. The seamlessness comes from the system around the model, not from pretending one model should do every job. In my workspace, briefs, plans, outputs, audits and Cortex links all live as files. Fable can follow those links, hold the seat and decide which lane the next piece belongs in without dragging the whole working context into one chat. The diagrams above and the two toys you just played with were not built by the seat. The seat said what it wanted, a Claude Sonnet worker built the components and the diagrams and returned a green build, and the seat never opened the editor. Here is the rest of the window. Two days of real work, scrubbed but honest, six models each used for the task shape it fits best. | Task | Model | Why this one | |---|---|---| | Turn one tight brief into routed work | Fable | Thorough enough to solve the shape of the problem and hold the thread | | Build this page: components, diagrams, green build | Claude Sonnet | Fast, reliable hands for a contained build | | Plan the hard builds, think through the deep problems | Opus 4.8 | The slow, careful thinker, kept for plans and synthesis | | Close a heavy build a cheaper lane wobbled on | Codex | The coding powerhouse, brought in to finish clean | | Run the looping builds and the audit passes | MiniMax M3 | Cheap enough to loop, because the discipline lives in the loop | | Read a large pile in one pass and return a verdict | Kimi | The largest context window, the long-read lane | Two of these are worth saying out loud, because they are the part people usually flatten. The heavy build is the clean one. Every step is tiered against the model I actually have, not against a fantasy model that can do everything. Two cheaper passes wobbled on the same implementation. Codex took the next pass and closed it. The slot is not loyal to a model, it goes to whoever finishes it. The loop is the honest one. MiniMax M3 runs the audit passes, the fresh-context checks every build must clear before it merges. One night a briefing bug meant the check could never write its verdict, so the system kept firing the same audit again. It ran about ten times before anyone caught it. The fix was not a smarter model. It was a cap: three retries, then the task escalates to me instead of looping forever. A Claude Sonnet worker found the cause, added the cap and wrote the tests the same night, and the lane went back to work. A cheaper model looping is only a weakness if nothing around it knows when to stop. Both pieces, the routing matrix and the looping build system, are coming to [ARI-OS](/documents/ari-os/overview) in an update. Same discipline, packaged so it installs on top of an existing setup. That is the lesson worth keeping. I have spent my time with Fable, and with every frontier model before it, building the infrastructure to create the perfect workspace. The importance was always the infrastructure, not the solution. The intelligence is the routing, not any single model. --- ## Advanced: the default-off surface URL: https://aris-space.com/documents/ari-os/advanced Date: 2026-06-15 import { Code, SurfaceList, PatternDetect, Diagram, Faq, Pullquote } from '@/components/blocks' Most of this surface is off by default. The core brain works without any of it. Turn pieces on only when you want them, one at a time. Everything here runs through the cortex tool, `python3 -m ari_os.tools.cortex`, and the toggles live in the control panel, `python3 -m ari_os.tools.arios cortex on|off`. ## Knowledge graph The knowledge graph reads your memory and pulls out the entities and the relations between them. You get a graph you can list and measure, not just a pile of notes. Extract the graph, list what it found, then check its size. {`python3 -m ari_os.tools.cortex kg extract python3 -m ari_os.tools.cortex kg list python3 -m ari_os.tools.cortex kg stats`} `extract` builds the graph from your memory. `list` shows the entities and relations it found. `stats` measures it, so you can see how dense the graph has become over time. ## Prediction and prefetch Prediction looks at where you are and surfaces what you are likely to need next. Prefetch goes one step further and warms the context for a working directory before you open it. After enough repeats of the same shape, the brain recognises the pattern and acts on it. {`python3 -m ari_os.tools.cortex predict python3 -m ari_os.tools.cortex prefetch --cwd `} `predict` surfaces what you are likely to need. `prefetch` warms context for a given working directory, so the brain is ready the moment you arrive. ## Mind-wander Now and then, the brain surfaces a memory you had set aside. It is the quiet background process that connects an old note to the thing in front of you. {`python3 -m ari_os.tools.cortex wander --focus ""`} Use `--focus` to point the wander at a topic. Toggle the whole feature on or off through the control panel. {`python3 -m ari_os.tools.arios cortex wander on|off`} ## EARS (listening) EARS ingests sound. Point it at an audio file or a transcript, and the contents land in memory like any other note. {`python3 -m ari_os.tools.cortex ears `} Enable it through the control panel. {`python3 -m ari_os.tools.arios cortex ears on`} The vision parts of EARS need a local vision model. The plain audio and transcript path does not. ## LENS (seeing) LENS applies a visual or aesthetic lens to your work. Pass it a slug and it reads through that lens. {`python3 -m ari_os.tools.cortex lens `} Enable it through the control panel. {`python3 -m ari_os.tools.arios cortex lens on`} The MCP tools `brain.see` and `brain.lens` stay off until both LENS and a local vision model are enabled. Without the model, there is nothing to see with. ## Embeddings backends The brain needs an embeddings backend to turn text into vectors. Choose it through the control panel. {`python3 -m ari_os.tools.arios cortex embeddings auto|google|ollama|off`} `auto` picks a sensible backend for you. `google` and `ollama` pin it to one provider. `off` runs without embeddings at all. Most of this surface ships off. You turn it on when you want it, not before. To see how the core memory works underneath all of this, read the [brain page](/documents/ari-os/brain). --- ## Get the most from the Cortex brain URL: https://aris-space.com/documents/ari-os/brain Date: 2026-06-15 import { Code, SurfaceList, CortexRegionMap, ConsolidationCompressor, EvidenceDigFidget, LeakyBucket, Diagram, Pullquote } from '@/components/blocks' The Cortex brain is the memory layer of ARI-OS. It is local-first. It remembers across sessions on your own machine, and it both reads and writes through the `ari-os-cortex` MCP server. Nothing leaves your machine to make it work. A session with no memory boots blind. You re-explain yourself, then the window closes and it all drains away. The drawing below shows what that looks like. The brain plugs the leak. It holds the connections so each new session starts knowing, not guessing. ## How memory is organised Memory is not one flat pile. It is split into regions, the way a brain splits work across areas. Language comprehension, language production, vision, episodic events, spatial and project structure, and identity each map to a region. When you recall, results come back grouped the way they were stored, so the brain hands you a shaped answer instead of a heap. The map below is interactive. It does the explaining, so the prose stays short. ## Remember There are two ways to put something into the brain. Through MCP, call the tool `brain.remember(text, layer='semantic', source)`. The `layer` says where the memory sits, and `source` records where it came from. The brain dedupes by the sha256 of the text, so writing the same thing twice does not create a duplicate. From a file, write a markdown note first, then ingest it. The note is the canonical record. Ingesting it just teaches the brain the connections. {`python3 -m ari_os.tools.cortex ingest --path `} Memory files live under your memories directory, at `$ARI_OS_HOME/memories//.md`. The folder is the context, and the timestamp keeps each note in order. ## Recall There are two ways to pull memory back out. Through MCP, call `brain.recall(query, mode='default', k=12, token_budget=4000)`. The `query` is what you are looking for, `mode` shapes how the brain ranks, `k` is how many candidates it considers, and `token_budget` caps the result so it never floods the window. From the command line, run the retrieve command. The `--cwd` flag is the workspace gate. It scopes recall to what you are working on now, so you get the context that belongs to the project in front of you and not everything you have ever written. {`python3 -m ari_os.tools.cortex retrieve -q "" --cwd "$PWD" --mode `} Recall gets better as more context layers switch on. The fidget below shows the same answer sharpening as each layer is added. ## Modes A mode shapes how the brain ranks what it pulls. Same brain, different posture. There are 10 retrieval modes. Switch the active mode from the command line. {`python3 -m ari_os.tools.arios cortex mode `} On the cortex tool you can also list, get, and set the mode with `cortex mode list|get|set `. ## Consolidation (dream) Raw capture is noisy and expensive to keep at full size, so the brain sleeps. Dreaming is a deterministic distil plus decay pass. It compresses old memories down through tiers while their importance fades, and it never throws the lineage away. You can always walk a durable fact back to the note it came from. The slider below shows raw notes compressing through session, daily, and weekly tiers down to a durable fact, with the lineage still pointing home. Run a full dream pass. {`python3 -m ari_os.tools.cortex dream`} You can also run a single tier on its own. {`python3 -m ari_os.tools.cortex distill --tier session|daily|weekly`} The point of consolidation is to keep the store small and dense while losing nothing. Memories compress, but lineage still walks back to the original source. ## Embeddings The brain turns text into vectors so it can rank by meaning. The default backend is Ollama, which runs on your machine. Pull two models. The embedding model `nomic-embed-text` produces 768-dimensional vectors, and `gemma3:4b` handles the local language work. {`ollama pull nomic-embed-text ollama pull gemma3:4b`} `OLLAMA_URL` defaults to `http://127.0.0.1:11434`, so a standard local Ollama needs no extra configuration. With no Ollama running, recall falls back to a ranked keyword search. It is less precise than vector ranking, but the brain still works, fully offline, with nothing to set up. ## Where to go next Files own the truth. The brain owns the connections. For tuning, custom modes, and the deeper mechanics, read [Advanced](/documents/ari-os/advanced). To see the brain in a working session, read [Using it](/documents/ari-os/using-it). For the bigger picture of how ARI-OS fits together, start at the [Overview](/documents/ari-os/overview). --- ## Install ARI-OS URL: https://aris-space.com/documents/ari-os/install Date: 2026-06-15 import { Code, Steps, InstallRitual, OneCommitUndo, Diagram, Faq, Pullquote } from '@/components/blocks' ARI-OS installs on top of Claude Code. It does not replace it. It adds an orchestrator-first layer and a local memory brain called Cortex. Every change it makes is backed up first, so the whole install is reversible. AI accelerates, it does not generate. If you want a one-line overview of what ARI-OS is before you install, read the [overview](/documents/ari-os/overview). ## Clone and install Clone the repository, enter it, and install the package in editable mode. {`git clone https://github.com/PUSHINGSQUARES/ARI-OS cd ARI-OS uv pip install -e .`} If you do not use `uv`, plain `pip install -e .` works the same way. For the optional media features, install the extra group with `pip install -e '.[media]'`. ## Run the installer The installer is a Python module. Run it as a module, not as a script. {`python3 -m ari_os.install`} The wizard accepts the following flags: - `--llm ollama|api|off` sets how recall is powered. The default is `ollama`. - `--ears` enables the optional listening surface. - `--lens` enables the optional vision surface. - `--no-mcp` skips automatic MCP registration. - `--dry-run` shows what would change without writing anything. - `--update` re-applies the latest managed files. - `--revert` rolls the managed changes back. - `--uninstall` removes everything ARI-OS placed. - `--purge-keys` clears stored keys, used together with uninstall. ## What it installs The installer writes a small, predictable footprint. It places: - 10 skills into `~/.claude/skills//SKILL.md`. - 10 command shims into `~/.claude/commands/.md`. - A statusline in `settings.json`. - A SessionStart hook. - A managed block in your `CLAUDE.md`. - An empty brain database at `~/.ari-os/brain.db`. - Timestamped backups in `~/.ari-os/backups//`. Everything it touches is captured in a backup first. Nothing is overwritten without a copy being kept. ## Connect the memory (MCP) Cortex is the local memory brain. The installer connects it for you. MCP auto-registration is on by default, so you do not need to do anything here. Pass `--no-mcp` if you would rather wire it up yourself. When auto-registration runs, it registers a server named `ari-os-cortex` into `~/.claude/.mcp.json`, `~/.codex/config.toml`, and `~/.gemini/settings.json`. To add it by hand, run: {`claude mcp add ari-os-cortex -- python -m ari_os.tools.cortex.mcp_server stdio`} There is more on how the brain works in the [brain](/documents/ari-os/brain) page. ## Keys Keys are read from environment variables first, and then from the macOS Keychain under the service `com.ari-os.keys`. They are never printed. This is the same principle as the rest of the install: nothing destructive, nothing leaked, and every action reversible. ## Verify Run the test suite, then open the monitor. {`python3 -m pytest -q python3 -m ari_os.tools.monitor`} The monitor opens at `http://localhost:7777`. If the tests pass and the monitor loads, the install is healthy. ## Reversible Every change is backed up first, so you can move forwards or backwards at any time. - `python3 -m ari_os.install --update` re-applies the latest managed files. - `python3 -m ari_os.install --revert` rolls the managed changes back. - `python3 -m ari_os.install --uninstall` removes everything ARI-OS placed. Add `--purge-keys` to also clear stored keys. The install is backed up and reversible. You can always go back. ## FAQ ARI-OS is version 2.0.0, released under the PolyForm Noncommercial licence. Next, learn how to drive it in [using it](/documents/ari-os/using-it). // --- ## What ARI-OS is URL: https://aris-space.com/documents/ari-os/overview Date: 2026-06-15 import { TaskVsWorkflow, Diagram, Pullquote, SurfaceList } from '@/components/blocks' ARI-OS is an orchestrator-first layer on top of Claude Code. It changes one thing, and that one thing changes everything: you stop doing the work and start directing it. You stay in the chair. You make the judgement calls. Background workers do the execution. The point is not to remove you from the loop. The point is to move you up a level, so your attention goes to shaping the outcome and judging the result, not to typing every step yourself. This is the core claim the whole system is built around. AI accelerates, it does not generate. The acceleration is real, and it is large. The taste, the standard, and the final yes remain yours. ## The loop Directing is not one action. It is a loop you run, again and again, at whatever pace the work needs. You define the outcome in plain language. You dispatch the defined work to background workers. You review what comes back. You ship only what passes. The same shape holds for a quick fix and for a week of building. Once the loop is familiar, the size of the task stops mattering. The loop is not a one-way pipeline. Review can send work back to dispatch. A weak spec sends you back to plan. That is the system working as intended. The judgement stays with you at every turn, and nothing ships until you say so. ## The four pillars Underneath the loop sit four pillars. Each one removes a different kind of friction, and together they are what make directing practical rather than aspirational. Spec-first is the discipline that makes everything else safe. If the outcome is vague, the work that comes back will be vague, no matter how fast it arrives. Writing the [spec](/documents/ari-os/using-it) first is how you keep the acceleration pointed at the right target. Background dispatch is what frees your attention. The execution happens on workers, detached from your session, so the slow part of the work does not hold your seat hostage. You can shape the next task while the last one runs. Handoff continuity is what lets the work outlive a single sitting. When a session ends, the thread is preserved, so the next session picks up where you left off instead of starting cold. The live local [Cortex brain](/documents/ari-os/brain) is the memory layer underneath all of it. It runs on your own machine. It reads and it writes, and it returns the past context that is relevant now, so the loop stays informed without you having to repeat yourself. ## What you need ARI-OS requires Claude Code. It is a layer, not a replacement, so it sits on top of an existing setup rather than standing in for it. If you already work in Claude Code, you already have the foundation. It is version 2.0.0, open-source under the PolyForm Noncommercial licence, at https://github.com/PUSHINGSQUARES/ARI-OS. One thing worth settling early is when to reach for a one-off task and when to build a repeatable workflow. The first is a single dispatch. The second is a shape you will run more than once, so it is worth defining properly. ## Where this goes You direct and review. The workers execute. That division is the whole idea, and once it is in place the rest is practice. You direct and review. The workers execute. Next, install it. The [install guide](/documents/ari-os/install) walks you through setting up the layer on top of your existing Claude Code. --- ## Using ARI-OS day to day URL: https://aris-space.com/documents/ari-os/using-it Date: 2026-06-15 import { Code, SurfaceList, WorkerFanOutFidget, Diagram, Pullquote } from '@/components/blocks' ARI-OS gives you one chair to work from. You direct from your main session, and the heavy work runs in the background. This page is the reference for the surface you touch every day: the slash commands, the skills, the Cortex memory tools, dispatch, the monitor, and the control panel. The shape is always the same. You stay in the conversation and set the direction. Workers run elsewhere and report back. AI accelerates, it does not generate. The judgement stays with you. If this is your first visit, start with the [overview](/documents/ari-os/overview) for the why, and the [install guide](/documents/ari-os/install) for the setup. ## Slash commands These run inside your main session. They are the verbs you reach for most. ## Skills Skills are the named capabilities the orchestrator can step into. A command often invokes the matching skill, but the orchestrator can also reach for a skill on its own when the work calls for it. ## The Cortex memory tools (MCP) The memory brain is exposed to your model through an MCP server named `ari-os-cortex`. The install guide wires this up for you. To register it by hand: {`claude mcp add ari-os-cortex -- python -m ari_os.tools.cortex.mcp_server stdio`} Once it is registered, your model can call these tools directly. The names are stable and the parameters are listed in full. `brain.see` and `brain.lens` are off by default. They switch on once LENS, and a local vision model for `brain.see`, are enabled. For the deeper memory workflow, how recall, consolidation, and regions fit together, read the [brain page](/documents/ari-os/brain). ## Dispatch background workers Dispatch is how one prompt becomes several workers running in the background. You write the brief, hand it off, and stay in your own session while the work happens elsewhere. To start a worker: {`python3 -m ari_os.tools.dispatch start --executor sonnet --task-file BRIEF.md --cwd ./worktree --label mytask`} A few rules keep dispatch safe and predictable. The executors are `haiku`, `sonnet`, and `opus`. Pick the smallest one that can do the job, and escalate only when the work demands it. Two extra flags shape what a worker can touch: `--add-dir` grants access to an additional directory, and `--read-only` runs the worker without write access. Dispatch refuses a git repository root as `--cwd`. Point it at a worktree or a subdirectory instead, so a worker can never act on the whole repository at once. Once workers are running, manage them from your session: {`python3 -m ari_os.tools.dispatch list python3 -m ari_os.tools.dispatch questions python3 -m ari_os.tools.dispatch answer --answer "..."`} `dispatch list` shows what is in flight, `dispatch questions` surfaces anything a worker is blocked on, and `dispatch answer` sends your reply back to a specific worker so it can carry on. ## Watch it run The monitor gives you one window onto every running worker, live. {`python3 -m ari_os.tools.monitor`} It opens at `http://localhost:7777`. Leave it running while you work, and you can see progress, questions, and completions without switching context. ## Control panel The control panel is the single command for configuring ARI-OS. {`python3 -m ari_os.tools.arios`} It takes these subcommands: - `keys` manages the API keys for any models you use. - `theme ` switches the visual theme. - `toggle on|off` turns a feature on or off. - `update` pulls the latest version. - `cortex [value]` configures the memory brain, where `setting` is one of `status`, `embeddings `, `mode `, `wander on|off`, `ears on|off`, or `lens on|off`. For example, to check the state of the brain: {`python3 -m ari_os.tools.arios cortex status`} And to switch the retrieval mode to focus: {`python3 -m ari_os.tools.arios cortex mode focus`} Each cortex setting changes what the brain pulls and how. The [brain page](/documents/ari-os/brain) covers the modes and embeddings in depth. You direct from the chair. The workers run in the shadows. That is the whole daily surface. When you want to understand what the memory layer is doing underneath all of this, the [brain page](/documents/ari-os/brain) is the next stop. --- ## Pushing Talk_: own your voice, own what it says URL: https://aris-space.com/documents/debugging/pushing-talk-finished-three-times Date: 2026-06-15 It recorded. It transcribed, word for word, perfectly. Then the text vanished. Nothing reached the field I was typing in. No error, no crash, no red flag. The recording worked, the transcription was flawless, and the one thing that mattered, the words landing where I wanted them, never happened. That is the most expensive kind of failure, because it looks like success right up until the last inch. Then the strangest part. I had granted the permission it needed. The settings pane showed a tick. And it still did nothing. I granted the permission. The system said yes. And nothing happened. ## Why I built it Every cloud dictation tool sends your voice to a server you do not own. I dictate client names, half-formed ideas, things I would never want sitting in a log I cannot see. I did not want my voice to be someone else's data. So I built one that keeps it on the machine I own. Permissions, privacy and trust are not plumbing you hide behind a product. On a tool that listens to your voice, they are the product. Every bug in this story is, underneath, a trust question wearing a technical costume. ## What I built It is called Pushing Talk_. Hold a key, speak, release, and your words land as text in whatever field you were already typing in. That is the entire interaction. It runs on macOS, and it is free. The part that matters sits underneath. The speech-to-text runs locally, on my machine and on yours, using a local Whisper model. No cloud. No account. No network call. Your voice never leaves your Mac. ## Own what it says Owning the app is half of it. The other half is owning what it produces. Cloud dictation rents you a transcription and keeps the original. Your words land in a log on a server you do not control, useful to whoever owns it, gone to you. When the dictation runs on my own machine, the words stay mine, and that changes what they are. They stop being throwaway text and start being a record. So I point them at a store I own. A private, searchable record of everything I talk out, that lives on my machine and answers only to me. No vendor sees it. No model trains on it. That record is the part I am most excited about. A spoken thought is the cheapest thing I make and usually the first thing I lose. Kept and searchable, it becomes something I can hand to my own assistant later. Find the thread I was pulling on last week. Draft from the note I talked out in the car. Connect two ideas I spoke a month apart. The voice is the input. The thing I own is the memory. None of that works if your dictation lives on rented infrastructure. A private store of your own thinking is exactly what a cloud product cannot let you keep. That is the whole reason to build it local. ## How I built it I did not type it out by hand in one sitting. I brainstormed the outcome, turned it into a plan, and the plan became the build. The code was written by Codex sessions running in parallel, each handed a tight slice of the work. Claude held the spec, dispatched the slices, reviewed what came back, and I made the calls. The judgment that ships is a separate job from the hands that build, and that split has its own write-up in [the Codex Loop](/documents/discipline-and-process/the-codex-loop). I never leave that loop. I decide what "done" means and I approve the result. The models accelerate the middle. They do not get to define the outcome. The system around the AI is the intelligence, not the model. Build with Codex. Ship with Claude. But built is not the same as working. I declared this thing finished three times before it actually worked, and each near-miss taught me a debugging principle that has nothing to do with dictation. Here is where it got hard. ## Beat one: instrument before you fix The symptom was "no paste," so the instinct is to open the paste code and start patching. I resisted that. The visible failure is almost never the cause. My first real move was not a fix. It was a light. I put a diagnostic log at every stage of the pipeline. Key pressed. Audio captured. Transcription complete. Text ready. Insertion attempted. Each stage stamped, so the path the data actually took became visible instead of imagined. The log answered the question in one run. Every stage up to insertion was clean, and the insertion itself never landed. Everything before the last step was innocent. ## Narration The log stamped every stage. Key, audio, transcription, text, all clean. Only the final handoff into the field failed. The bug was not in the pipeline. It was at the very last step. This is the oldest lesson in debugging, and it is table stakes. You have heard it before, so I will not dwell on it. The interesting part is what the light revealed. ## Beat two: the bug was not in the code To paste text into another app on macOS, an app needs an accessibility permission, the grant that lets one app put text into another. You allow it once, and from then on it should just work. I had granted it. The setting showed the tick. And it did nothing. The cause was the operating system's permission system, not my code. Earlier builds had each registered their own entry. Four stale permission entries sat in the list, ghosts of versions that no longer existed. On macOS, a permission is tied to a specific signed identity, and the build I was running matched none of them. The tick in the settings pane belonged to a build that was gone. So a permission that read as granted was, in effect, refused. The fix lived in app signing, five steps upstream from the symptom. The bug is rarely where you look first. And the cause itself is the thesis showing up as a defect. The system refused a capability because it could not confirm my app was who it claimed to be. ## Beat three: then it pasted three times I cleared the permission, and the text finally arrived. Three times. The same sentence, stamped into the field in triplicate. The paste logic I had written used a fallback design. Try one method of inserting text, and if it cannot confirm that method worked, try the next. The problem was confirmation. For some apps it could not read the field back to check whether anything had landed. With no signal that it had succeeded, the "stop on success" condition never fired, so every method ran in turn. Three methods, three pastes. A system that cannot confirm its own success will repeat itself. Unverifiable actions retry, duplicate, and corrupt, not because the code is careless but because it has no signal to stop on. The fix was not a better paste method. It was a real confirmation step. Design the check, not just the action. ## Beat four: the fix had become the bug Now the tool worked. It recorded, transcribed locally, pasted once, into the right place. By any normal standard, finished. Finished is where the embarrassing things hide. I ran the working tool through a proper security review, the way an attacker would, a panel of reviewers each attacking from a different angle. They did not find a flaw in my original design. They found a flaw in my repair. Remember the diagnostic log from beat one, the hero of the story. It had been writing previews of the transcribed text to a plain file on disk. And the raw audio captured for each dictation was never being deleted after transcription. For a tool whose whole promise is that your voice never leaves your machine, the scaffolding I built to debug it had quietly turned the inside of the machine into a place where your words sat in the clear. Neither was in my original product. Both arrived as helpers. I added the log to debug. I kept the audio to transcribe. The things I added to make the tool work had become the way it failed its one promise. The leak was not in the product. It was in the repair. Audit what you added, not just what was already there. Call it the self-inflicted bug. The failure you introduce while fixing a different one, hiding inside the thing you trust most because you just added it. Diagnostics write data. Retries repeat actions. Caches hold copies. The instruments you reach for under pressure are the additions least likely to get a second look, because they feel like helpers, not features. They are features. They ship. I caught and closed both in review, before any release. The log now stores no transcript content. The raw audio is deleted the moment transcription finishes. I made the promise true on the bench, instead of breaking it later in a stranger's hands. The question that found it was not "does it work." A working tool had already convinced me, its maker. It was "if I wanted to leak something through this, where would I go," asked by reviewers who did not build it and had no reason to flatter it. ## The payoff Pushing Talk_ is the example. These six principles travel to any system you build. 1. **Instrument before you fix.** You already know this one. You cannot fix what you cannot see, so make the invisible visible before you touch a line. 2. **The bug is rarely where you look first.** The symptom and the cause were five steps apart. Follow the evidence, not the instinct. 3. **A system that cannot confirm success will repeat itself.** Unverifiable actions duplicate and corrupt. Design the check, not just the action. 4. **The fix can become the next bug.** The self-inflicted bug is real. Audit what you added with the same suspicion you bring to the original code. 5. **"Working" is not "done."** Done is "I tried to break it and could not." A real review of a finished thing is where the embarrassing stuff surfaces, on your terms instead of a stranger's. 6. **Permissions and trust are part of the product.** On-device, signed, least-privilege. That is a feature you can name, not plumbing you bury. Read those together and one idea remains. Stop prompting, start defining outcomes. Decide what "done" actually means, then instrument toward it, including the helpers you brought in to get there. The close is not a feature list. It is the point. I built it free. I signed it, so the system and the person running it both know exactly what it is. It is least-privilege. The speech-to-text is local, so your voice never leaves your machine, the raw audio is deleted the moment it is used, and the debug log holds no transcript content, because once it did, and that was the bug. Trust is not what you do after the product works. On a thing that hears your voice, trust is the product. Everything else is just the button you hold down. What did you add to your last build to help it, and when did you last go back and check it was not quietly hurting? ## Get the beta Pushing Talk_ works, it is free, and right now the only way to get it is to ask. It is in private beta while I tune the last edges. Message me in the Clief Notes community and I will send you a copy. Tell me what you dictate into all day, because that is the part I am still shaping. [Message me on Skool](https://skool.com/cliefnotes) {/* --------------------------------------------------------------- ENRICHMENT TODO (not blocking the draft): - Live graphics on this page: hero dictaphone.png, the generated pipeline.png , and three interactive fidgets (PermissionGhosts, PasteCascade, SelfInflictedBug). The hero is a 4x nearest-neighbour upscale of the 256px app icon; swap in the original ~1254px dictaphone generation for extra crispness if Ari still has it. - Optional + for: accessibility-permission, code-signing, least-privilege, on-device (add entries to content/glossary.ts if missing). --------------------------------------------------------------- */} --- ## ARI-OS: set it up and use it URL: https://aris-space.com/documents/tools-and-plugins/ari-os Date: 2026-06-15 import { ARI_OS_PAGE } from '@/components/ari-os/provider-page' ## Set it up ## The surface ## Works with ## What you need ## Using it ## FAQ // --- ## I directed a website live, the way I direct a film set URL: https://aris-space.com/documents/workflows/direct-the-screen Date: 2026-06-16 import { Diagram, CrtKnockFidget, DialsToTokensFidget } from '@/components/blocks' I have directed film sets for years. Last night I directed a website the same way, and I never wrote a prompt. On a set you do not operate the camera. You watch the frame and call what it needs. Slower. Dirtier. Again. The crew has the hands. You have the eye. I ran a build the exact same way. A live page open on screen, an agent holding the hands, and me reacting out loud to what moved in front of me. One change. Watch it land. Call the next. **DIRECT THE SCREEN, DON'T PROMPT THE MODEL.** A prompt is a memo. You write the whole brief, fire it off, and hope what comes back is what you felt. Directing inverts it. You give one small note against a live render, you see it land the instant it changes, and the screen hands you the next note. What came out of it: a wall of twelve CRT monitors, each playing a showreel at a different second, scanlines and flicker and a teal glow. "Make the cursor knock the screens." Now a mouse sweep tears the signal, splits the colour, sometimes cuts a screen to black static, then it recovers on its own. "Dirtier." A pink and teal spark cracks at the pointer. A custom glitch typeface on the headline. None of it was written down up front. It emerged, note by note. This is not magic. Nothing builds itself. An agent built each change, I reviewed every frame, and I called every move. The taste was mine. The hands were not. The loop, if you want to run it: 1. Stand it up live and look. "Warmer" needs something to be warmer than. 2. One move per round, so your reaction maps to one cause, not five. 3. Make every value a named dial. Steer by feel, not by editing code. 4. The agent proves its own edit compiled before it says done. You stay free to just watch. 5. When a look locks, save it. The final dial values are your design system. The skill that runs this loop is open source. Take it: https://github.com/Pushing-Squares/art-direct Here is the part that stuck. You cannot write a feel down. A brief is a guess at an aesthetic you have not seen yet. The eye only knows once the live thing is moving in front of it. So stop trying to specify the feel. Build a loop fast enough to react inside. The model can hold the hands. Only you can hold the loop. What have you been trying to brief, that you should be directing live instead? Stop prompting, start defining outcomes. // A\<3 --- ## Plan Like You Mean It URL: https://aris-space.com/documents/discipline-and-process/plan-like-you-mean-it Date: 2026-06-21 ## The slot machine Most people drive AI like a slot machine. They type a vague wish, pull the lever, and hope. The output comes back wrong, so they reword the wish and pull again. Then again. Three hours later there are forty messages in the thread, a tangle of half right code, and no clear memory of which version was the good one. That is not building. That is gambling with extra steps. The reflex is to blame the prompt. Write a cleverer prompt, get a cleverer result. It is the wrong lesson. The problem was never the sentence. It was the absence of a plan. Here is the thing nobody says out loud. AI accelerates, it does not generate. Point it at a clear target and it will close the distance frighteningly fast. Point it at a vague one and it will accelerate in a random direction, which is just a quicker way to get lost. > The fix for a bad output is almost never a better prompt. It is a better definition of done. ## Stop prompting, start defining outcomes A prompt describes a wish. An outcome describes a result you could check. The gap between those two things is the entire game. When I start something now, I do not open a chat and start typing instructions. I open a conversation whose only job is to decide what we are actually building. What does done look like. What must be true. What is explicitly out of scope. None of that is code. All of it is the part that makes the code come out right. This is slower for about twenty minutes and faster for the rest of the project. You trade a vague head start for a clear finish line. ## The chain The method is a short chain, and each link feeds the next. **1. Brainstorm before you build.** Run a real interrogation of the idea first. Not "what should I build", but "what are we actually trying to make true, and what would break it". I use `/brainstorm` for this, one question at a time, until the fog clears. The output is a shared understanding, not a to do list. **2. Freeze it in a spec.** A spec is the brainstorm, written down and made hard to argue with. Objective in one falsifiable sentence. Constraints that bound the solution. A definition of done where every item can be checked with a single action. If you cannot write that sentence, you are not ready to build, and now you know it cheaply. **3. Break the spec into a phased plan.** A plan turns the spec into ordered, bite sized phases. The discipline that matters most here is sizing. Each phase has to be small enough to carry start to finish in one sitting, with room to spare. **4. Hand each phase over as a typed brief.** This is the part that does the heavy lifting, so it gets its own section. ## The typed brief is where the magic is A typed brief is a product requirements document, scaled down to whatever you are making. It is the difference between "build me a settings page" and a short document that states the goal, the constraints, the acceptance criteria, and the phases. It feels like bureaucracy. It is the opposite. The brief is a forcing function. You cannot write acceptance criteria for a feature you do not understand. You cannot list constraints you have not thought about. The act of filling in the fields drags every fuzzy assumption into the light while it is still free to fix. Play with the toggles below. Watch the output sharpen as each field of the brief gets filled in. The model did not get smarter between the first state and the last. The brief did. That climb is the whole argument in one widget. Vague in, generic out. Specific in, on spec out. The leverage was never in the prompt. It was in the definition. ## One phase, one session The other half of the method is sizing. A plan is only good if each phase actually fits. Fits what? A single session. A model holds a working memory, a context window, and it is finite. Cram an entire project into one session and quality falls off a cliff long before you hit the wall. The model starts dropping detail, contradicting earlier decisions, losing the plot. You can feel it happen. Slice the same project into phases that each fit comfortably inside one session, and every phase ships clean. The work is identical. The packaging is everything. Drag the load into the gauge below and watch what happens. This is why the plan and the brief are partners. The plan decides where the cuts go. The brief makes each slice executable on its own. Together they let you build something large without ever asking one session to hold all of it. ## Why this works, the part nobody tells you The obvious payoff is that the output is drastically better, and it is. But the real prize is quieter. Writing the brief makes you understand your own design. By the time I have written a spec and sliced it into briefed phases, I have already found the contradictions, the missing decisions, the bit I was hand waving. I found them at the desk, in plain English, where they cost minutes. Not three hours into a build, where they cost the build. So the plan is not the thing you do before the work. The plan is the work. The building is just the part that is easy to delegate once the thinking is done. ## The boring habit None of this is clever. It is a brainstorm, a spec, a plan, and a brief. It is the boring habit underneath everything that ships. Stop prompting. Start defining outcomes. Then watch how little re prompting you have to do. // --- ## Loop Engineering + ICM aren't a duo. They're one machine. URL: https://aris-space.com/documents/workflows/loop-engineering-vs-icm Date: 2026-06-22 import { Diagram, Download, Pullquote, BoardBreatheFidget, ReadWriteDialFidget, V3TeaserFidget } from '@/components/blocks' {/* gpt-image-2 prompt: "A single mechanical flywheel, clean technical illustration on the site's background. The wheel's TEETH are labelled folder tabs reading 01_inbox, 02_doing, 03_done, _board.md. One continuous arrow loops around driving the wheel. Title feel: 'one machine, not two'. Minimal, confident, on-brand with aris-space heroes." */} Someone in here asked a sharp question this week: are Loop Engineering and ICM a perfect match, or two completely different things? Neither. They're one machine people keep mistaking for two. Here's the split everyone starts with, and it isn't wrong: Loop Engineering = how the agent acts. The autonomous cycle of execute, verify, self-correct. ICM = where the agent lives. Transparent folders and markdown that hold the context. But "where it lives" is carrying way more weight than it gets credit for. A folder structure isn't storage. It's the loop's memory between iterations. Think about what "self-correct" actually requires. A loop corrects by reading state, acting, then re-reading what changed. If that state only exists in the model's context window, it evaporates the moment the loop restarts or the window rolls over. If it lives on disk as plain readable markdown, the loop can check itself against it on every single pass, forever. So the whole relationship collapses into one line: A loop can't verify what it can't read back. ICM is the thing it reads back. That was always the connection. It was never two tools. {/* gpt-image-2 prompt: "Side by side. LEFT: a loop arrow spinning in empty space, faded, labelled 'blind loop, retries'. RIGHT: the same loop arrow reading from and writing to a stack of labelled markdown files, crisp, labelled 'stateful loop, corrects'. Clean technical diagram, on-brand." */} Let me kill the three framings from the original question: **1. "Do they intertwine?"** Not as a duo. As one organism. The loop is the metabolism. ICM is the body. Run a loop on a messy structure and it doesn't degrade slowly, it degrades faster, just more legibly. **2. "Can Loop Engineering be the framework FOR ICM?"** Flip the arrow. Moving a file from 01\_inbox to 02\_processing isn't the loop driving ICM. It's the loop using ICM as its scoreboard. The folder a file sits in IS the loop's current state. Moving it is the loop committing a decision it can audit on the next pass. **3. "Or are they for completely different use cases, automation vs human-readable?"** That's the exact split you want to collapse, not protect. The whole point of transparent folders is that the autonomous loop AND the human read the same files. That's what lets you stay ON the loop instead of IN it. Delete the transparency and you're back to babysitting a black box. Not magic, to be clear. ICM doesn't make the loop smart. It makes the loop's mistakes recoverable. I still read the board every time. Here's the build-it-today version. Five things in a folder: ``` 01_inbox/ new work lands here 02_doing/ loop pulls ONE item here and works it 03_done/ loop moves it here once it verifies _board.md loop rewrites this every pass, status of everything _needs_me.md loop parks anything it's unsure about ``` {/* gpt-image-2 prompt: "A clean schematic of five items in a folder (01_inbox, 02_doing, 03_done, _board.md, _needs_me.md) with a 4-step loop arrow beside them: read board, pull top of inbox, do+verify+move, rewrite board. Technical, minimal, on-brand." */} And the loop rule, four lines: read \_board.md, then pull the top of 01\_inbox into 02\_doing, then do it, verify it, move it to 03\_done (or \_needs\_me), then rewrite \_board.md and go again. That's the whole thing. The folders are the state. The loop is the cycle that reads and writes that state. You never watch it run. You read \_board.md, the same file the loop writes. That is Loop Engineering and ICM being the same machine. The law underneath all of it: An autonomous loop is only as smart as the state it can read back between iterations. Stateless loops don't correct. They just retry. ICM is the state. You don't get to pick one. Question back to the room: where do you draw the line on what your loop is allowed to WRITE vs only READ? That boundary is exactly where my loops either earn trust or lose it. //A<3 --- --- ## I run 100-agent workflows on a budget model. Here's the catch. URL: https://aris-space.com/documents/workflows/swap-the-orchestra Date: 2026-06-22 import { Diagram, ProviderCostDial, WorkflowAnatomyAnim, SwapOrchestraAnim } from '@/components/blocks' Last night I dispatched 235 agents to review a codebase. The model wasn't Claude. The harness was. Claude Code ran the whole thing. The model underneath was a budget one. Here is the thing nobody tells you about dynamic workflows. They are not a model feature. They are a harness feature. Claude Code has a mode called UltraCode, and UltraCode runs the dynamic workflows for you. Turn it on and it fans out tens or hundreds of agents by default, runs them in parallel, verifies each finding adversarially, then synthesises the survivors. That whole dance is orchestration Claude Code performs. The model just fills the seats. Which is also a cost bomb. Automatic fan-out to hundreds of agents on a premium model is a serious bill arriving by default. So I started renting the conductor and swapping the orchestra. The conductor is Claude Code, the harness: UltraCode, dynamic workflows, dispatch, the fan-out and verify loop. That stays fixed. The orchestra is the model underneath, and the model is swappable. Claude is one player you could seat. GLM and MiniMax are others. Point the same harness at a cheaper provider, GLM or MiniMax, and you keep the orchestration while the token bill collapses. Same UltraCode, same automatic dynamic workflows, a fraction of the bill. You utilise the same UltraCode, you just stop paying premium rates to run it. Now the catch, because there is one. You do not get all the benefits. A cheaper model reasons worse per agent. One GLM agent is not one Opus agent. What you are buying is the right to run fifty of them for the price of one, and to let structure do the work the raw model cannot. That is the trade. Depth per agent goes down. Breadth goes way up. And the workflow shape, fan-out then adversarial verify then synthesise, claws most of the quality back, because three cheap sceptics catch what one of them misses. The numbers from one run: 1. 235 agents, fanned out across the workflow. 2. 13.12 million tokens between them. 3. On premium token rates, that is a serious bill. On the budget orchestra it was a fraction of it, roughly a tenth. 4. Same workflow. Same fan-out. Same verify pass. What you can build today: 1. Turn on UltraCode. You do not hand-build the dynamic workflows, UltraCode runs them for you, fanning out the fan-out then verify then synthesise shape by default. 2. Point Claude Code at a budget model, GLM or MiniMax. This is the move that lets you utilise UltraCode without the premium bill. 3. Run the same UltraCode workflows and watch the structure carry the cheap model. The sceptic's objection is fair, so I will say it plainly. This is not magic and it is not free. I still review everything. The cheap model still gets things wrong. But the unit economics of being wrong cheaply, in parallel, then voting on the survivors, beat being right expensively, alone. The principle that outlives the tool: The orchestration is the intelligence. The tokens are a line item. Configure the conductor once. Hire whichever orchestra you can afford. --- ## You don't buy roads. You lay them. URL: https://aris-space.com/documents/workflows/lay-your-own-roads Date: 2026-06-24 import { Diagram, Download, Pullquote, PortableContextFidget, SharedBoardFidget } from '@/components/blocks' {/* gpt-image-2 prompt: "A clean technical illustration of a city built in four stacked, clearly LABELLED layers, on the site's cream background. Bottom to top: a layer labelled 'MODELS / the land' drawn as plots of soil; above it 'HARNESSES / storefronts' drawn as small shopfronts; above it 'ROADS / portable context' drawn as roads connecting the shopfronts; at the top 'CITY GRID' where everything connects. Minimal, confident, exact labels in order, on-brand with aris-space heroes." */} Everyone argues about which model is best. GPT, Claude, Gemini. Almost nobody can tell you the layers their AI is actually standing on. So here is how the thing you use every day actually works. Picture it as a city. At the bottom is the land. The models. The raw intelligence. On their own they can only talk. They cannot do anything. On top of the land you get storefronts. The harnesses. These are the tools that let a model actually act. Read your files, run code, search the web, remember what happened last time. When you say you are "using AI," this is almost always the layer you are touching. Not the model. The storefront built on top of it. Here is the catch most people never feel until it bites them. The storefronts do not talk to each other. Your context, your history, your setup, none of it travels. Switch tools and you start from zero on a fresh plot of land. So the layer everyone is now chasing is the roads. The connective bit. The thing that lets your work move between tools, lets you hand it off, lets you build pipelines on top instead of babysitting one chat at a time. That is the part I want to talk about. Because you do not have to wait for someone to sell you the roads. That is ICM. We have been laying those roads out of numbered folders and plain markdown the whole time. > Your context travels between tools. Copy the folder. > Anyone can change the pipeline. Open a markdown file. > Hand the whole thing to a teammate. Send them the folder. No platform. No deploy. No lock-in. A workspace is a folder, and a folder goes anywhere. {/* gpt-image-2 prompt: "Side by side technical diagram on cream background. LEFT panel labelled 'RENT THE HIGHWAY': a large tollgated corporate highway with a toll booth, a few tool icons queuing to pay. RIGHT panel labelled 'PAVE YOUR OWN ROAD': a simple hand-laid road built from stacked folder and file cards labelled 'CONTEXT.md', '01_stage', 'output' connecting the same tool icons directly, no toll. Clean, minimal, exact labels, on-brand." */} And once the road is yours, you build on it. Run stages in parallel. Have one model check another model's work. Ask two models the same question and compare. None of that needs a framework. It needs structure you can read. ICM does not do everything, and it does not pretend to. Real-time, high concurrency, fifty agents talking at once, that is a framework's job and ICM says so out loud. But most work is not fifty agents. Most work is five stages and a human who wants to see each one. You do not buy roads. You lay them. So the next time someone tells you the roads are a thing you buy: you do not buy roads. You lay them. The most portable road ever built is a folder full of markdown, and it already drives everywhere. > Stop renting the road. Start defining the route. Where are you still paying for something a folder would do? //A<3 --- ## The Output URL: https://aris-space.com/documents/doctrines/the-output Date: 2026-07-03 # The Output **Output isn't what you ship. It's what you push forward.** This is a doctrine for people who build with machines that build. Drafted with an AI accelerator. Hiding that would be the first lie: the essay would rot from the first line. A confession, because the doctrine dies if I hedge it: I am dyslexic, I am not fast at prose, and most of the sentences here were shaped in conversation with a model that can hold a sentence while I hold the idea. That is not a disclaimer. It is the same law this essay describes. The strong thing does not do the work. The strong thing conducts. --- ## 1. The Wing For as long as I have built things, the strongest tool in the room did the hardest work with its own hands. The best model wrote the best code. You spent your best intelligence on your hardest lines. That was the whole idea. That is over. The strongest model I have does not write the code any more. It conducts the ones that do. It sits above the work, not inside it, and points: this piece to that model, that piece to another, all of them running at once. The best intelligence I have is too expensive to spend on typing, so it stopped typing. It picked up a baton. This is not a faster typist. It is a conductor. And on my side of that baton, the change is mine. I stopped making the work by hand. I started directing a fleet that makes it. That is the lift, and it is not more speed at the keys. It is a different seat entirely. The typing left the chair. The judgement stayed in it. --- ## 2. The Proof Here is one week. The week this doctrine was written. Zero posts published. Old unit says dead week. Real unit says biggest week yet. The grid did not wait for a gate. **715 commits** landed, and I will be honest about them, because this doctrine is worthless if the numbers lie. Roughly 328 are feature work, 61 are tests, 50 are fixes, and about 135 are chore commits, many of them automated bookkeeping. The remaining one-hundred-odd are merges, docs and miscellany. The real feature floor is closer to 440. I am not going to round up. The number is still enormous for one human and a fleet of machines. Behind those commits, roughly **640 background jobs** started. Not all delivered clean. Some retried. Some failed on startup. Some got sent back. 640 is jobs *started*, not jobs that landed. Starts are not wins. State the gap plainly: it is the engine breathing, not the engine failing. And in that same window, one model went from scoring one out of five on a hard ordering task to five out of five, by teaching itself. It could not do the thing on Monday. It could by Friday. Nobody fixed it. That skill is permanent now, and it is output no feed will ever show. A phone photo editor booted for the first time. A desk cockpit shed a two-second lag on every keystroke. An 8,943-line depth pipeline merged clean. Local image generation came online. The publishing machine itself, the thing that will one day ship the posts, got torn down and rebuilt underneath me as a compiled browser engine. Zero posts. The grid advanced on nearly every front. This is not a flex. It is a receipt. Stop counting posts. Start counting squares pushed. --- ## 3. How You Fly The mechanism is the part you can take. The harness is Claude Code. On top of it, UltraCode fans a single model into dozens, each copy working in its own parallel worktree. Many hands, one instrument, all playing at once. Not a queue. A section. Above them sits the conductor: the strongest model I have, Fable. It does not play. It plans the task, splits it into pieces, and routes each piece to the cheapest model that can hold it. Prose to Claude. The build to Codex. The long cheap grind to GLM. Vision to MiniMax. Every lane runs a different model pushing a different square. None of this is a private trick. The harness is public. The fan is public. The routing is a file you could write tonight. So picture your own fleet. One seat that decides. A dozen cheap seats that do. The work stops being what you can type before you sleep. It becomes what your routing can push while you do. --- ## 4. The Routing Is The Moat The strong model is not the ceiling. Here is the part that broke my brain when it proved out: the conductor is itself swappable. I put the same conducting seat on GLM plus a cheap coding model, and the grid still moved. Not because Fable is weak. Because Fable was simply the first model strong enough to prove that the conducting was the thing all along. Once you can see the conducting, you can hand the baton to cheaper hands. That is the whole inversion. The expensive model's real job is to make itself optional. It writes the routing, proves the routing, then steps aside while cheaper models run inside it. The conducting becomes a file. The file becomes a line in a budget. The line goes down. The intelligence is not the model. It is the routing. The tokens are a line item. So my output is not bounded by the model I can afford. It is bounded by the routing I can build. The model is a hiring decision. The routing is the company. Any single model, even the strong one, is a budget question. The routing is the moat. --- ## 5. Measure What Moved So measure the right thing. Everyone watches the posts. The posts are the last five percent. The publishing gate opens later, and when it opens the posts come fast, because most of what is behind them is already built. But the gate was never the work. The work was the ninety-five percent nobody watched. The engine is the output. The posts are a valve on it. Measure the commits, counted honestly, chores called out and starts kept separate from wins. Measure the capabilities unlocked. Measure the walls moved a row over. Measure the routing getting denser, the conductor getting cheaper, the fleet getting louder. A square is the smallest unit of forward motion. A commit. A capability. A wall moved a row. Output is the squares that moved since yesterday, whether or not a single one of them showed its face. --- ## Close Output isn't what you ship. It's what you push forward. Stop counting posts. Start counting squares pushed. --- ## Stop handing context to your agents. Pack it. URL: https://aris-space.com/documents/dispatch/context-pack-dispatch Date: 2026-07-06 import { DispatchFlowDiagram, ContextPackAnatomy, RoutingMap, NeedleExtractorFidget, Download } from '@/components/blocks' Hand a cheap model a task and it re-reads everything, or confabulates the one ID that actually mattered. So I pack it instead. A **Context Pack** is one file: exact needles (ids, paths, values) kept verbatim, the bulk gisted, sized to half the model's window. Workers read what matters and re-fetch the rest. A manager routes each task to the cheapest Claude tier that can do it, on your subscription, never metered. Small jobs go direct. Big ones fan out under a cheap large-context model that reassembles the result. I shipped this repo by pointing the tool at itself. It said "12 ok". I believed it only after diffing every file, because a workflow once told me "ok" for work it never ran. Verify the behaviour, not the tally. The whole thing is MIT and built with Claude: [github.com/PUSHINGSQUARES/Build](https://github.com/PUSHINGSQUARES/Build). {/* RELATED, once published as MDX: context-is-the-product and reading-swarm are strong siblings but exist only as Skool drafts today. Add them to the related list when they are scaffolded. */} --- ## Port the site. Keep the conductor. URL: https://aris-space.com/documents/dispatch/the-conductor-never-moved Date: 2026-07-12 import { Diagram, Download, Pullquote, SwapOrchestraAnim, WorkerFanOutFidget, ProviderCostDial } from '@/components/blocks' I moved my whole site between hosts this week. The model that planned the move never executed a single task of it. Fable planned it, sitting at the gate. The migration itself, the wrangler config and the adapter and the DNS cutover, was executed by a swarm of cheaper models, each routed to the one slice of work it could do. ## Rent the conductor. Swap the orchestra. The conductor is the harness and the routing. The orchestra is the model, and it is swappable. Here Fable held the baton and budget lanes played the parts. Elsewhere the conductor seat itself is a cheap large-context model: one is running 34 parallel workers for me right now, another wired the grok fleet that shipped ten landing pages overnight. The intelligence is the routing, not any single model. Two caveats, honestly. It was a day and a morning, not a day: preview green before dinner, production flipped the next morning. And I sat at every gate. Nothing ships itself. The port is not the point. The point is the expensive thinking and the cheap doing have been peeled apart, and you route each to whichever model earns it. What is the one job you would hand to the cheapest model that could do it, if you stopped insisting the smartest model do everything? //A<3 --- ## Build it today The two artefacts below are the load-bearing parts of this build, redacted of secrets. The pattern they encode: **one** conductor (the harness, the routing, the gates) and **many** swappable workers (the cheapest model that can do each slice). The conductor never moves. The orchestra is rented by the hour. --- ## The model is a dial URL: https://aris-space.com/documents/tools-and-plugins/the-model-is-a-dial Date: 2026-07-14 ## Narration A model selector sits inside a larger control panel. Effort, context, tools, persistence, and review each have their own control. An outcome contract enters on one side. A checked result leaves on the other. Frontier models changed the useful abstraction level of prompting. The stronger the model becomes, the less value there is in narrating every turn of the route. The leverage moves upward: define the destination, specify the evidence, state what failure looks like, and make the review boundary explicit. That does not mean prompts should become vague. It means precision belongs in the outcome contract, not in a speculative list of keystrokes. _AI-assisted: This page was developed with AI as an accelerator. The thesis, framing, and final approval remain human decisions._ The second shift follows from the first. Model selection is not a prestige ladder. It is effort allocation. Spend deeper reasoning where ambiguity, failure cost, synthesis, or time horizon require it. Use the smallest sufficient profile everywhere else. ## Prompting moved up an abstraction layer Early prompt engineering often treated the prompt as a route description. Open a file. Find a function. Add a branch. Run a command. Return a summary. That structure can still help with deterministic or brittle work. It is also a low abstraction level. The person writing it must predict the implementation path before the model has inspected the environment. Every route decision embedded in the prompt becomes a decision the model cannot improve without first disobeying the prompt. A brief moves one level up. It defines the goal, constraints, and acceptance criteria, then leaves the route open. An outcome contract moves higher again. It defines not only what should exist, but also how the result earns trust. The shift is from **route precision** to **outcome precision**. Route precision says which steps to take. Outcome precision says what must be true when the work is finished. A capable agentic model can search, inspect, test, and revise its route. It cannot infer an unstated audience, an invisible failure condition, or who has authority to approve the result. Those remain contract work. ## An outcome contract is not an outcome wish "Build a polished page" is an outcome-shaped sentence, but it is not a contract. It has no evidence standard, no boundary, and no definition of failure. The model can produce something that looks complete while leaving every important judgment unresolved. A useful outcome contract carries six fields. - **Result.** The observable thing that must exist. - **Audience.** The person or system the result must serve. - **Constraints.** The boundaries the route cannot cross. - **Evidence.** The tests, sources, measurements, or artefacts that prove the result. - **Failure conditions.** The states that must block completion, even if the output looks plausible. - **Review gate.** The person or independent process that can accept the work. Here is the compact template. ```yaml outcome_contract: result: "What must exist when the work is finished" audience: "Who or what must be able to use it" constraints: - "A boundary the route cannot cross" evidence: - "A test, source, measurement, or inspectable artefact" failure_conditions: - "A state that blocks completion" review_gate: "The independent check or human approval required" ``` Notice what is missing: a compulsory implementation transcript. The model still needs relevant context, references, and interfaces, but it can choose the route after inspecting them. You define what earns acceptance. It works backwards from that acceptance state. This is the freedom of a tight brief. The model has room to solve the path because the destination does not move. ## Model choice is effort allocation Once the prompt is an outcome contract, model choice becomes easier to reason about. You are no longer asking which model is best in the abstract. You are asking how much cognitive and operational effort this contract needs. Four variables do most of the work. ### Path ambiguity How many viable routes exist, and how much discovery must happen before one can be chosen? A known transformation over a known file has low path ambiguity. A cross-system architecture decision has high path ambiguity. High ambiguity pays for synthesis because the route itself is part of the problem. ### Failure cost What happens if the result is wrong? A reversible draft can tolerate a cheap first pass. A destructive migration, public claim, or production decision needs a more cautious profile. Failure cost is not the same as task size. A one-line change can carry a large blast radius. ### Time horizon How long must the model preserve intent across decisions? A single-turn transformation has a short horizon. A build that inspects, edits, tests, diagnoses, and revises has a longer one. Long-horizon work consumes more of the context window and benefits from stronger state management, whether that comes from the model, the surrounding files, or both. ### Reviewability How quickly can another process detect a bad result and reverse it? Strong tests and clean diffs lower the effort required for an initial attempt because mistakes surface cheaply. Weak observability raises the required effort. If a result cannot be reviewed, the model has to carry more of the assurance burden before acting. The profiles in the matrix are operating shorthand. | Profile | Useful shape | |---|---| | Haiku with light effort | Bounded, reversible, short-horizon work with a clear check | | Sonnet with standard effort | Moderate synthesis, familiar implementation, and visible review evidence | | Opus with deep effort | Ambiguous synthesis, high failure cost, or decisions that shape a long chain of work | | Codex with high effort | Tool-led implementation where repository inspection, code changes, and verification dominate | This is not a universal ranking, and it does not claim literal equivalence between providers. Haiku, Sonnet, Opus, and Codex name useful working profiles here. The right profile depends on the contract and the environment around it. ## The model is only one control A model picker compresses several separate decisions into one brand name. That is operationally weak because changing the model is not the only way to change capability. You can change the thinking effort. You can provide a larger or tighter context. You can grant tools. You can persist state across turns. You can require a fresh audit or human approval. These controls are orthogonal. A high-effort model with no evidence can spend more tokens producing a slower guess. A lighter model with a narrow contract, relevant files, deterministic tools, and a strong review gate can outperform it on the actual outcome. This is why model selection should happen after contract design. The contract tells you what kind of uncertainty remains. The surrounding controls tell you which uncertainty the model must carry itself. ## A practical allocation method Use this sequence before choosing a model. **Define acceptance first.** Write the result, audience, evidence, failure conditions, and review gate before discussing the route. **Classify the uncertainty.** Separate uncertainty about the destination from uncertainty about the path. Destination uncertainty is a briefing problem. Path uncertainty is a reasoning problem. **Price failure.** Ask what a plausible but wrong result would cost. Include reversal cost, public exposure, data loss, and downstream work built on the decision. **Inspect the environment.** Count the useful context, tools, tests, and checkpoints already available. A furnished environment reduces the amount the model must invent or remember. **Choose the smallest sufficient profile.** Start with the lowest effort that can carry the remaining ambiguity and failure cost. Raise it when the contract demands more, not because a larger model is available. **Spend review separately.** Model effort and review effort solve different problems. Deeper reasoning reduces some errors before action. Independent review catches errors the same reasoning process cannot see. The result is a system that can dial effort up without leaving every control at maximum. That matters because excess effort has a cost in latency, tokens, attention, and throughput. ## Common failure modes ### Maximum effort as a default This spends time on tasks whose route and check are already obvious. It also hides weak contracts because the model appears busy. If the acceptance state is vague, more reasoning does not make it precise. ### Model choice before contract design Picking the model first encourages post-hoc justification. Define the work, then allocate the profile. Otherwise every task mysteriously grows to fit the most prestigious option. ### Outcome language without evidence Replacing steps with a vague destination removes useful structure without adding assurance. An outcome contract needs evidence and failure conditions. Without them, it is only a wish with a heading. ### One control standing in for the whole system Changing the model cannot compensate for missing context, absent tools, no persistence, or a weak review gate. Treat those as separate controls so each can solve the problem it actually owns. ## The rule Explain less of the route. Define more of the outcome. Then choose the smallest sufficient effort for the ambiguity and failure cost that remain. The model is a dial. The contract is the control surface. ## Source note The model names on this page label operating profiles drawn from practical use. They are not benchmark claims, a provider ranking, or a claim that the models are equivalent. The allocation method is based on task ambiguity, failure cost, time horizon, and reviewability. --- ## Work YOUR Way With Pi URL: https://aris-space.com/documents/workflows/work-your-way-with-pi Date: 2026-07-21 import { AgentRoutingFidget, EvidenceBeforeCompletionGraphic, ParentSeatContractGraphic, PiKernelGraphic, ReasonPerformDoGraphic, Download } from '@/components/blocks' ## Pi Is The Kernel Pi is deliberately small. It gives you a stable harness for an agent, then leaves the surrounding system open to design. That distinction matters because the useful part of an agent system is rarely a single model call. It is the contract around the call: what work enters, who owns the decision, what evidence returns, and when the system must stop. Tools, skills, extensions, provider choice, and agent conventions can sit around that kernel without becoming the kernel. The result is a system that can change its working parts without forcing you to rebuild the conversation layer every time a tool changes. Minimal extensibility is not an empty starting point. It is a boundary. Keep the stable core responsible for the smallest possible set of guarantees, then make the policy around it visible, inspectable, and owned by the operator. ## The Parent-Seat Contract The parent seat stays with the human. It receives the outcome, interprets constraints, decides what can be separated, and retains the context that makes the work coherent. A parent agent is not a queue manager that disappears once it has handed out tasks. It is the reviewer of the whole system. Specialists receive bounded work. A useful specialist brief names one outcome, the constraints that shape it, the evidence expected at closeout, and the stop condition. It should not require a specialist to infer hidden priorities or make a decision that belongs to the human. That split protects both sides. The parent can keep the long-lived conversation and the responsibility for tradeoffs. The specialist can concentrate on a small surface, return an artifact and concise findings, then surface a blocked decision instead of silently expanding scope. ## Route The Work, Not The Prestige Reason, Perform, and Do are descriptions of work, not rankings of intelligence. **Reason** is for high-consequence work, deep ambiguity, architecture, and hard debugging. It should identify assumptions, compare viable options, and make the cost of being wrong explicit before a decision moves forward. **Perform** is for substantive implementation inside a clear brief. The work may involve several coordinated changes, but the outcome and the boundary are known. Its closeout should show the changed artifact, a targeted check, and any conflict that needs a parent decision. **Do** is for bounded, repeatable work such as classification, parsing, routine transforms, routing, and basic boilerplate. It needs a stated rule and a sample check. If the rule becomes ambiguous, it stops being Do work. Route by **consequence** and **complexity** together. A simple action with irreversible consequences belongs in Reason. A complex but reversible task may belong in Perform. This avoids the prestige trap of sending every task to the most capable seat, even when a smaller, inspectable process is safer and easier to review. ## Evidence Before Completion An agent saying it is finished is a claim, not a completion event. The parent closes work through one explicit loop: `claim → artifact check → test or inspection → accept / retry / escalate` First, confirm the claimed artifact exists and matches the requested shape. Then run the relevant test or inspect the output against the stated constraint. Only then can the parent accept it, send it back for a targeted retry, or escalate the unresolved question. This is not bureaucracy for its own sake. Agent systems can produce detailed reports that sound complete while the expected file, change, or behavior is absent. Evidence keeps completion grounded in a thing another person can inspect. The human remains the authority for judgment-heavy and irreversible decisions. The parent can frame options and expose failure modes. It cannot quietly convert a decision about risk, intent, ownership, or consequence into a technical default. ## Build Your Own Parent Seat Start with one parent seat and a small number of specialist contracts. Write down the outcome, boundary, evidence, and escalation rule before you add more automation. The system becomes trustworthy through clear handoffs, not through a larger pile of autonomous steps. The starter below contains the public version of that contract: specialist boundaries, tier routing, evidence requirements, and escalation rules. Adapt the language to your own work, then make the parent responsible for checking what the specialists return. --- ## Save For Later URL: https://aris-space.com/documents/tools-and-plugins/sfl Date: 2026-07-22 import { SflGate } from '@/components/sfl/SflGate' import { S7Window } from '@/components/blocks/s7window' # Save For Later Most brainstorms end the same way. A long chat. Maybe a design doc. Then the tab closes. Next session, you re-explain the campaign from scratch. A sub-agent gets a vague brief and invents constraints you already rejected. The "don't do X" line that took twenty minutes to discover is gone. That is not a model problem. It is a continuity problem. **SFL - Save For Later** is a small skill that upgrades brainstorming with a living project pack: one place where locked decisions, rejected approaches, subtleties, and handoff notes accumulate for the life of a campaign. ## Two densities, one truth | Who | Density | |---|---| | You / next main session | Full pack | | Sub-agent / worker | Thin slice | The full pack is skimmable human continuity: status, intent, decisions, open threads, subtleties, handoff notes, file index. The thin slice is task-shaped: mission, MUST, NEVER, exact needles, paths to open. Nothing else. Workers should never become a second author of campaign truth. They write receipts if you want them; they do not invent the spine. ## The pack spine Every campaign pack uses the same sections: 1. **Status** - phase, next action, blockers 2. **Intent** - why this exists 3. **Decisions** - dated locks and rejections 4. **Open threads** - unresolved forks 5. **Subtleties** - promoted nuance only (not raw chat) 6. **Handoff notes** - if you pick this up now 7. **File index** - load-bearing paths 8. **Changelog** - what changed in the pack You can maintain that by hand in markdown. The shipped helper also keeps an append-only event log and re-renders the pack so you do not lose history while editing the view. ## Brainstorm upgrade, not brainstorm replacement If you already use a structured brainstorming discipline, SFL runs beside it: 1. Name the campaign early. 2. Birth a pack (or adopt mid-flight from existing design notes). 3. Every locked decision or rejected approach gets **promoted** into the pack. 4. When you park, the handoff lives **inside** the pack. 5. When you write the design and plan, point the file index at them. The design doc and plan stay the build contract. The pack is continuity and nuance around them. ## Hard gate This matters enough to say twice. A pack is **not** permission to build. If your brainstorming method has a hard gate before implementation, keep it. SFL does not cross that line for you. Continuity without a gate just helps you ship the wrong thing faster. ## What ships in the zip - `SKILL.md` for agent harnesses that load skills as markdown - `sfl.py` - Python 3 stdlib helper: `init`, `promote`, `slice`, `render` - demo pack + example thin slice - install notes No cloud account. No proprietary runtime. Drop the skill in, point it at a project root, start saving for later. ## Get SFL Email unlocks the zip and the copyable skill text. The download gate is on this page. ## Install in thirty seconds 1. Unzip. 2. Copy the `sfl` folder into your agent skills directory. 3. In a project: `python3 path/to/sfl/sfl.py init my-campaign` 4. Promote as you lock decisions. Slice when you brief a worker. Full steps are in `INSTALL.md` inside the package. ## Why this is the product I got tired of re-teaching the same campaign every morning and watching sub-agents re-decide problems I had already closed. The fix is not a longer chat. The fix is a file that survives the chat, with two densities so humans and workers consume different projections of the same truth. Save the decision when you make it. Save the rejection when you earn it. Save the handoff when you leave. That is SFL. --- ## Touchmark: five characters that end session blur URL: https://aris-space.com/documents/workflows/touchmark Date: 2026-07-26 import { Code, Term, Glossary, Pullquote, SessionBlurBeat } from '@/components/blocks' import { S7Frame, S7Window } from '@/components/blocks/s7window' Last week I ran twelve AI sessions in parallel. Builds, audits, research legs, a render pipeline. All twelve produced files. All twelve transcripts look the same in hindsight: scrollback, tool calls, a wall of green checkmarks. Three days later I opened a handoff doc and could not answer the only question that mattered. Which session wrote this? The answer cost an hour of archaeology through git logs and file timestamps. That hour is the tax. It is not a tooling gap you notice once. It is a recurring leak in every parallel workflow, and it compounds with every session you add. ## 1. The blur problem Parallel sessions are anonymous by default. The harness gives each one an ID, but nothing surfaces it. Every terminal pane shows the same shape. Every artifact lands with no mark of origin. Anonymous sessions make anonymous artifacts. A spec, a render, a stamped commit: once it leaves the session, its provenance is gossip. You either remember which pane made it, or you dig. The fix is not a dashboard. It is a face. Give every session a mark that is cheap to compute, impossible to misread, and visible wherever the session touches the world. Then stamp that mark onto everything the session produces. That is what touchmark does. The rest of this post is the mechanism. ## 2. The face Every session already has an ID. A UUID, a slug, a key the harness assigned at boot. Touchmark takes that key, appends a salt, and runs it through SHA-256: ``` material = session_key + "\n" + "touchmark-v1" digest = SHA-256(material) ``` The digest is 256 bits. Useless to a human. So the code takes a Crockford base32 reading of it and keeps five characters. The alphabet is 32 symbols: digits 0 to 9, then most of the uppercase letters. Four letters are removed on purpose. **I** and **L** go because they misread as 1. **O** goes because it misreads as 0. **U** goes so a random code can never spell a word. What survives is an alphabet where every character is hard to confuse with any other, on any screen, in any font. Five characters at five bits each gives 25 bits. That is 33,554,432 possible codes. The right way to judge that number is not as a global namespace. It is as a local working set, and there the collision math is kind. By the birthday bound, the chance of two sessions sharing a code is roughly n squared over 2 to the 26. One hundred live sessions: about 0.015 percent. One thousand: about 1.5 percent. You feel collisions at scales no single operator reaches, and you never feel them in a working week. Why five and not four or eight. Four characters is 16 bits: a collision inside a busy month. Eight characters is 40 bits: overkill, and now the code no longer fits in glance memory. Five characters is the largest code a person holds without effort. You can say it over a call. You can spot it in a screenshot. You can type it without checking. The code is deterministic. Same session key, same five characters, on any machine, in any language. The JavaScript port on the download page is pinned bit-identical to the Python CLI by a golden-vector fixture, so the face a browser shows you is the face the CLI stamps. ## 3. The grid The code is for reading. The grid is for seeing. The same digest drives a second rendering: an 8 by 8 grid of cells, where the hash places between 12 and 18 dots. Different session, different constellation. Same session, identical constellation, every time. Why a grid at all, when the code already identifies the session. Because text costs attention and pattern costs almost none. Reading a code is foveal work: you stop, you fixate, you parse. Recognising a dot pattern is peripheral work. Your visual system flags same or different before you have decided to look. Twelve panes on a screen and your eye catches the odd grid out without a single act of reading. The sparsity is tuned. With 64 cells, the dot count k is drawn from the range 12 to 18. Below 12 the faces converge: too few dots, and unrelated sessions start to look alike. Above 18 the grid turns to static: too many dots, and every face reads as the same noise. Inside the band, at k equals 15, the number of distinct grids is the binomial coefficient 64 choose 15, about 1.6 times 10 to the 14. The alphabet of faces is effectively inexhaustible next to any session set. The grid and the code come from the same digest, so they never disagree. The code is what you type into a search box. The grid is what your eye catches first. ## 4. The stamp A face nobody wears is decoration. The point of the mark is that it travels onto the work. `touchmark stamp ` writes a frontmatter block into a markdown artifact. A real specimen, minted from the session key `touchmark-sample`: ```yaml --- touchmark: schema_version: 1 code: "31T2J" session_key: "touchmark-sample" harness: claude minted_at: "2026-07-25T14:07:24Z" --- ``` `touchmark verify ` recomputes the code from the stamped session key and compares. Exit 0 when the mark matches. Exit 1 when it does not, or when the file carries no readable mark at all. That exit code is the whole API surface for automation: a gate in a pipeline is one line, and a forged or stale stamp fails closed. `touchmark scrub-check ` runs the other direction. Exit 0 is clean. Exit 1 means the file carries touchmark patterns that should not leave the building: session keys, stamped marks, stray sigils in prose. This is the check that runs before anything publishes. Now the artifact carries its own provenance. The question from the opening, which session wrote this, stops being archaeology. It is a read of five characters in the file's own header, verifiable by anyone with the same one-file tool. ## 5. The contract Notice what the software does not do. It does not watch your sessions. It does not intercept your saves. It mints, stamps, verifies, and scrubs when asked. The sigil works because of a behavioral contract, not because of enforcement. Three rules: 1. **Mint on start.** Every session gets its face at boot, before the first artifact exists. A session that mints late has already shipped anonymous work. 2. **Stamp artifacts.** Anything meant to outlive the session carries the mark. Specs, handoffs, plans, publishable drafts. Ephemeral scrollback can stay anonymous; deliverables cannot. 3. **Scrub before publish.** Public output gets checked. The mark is for your trail, not for leaking your session graph to strangers. This is why the tool ships as a skill file and a single script rather than a daemon. The protocol is the product. The script just makes the protocol cheap to keep: one command per rule, each one fast enough that keeping the contract costs less than breaking it. A protocol you keep beats a feature you configure. ## 6. The packaging The distribution is a zip with an `install.sh` inside. Not pip, not a package registry, not a versioned dependency. The reason is what the artifact actually is. pip installs code into an environment, and touchmark is not code you import. It is a convention wired into a harness: a skill the model reads, a statusline field, a stamp command in reach. `install.sh` places those wires where the harness expects them and proves the wiring with a self-test. A registry entry cannot do that, so the registry would be ceremony. The reason for the adversarial scrub is what a grep cannot see. A token scan catches strings: paths, names, key patterns. It cannot catch a semantic fingerprint, text that names no secret yet describes something identifiable to anyone who knows the private context. The public build of this tool was reviewed with adversarial passes seeded with that context, and those passes caught lineage vocabulary that every regex called clean. Both layers ship in the box. Only one of them would have been enough. The stance on the gift is stated plainly: **as-is gift, no support, no roadmap.** The declared envelope is macOS and Linux, Python 3.9 or later, Claude Code. Inside that envelope it is dogfooded daily and pinned by a parity gate. Outside it, you are on your own and the price reflects that. The tool is free. The deep dive you just read is the whole pitch. If the blur problem is yours, the download is one email gate away: **[Get touchmark](/touchmark)** Mark the session. Stamp the artifact. Trust the trail. --- ## The desk is open URL: https://aris-space.com/documents/announcements/aris-space-v2-is-live Date: 2026-08-01 # The desk is open **Ari's Space V2 is live.** This note is the short door. The long story is the making-of. --- ## Read this first if you want the process **[Ari's Space, Rebuilt With Kimi](/documents/announcements/rebuilt-with-kimi)** - swarm night, Kimi groundwork, Grok art-direct, waves W0 through the OS desk. Behind the scenes, not a brochure. The older V1 speedrun still sits in the library: [*Building Aris Space: 8 Hours...*](/documents/discipline-and-process/building-aris-space). --- ## Quick map | Go | What | |----|------| | [`/documents`](/documents) | Library graph (free deep dives stay free) | | [`/courses`](/courses) | Multi-page courses | | [`/pricing`](/pricing) | Orbits = extra access + tools, not a swap for free teaching | | [`/privacy`](/privacy) | What loads (no analytics SDK today) | | [`/community`](/community) | Member community | Guest desk first. Sign in for the working machine under `/app`. **Skool stays.** Clief Notes cadence is not replaced by this desk. Membership is an extra layer: machines and new tools to try, on top of free essays and the posts you already get. --- // Walk the library. Then read the making-of. --- ## Ari's Space, Rebuilt With Kimi URL: https://aris-space.com/documents/announcements/rebuilt-with-kimi Date: 2026-08-01 {/* Model name: public copy uses "Kimi" only (no vendor SKU claim). Ari approved publish 2026-08-01. */} import { Diagram, Pullquote } from '@/components/blocks' # Ari's Space, Rebuilt With Kimi I tore this site down to the studs. Not a reskin. A rebuild. New design system, new architecture, new money path, new content machine, then an OS skin you can walk into. The crew was not a crew. **Kimi** carried the groundwork: swarm night, architecture kill, wave plans, money, gen, migration. **Grok** took the baton for art-direct: live render, one note per round, rapid iteration on the desk face. Same doctrine. Different job for the seat. This is the **making-of**. How V2 got decided, how it got built in waves, how the look got directed, what broke, what we refused to ship soft. If you want the older speedrun (V1, eight hours, five sessions), that still lives here: [*Building Aris Space: 8 Hours, 5 Sessions, One Site*](/documents/discipline-and-process/building-aris-space). Different era. Same instinct: protocol over heroics. Stop prompting. Start defining outcomes. This is what that looks like when you point it at your own website. --- ## Night zero: the swarm that argued first I dumped a mess into one session. Membership tiers. An image tool. A forum. A design language built around a pixel rocket shaped like the letter A. Chaos. The session did not start writing code. It started by arguing with itself. **Five discovery agents** went out in parallel: 1. Map what already existed 2. Stress-test the stack 3. Hunt every way the plan could fail 4. Walk the site as a visitor 5. Sequence the work They came back with digests, not noise. I made a short stack of hard decisions in about ten minutes. Then **three architecture drafts** went head to head. **Three adversarial judges** tried to kill them. Two drafts died. The survivor is the skeleton of what you are looking at now. The public name of the model lane that carried that night and the wave groundwork is **Kimi**. The method is load-bearing either way: swarm discovery, kill weak architecture, lock a written plan, then build in waves. --- ## What the night locked (before a single product page) ### Three surfaces, one domain Not three marketing sections. Three machines that share a domain: | Surface | Job | |---------|-----| | **Reading machine** | Essays, courses, pricing, public pages. Server-rendered. Fast. Crawlable. | | **LLM machine** | Context packs, `llms.txt`, agent-readable needles. Same truth as the human notebook, different reader. | | **Working machine** | Signed-in product under `/app/*`: auth, billing, studio, gen, writes. | One domain so cookies stay first-party. Public content deploys when content changes. Product deploys when product changes. That split is why a content ship does not have to rattle the ledger. ### Design system before product Cream paper. Purple rocket. Type that looks like it escaped a terminal. **Whimsy is the wrapper, never the content.** If body copy is hard to read because we got cute with a pixel font, that is a bug. The design package shipped as the first real artifact of the rebuild. Showcase route. Tokens. Window chrome. Lint that keeps decorative noise out of the MDX body. ### Rules that outlived the night - **Outcome over path.** Public copy never needs private harness names. - **Paid value close to login.** No maze. - **Rocket intro once**, skippable, reduced motion honored. - **Ledger is law** for credits: integer pence, atomic debit, idempotent webhooks, reconcile when reality drifts. - **GEO is not an afterthought.** Agents are a first-class reader of the site. Those lines went into a written design. Everything after was execution against that contract. --- ## Seats: Kimi groundwork, Grok art-direct I do not treat models as interchangeable wallpaper. **Kimi** held the long groundwork seat: discovery swarm, design lock, identity, money path, gen surface, content migration. High structure. High proof. Written plans and definitions of done. **Grok** took the art-direct seat when the machines already worked and the face needed to move fast: live page open, one note per round, cream field and window chrome, library graph, loginwindow, guest desktop. Rapid iteration against pixels, not another architecture debate. That split matches how I direct film: some days you need a planning room. Some days you need a monitor and a call sheet of tiny moves. See [*I directed a website live...*](/documents/workflows/direct-the-screen). --- ## How we actually built it: waves, not one heroic session V1 taught me the session cap. V2 taught me the **wave** cap. Each wave had a definition of done. Merge-request only on main. Preview, then promote. Written handoff into the next wave so a cold session could not invent a new plan. ### W0 - Foundations Monorepo. Design package. Context-pack validator ported, not rewritten. This announcement drafted as the first page of V2. A real content-scale spike so we knew whether the essay corpus would blow the worker before we promised the world a migration. ### W1 - Identity Auth on the working machine. Users mirrored into the data plane. Public header that knows if you are signed in without gating the library. A hard spike: **one domain, two workers**, route dispatch for `/app/*`, one cookie. Sign-in had to work for real before money touched anything. ### W2 - Money Orbits on a real checkout path. Founding prices shown next to standard from day one so the jump is never a surprise. Ultra scarce by design. Credits as a ledger, not a vibe number in a row. The craft here is boring on purpose: idempotent webhook handling, atomic debit so two gens cannot spend the same pence twice, a portal for cancel, ops paths to inspect and replay when the edge of the internet lies to you. I ran a full £0 loop in the browser before anything live charged a card. Sign up, pick a tier, coupon, grant lands, cancel cleans the tier. That kind of proof is the opposite of a launch tweet. ### W3 - Product surface Image gen behind login. Prompt enhance on the server. Cap enforcement on the ledger. Community read on the public worker, write on the app worker. AutoMod posture: hide above threshold, review queue, not theater. The model slot on the gen path changed when the first planned backend refused credentials on this account. We probed live, picked a quality peer that actually answered, left a one-var upgrade path if the gate ever clears. That is the method: **probe, record, ship what works**, do not romanticise the brief when the wire says no. ### W4 - Content machine This was the heavy lift. The old corpus was not "a folder of markdown." It was hundreds of kilobytes of essays welded to a component library, fidget blocks, glossary runtime, and a few whimsy-in-content habits the new lint had to kill. We staged migration. Ported or shimmed the load-bearing blocks. Kept **URL shape 1:1** so the library did not become a redirect storm. Courses as multi-page paths. Privacy that matches what the site actually loads. Context packs and `llms-full` as **build-time static assets**, because the worker has **no disk** at runtime. That last line burned once for real. Green tests on a machine with a filesystem do not prove production. If a route handler tries to read content from disk on the worker, it fails closed in prod while your laptop smiles. Fix: generate the payloads at build, ship them as assets, probe a route that only exists in the new version after deploy. ### W5 - OS skin and the desk you walk into After the machines worked, we art-directed the face. This is where the **Grok** seat earned its keep. Login window. Guest desktop. Menu bar. Constellation of windows. Library as a **graph** of topic clusters with ASCII icons, not a flat blog index. Deep dives in paper clearings inside the field. Motion law: whole-pixel steps so text stays sharp. No greens. Cream and purple and brown. Live render open. One note per round. Call the next change when the frame settles. Agents held the hands. Taste stayed human. Then the apex cutover: the preview host stopped being the main door. The desk is the public site. --- ## Hard lessons (the ones that should transfer) ### Write the handoff A session that ends in chat lore is a session that steals from the next one. Done means a document: what shipped, what is open, what must not be re-litigated. ### Small sessions, then waves Context windows rot. Waves keep the plan honest. Definitions of done keep vanity work out of main. ### Swap the seat when the job changes Groundwork and art-direct are different sports. Route the model (and the human mode) to the job. Do not force a planning seat to paint, or a paint seat to re-litigate the ledger. ### Pathspec commits, staged deploys Stage only what you meant. Deploy web when content or chrome moved. Deploy app when money, auth, or gen moved. Do not "just ship everything" because the terminal is warm. ### Dual readers Humans get the notebook. Agents get the pack. Needles stay verbatim. See [*Context pack dispatch*](/documents/dispatch/context-pack-dispatch). ### Fail closed on gen that looks fake On the product path and on my own desk craft: - Two independent looks before anything is finished - If it looks obviously AI, it fails - Staging before promote - Still before motion when video is in play - Log recipes so a morning pass can see what is red Studio is where members run gen. Essays are where the floor gets taught. The private sharpen work on my machine stays private; the **discipline** is public. ### Probe production truths Workers have no disk. Webhooks hit real WAF rules. Auth widgets behave differently on test keys. £0 loops beat confidence. Replay paths exist for when the world is wrong and your ledger must still be right. --- ## What the experience of building this way felt like I did not "prompt a website into existence." I sat in the conductor seat. Discovery argued. Architecture died in public (inside the swarm). Waves merged under tests. Art direction happened against a live page. Money was proven on a zero charge. Content migration was measured before it was promised. The intelligence is not any single model. It is the **system around them**: who goes first, who gets to kill a draft, when to swap the baton from groundwork to paint, what done means, what ships only after eyes are on it. That is the same doctrine as the rest of this library. V2 is just the week I pointed it at the house itself. --- ## Where the desk is now You can walk the guest desktop. Open the library graph. Take a course. Sign in for the working machine. Read privacy that matches the loaders. Agents can fetch packs instead of scraping pretty HTML. I am not going to re-sell you the orbit table here. That is a different page, and it should stay a different page. This essay's job is narrower: **show the rebuild**. --- ## What does not change V2 is **not** a paywall on the teaching. - **Free deep dives stay free.** The library essays keep shipping for anyone who can open a browser. Membership is not a replacement for that corpus. - **Skool cadence stays.** I still post in Clief Notes the way I already do. The desk does not eat that habit or turn the community into a paid-only drip. - **Membership is an extra layer of access.** Studio, gen, member machines, tighter seats when you want hands on the tools. New tools to try. Not a swap for the public work. If you only ever read free and hang on Skool, you are still in the room. The orbits buy machines, not permission to learn the basics. --- // The rocket launches once. Then it's all content. --- ## Agentic Progressive Improvement: snags as nested units URL: https://aris-space.com/documents/workflows/agentic-progressive-improvement Date: 2026-08-02 # Agentic Progressive Improvement: snags as nested units Keep the main seat on the real task. Snags become **internal improve units** with risk tiers and a skim line, not a second design chat with you. This is a portable mid-session protocol. When a tool path breaks, a method gap appears, or the same friction shows up again, the orchestration seat spawns a nested improve unit instead of flooding the only context window or debating a low-risk fix with the human. Version pin on this page and the member kit: **`0.1.0-rc.1`**. The method is open (MIT on GitLab). Community members get a convenience kit: first-run pack, seat snippets, examples, scrubbed skill copy. The kit is polish, not exclusive IP. ## What it does You are mid-task. Something snags: a broken import, a wrong default path, a flake that will eat the next hour if you fix it inline. You have two bad habits available: 1. Stay in the main chat and thrash the fix until the real task is gone. 2. Start a second long design conversation with the human about a T0 or T1 change. **Agentic Progressive Improvement** picks a third move. The orchestration seat classifies a **risk tier**, appends a **local ledger** entry, and spawns an **improve agent** (nested brainstorm, not operator-facing for T0 to T2). That agent dispatches **builders** under a denylist. You keep the real conversation. Re-entry is a single skim line when the tier requires visibility, or silence when green hygiene already has a ledger and an undo story. ```text Operator <-> Orchestration seat (real task) | | spawn improve unit v Improve agent (nested brainstorm) | | builders (+ optional auditor) v Local trail + digest | v skim line if tier needs it silent OK for green T0 (ledger + undo) ``` ![Role graph doodle: orchestration seat, nested improve agent, and builders](/images/deep-dives/agentic-progressive-improvement/g1-role-graph.jpg) *Role graph (illustration). Labels live in the table below.* ### Roles | Role | Job | | --- | --- | | Orchestration seat | Real task; may spawn improve units; holds skim only | | Improve agent | Internal brainstorm; not operator-facing for T0 to T2 | | Builders | Mechanical changes under denylist + tier | | Optional auditor | Check risk / scrub when tier warrants | ### Caps ```text CAPS (hard) -------------------------------- <=3 concurrent improve units / session <=2 retries on the same error class then escalate: needs-operator same model as the orchestration seat (mechanical builders may use local only with headroom) ``` ![Session caps card: at most three concurrent units, two same-error retries, then needs-operator](/images/deep-dives/agentic-progressive-improvement/g5-caps-chip.svg) ### Public skim form ```text ↑ improve: · T# · · undo: ``` Teach surfaces use **`↑ improve:`**. Silent is fine for green T0 (and many T1s) when a ledger exists. Unsure about risk? Bump the tier. Do not downrank when uncertain. ![Public skim re-entry card showing the improve skim line pattern](/images/deep-dives/agentic-progressive-improvement/g3-skim-card.svg) **One safety sentence (memorize it):** > Silent green T0 is for hygiene with a ledger and undo, not for method, remotes, or secrets. Unsure → bump tier. T3 ask. T4 prepare only. ## Thought process ### Pain Mid-session friction is cheap to notice and expensive to host in the only window you have. Operators either flood that window fixing the snag, or they recruit the human into a design chat about a tiny change. Both steal the real task. Low-risk hygiene should not become a committee. ### Insight **Context is scarce.** Tokens spent on tool streams and bulk reads do not return as clarity. The orchestration seat should stay on the work that matters. Improve work can run as a **nested unit**: risk tier, local trail, skim re-entry only when the tier requires it. ### Method birth The portable product is the same doctrine in public language: spawn an improve unit (nested brainstorm → builders), classify T0 to T4, hard denylist, caps, same-seat model for the improve agent, local trail by default. Open MIT so any host that can load a skill and (ideally) spawn seats can run it. Serial single-seat fallback stays honest when multi-seat is impossible. ## How we built it Two layers, deliberately thin: 1. **Skill:** markdown protocol you drop into a seat skills directory: when to spawn, role graph, tier table, denylist categories, skim form, host honesty (`dispatch` / `serial_fallback` / `partial`). 2. **Optional local ledger CLI:** `api-improve` for classify, append, brief, skim, tail, trail. Ledger defaults to a local state path (override with env). Trail backend is local or none. No forge credentials required for the RC. ```text SKILL-ONLY (floor) SKILL + CLI (optional clock) ------------------ ---------------------------- drop skill into seat pip install -e ".[dev]" from clone invoke on snag api-improve classify|append|... obey tiers / caps / denylist ledger + trail on disk host must spawn or serial-fake same doctrine, better audit surface ``` Everything is protocol-shaped, not product-shaped. You bring the multi-agent host. This pack is not a full nested-dispatch runtime, not a memory-codify replacement, and not an AFK self-improve loop. SSOT for method and code lives on public GitLab under `agentic-progressive-improvement`. The site vends a versioned member zip as a convenience build. History and tags live on the open repo. ## How to use it ### 1. Get the method - **Free learn:** this Deep Dive + the public GitLab tree (skill, SPEC, tests, scrub gate). - **Member convenience kit:** zip via the CTA at the bottom (login required). First-run pack, seat-rule snippet, examples, scrubbed skill/prompts, tier cheat-card. Same version: **`0.1.0-rc.1`**. ### 2. Skill-only install Copy or symlink the skill folder into the directory your agent loads skills from. Invoke when a snag appears: ```text Run Agentic Progressive Improvement on this snag: . Classify T0-T4. Prefer dispatch when multi-seat exists. Use serial_fallback only if spawn is impossible. Obey denylist. Re-enter with ↑ improve: when the tier requires it. ``` ### 3. Skill + CLI (optional) From a clone of the public repo: ```text pip install -e ".[dev]" api-improve classify --snag "..." --path api-improve append --tier T1 --kind unblock --seat --status building --snag "..." api-improve skim --what "..." --tier T1 --ref --undo "git revert HEAD" api-improve tail -n 5 api-improve trail --backend local ``` Ledger default: XDG state path under `api-improve`, or `API_IMPROVE_LEDGER` override. Trail: `local` or `none`. ### 4. Run one unit 1. **Classify** T0 to T4. Unsure → bump one tier. 2. **Ledger** append `building` (local by default). 3. **Spawn** the improve agent with tier, snag frame, paths, denylist, model = inherit from the orchestration seat. 4. **Continue** the real task. Do not wait inside a flood loop. 5. **On digest:** verify claims on disk when ship matters; update ledger; emit one skim line if state change needs visibility. 6. **T3 / T4:** surface `needs-operator` with paths. Never silent promote. T4 prepares only; no auto-mutate. ### Host honesty | Mode | When | Claim | | --- | --- | --- | | `dispatch` | multi-seat spawn works | peer improve unit | | `serial_fallback` | one seat / no spawn | same stages + digests; not peer quality | | `partial` | mix | name which legs | Serial is the **portable floor**, not the preferred doctrine. Prefer dispatch when multi-seat exists. Never claim peer critique when one seat performed every role. ### When not to use it - Taste decisions the operator must own. - T4 red-zone mutation (prepare and ask only). - Replacing principle-capture or memory-codify tools. - Replacing a full design swarm or a locked build fan-out (pick the sibling below). ## Safety ### Risk tiers | Tier | Name | Operator | Ship posture | | --- | --- | --- | --- | | T0 | Session hygiene | Silent when green | Local only; ledger + undo story | | T1 | Task-unblock | Optional skim | Branch; auto-merge only under strict explicit caps | | T2 | Tool inherit | Batch at pause | Human merge | | T3 | Method / rules | **Ask** before promote | Draft until approved | | T4 | Red zone | **Ask** | **Prepare only** · no auto-mutate | ![Risk tier ladder from T0 session hygiene to T4 prepare only](/images/deep-dives/agentic-progressive-improvement/g2-tier-ladder.svg) **Silent green T0 is for hygiene with a ledger and undo, not for method, remotes, or secrets. Unsure → bump tier. T3 ask. T4 prepare only.** ### Classification floors - Unsure → bump one tier (never downrank when uncertain). - Touches seat rules, methodology, or durable process → min T3. - Touches secrets, remotes, disk cleanup, sudo, public publish → T4. - Second occurrence of the same pain class may promote T1 → T2 (inherit). - First occurrence, one-off → prefer T1 unblock, not a permanent new tool. ### Denylist (categories) Mass disk wipe · protected remotes · secret dumps · sudo without approval · public publish without scrub · push main · AFK irreversible. Full text lives in the kit and the public SPEC. Categories stay free to learn here. ### Model policy The improve agent uses the **same model as the orchestration seat**. Mechanical builders may use local models only when headroom exists. Never hop cloud vendors only to save cost. ## Sibling triangle Pick by job, not by habit. ```text +---------------------------+ | brainstorming swarm | | many seats on DESIGN | | stop at written spec | +------------+--------------+ | +------------------+------------------+ | | v v +------------------+ +------------------+ | solo brainstorm | | build swarm | | one seat, design | | many seats on | | until approval | | IMPLEMENTATION | +------------------+ +------------------+ orthogonal (this pack): +----------------------------------------------+ | Agentic Progressive Improvement | | mid-session SNAG → nested improve unit | | desk/repo better · operator stays in chat | +----------------------------------------------+ ``` ![Sibling pack icons: solo lamp, design swarm field, progressive improve wrench](/images/deep-dives/agentic-progressive-improvement/g4-triangle.jpg) *Sibling icons (illustration). Job names live in the table below.* | Method | Job | Stops at | | --- | --- | --- | | Solo brainstorm | One seat on design | Spec | | Brainstorming swarm | Multi-lens design under parallel pressure | Spec · no build | | Build swarm | Implementation fan-out | Shipped units | | **This** | Mid-session snag → nested improve by risk tier | Desk/repo better · real chat continues | If the design is not locked, do not use this pack as a fake design swarm. If you only need one seat and one pass on a small design, use solo brainstorm. If you need many seats on the design itself, use brainstorming swarm. If design is locked and you need hands on code, use a build swarm. Use **Agentic Progressive Improvement** when the real task is already running and a snag should not steal the window. ## Get the convenience kit Open method free on this page and on GitLab. The member zip is one-click install polish: first-run path, seat snippets, examples, scrubbed skill copy, tier cheat-card. Version **`0.1.0-rc.1`**. ![Blank sticky note doodle with a quiet stick figure for the membership note](/images/deep-dives/agentic-progressive-improvement/g6-sticky.jpg) If you enjoyed this: community members can download the **convenience kit** (first-run pack + seat snippets). The method stays free to learn on this page and on GitLab. --- ## Brainstorming swarm: design under parallel pressure URL: https://aris-space.com/documents/workflows/brainstorming-swarm Date: 2026-08-02 # Brainstorming swarm: design under parallel pressure Solo brainstorm works when one seat and one human can hold the problem. Build swarm works when the design is already locked and you need hands on the code. This pack sits in the middle: **many seats on the design itself**, then a hard stop before anyone builds. It is a skill you load into an agent workspace. Markdown, schemas, role cards. No vendor runtime. No cloud dispatch product. Any capable seat that can follow files can run a role. ## What it does You point the skill at a hard design problem. The conductor frames the goal and hard locks. Discovery lenses fan out (failure, stakeholder, constraint, temporal, experiential by default). You hold **Gate A**. Competing approaches fan under different axioms. Critique kills, keeps, or salvages. You hold **Gate B**. The swarm presents a design, writes the approved version, and **halts**. That last word matters. This skill does not build. Terminal outcome is a written design you can defend. Implementation is a different job, a different session, and usually a different pack. ```text +--------+ +-----------+ +--------+ +------------+ | S0 | --> | S1 | --> | Gate A | --> | S2 | | Frame | | Discovery | | human | | Approaches | +--------+ +-----------+ +--------+ +------------+ | v +--------+ +-----------+ +--------+ +------------+ | S5 | <-- | S4 | <-- | Gate B | <-- | S3 | | Spec | | Present | | human | | Critique | | HALT | +-----------+ +--------+ +------------+ +--------+ ``` **Brief in, digest out.** Each parallel leg gets a scoped brief: goal, locks, schema, word caps. The conductor gets named fields back, not a raw tool stream. Invalid or dump-shaped returns get rejected once, then escalated to you. ```text DUMP (rejected) DIGEST (accepted) ---------------- ----------------- full tool logs named fields only recursive tree paste hard word caps "here's everything I saw" one retry on bad shape floods the window protects the window ``` **Mode honesty.** Label the run for what actually happened: | Mode | Meaning | | --- | --- | | `dispatch` | Independent seats ran the legs | | `serial_fallback` | One seat played roles in sequence; schemas still hold | | `partial` | Some parallel, some serial; name which | Never claim peer critique when one seat performed every role. Floor success without multi-seat is required. Floor is not the default. ## Thought process Three load-bearing ideas shaped the pack. None of them are product marketing. They are scars from long sessions that drowned. ### Context is scarce Tokens spent on logs, bulk reads, and tool streams do not come back as clarity. The main chat is a scarce surface. If every leg dumps its research into that surface, the conductor stops thinking and starts scavenging. So the unit of exchange is the digest. Schema-capped. Field-named. Rejectable. The swarm can be loud at the edges and quiet in the middle. ### Orchestrator is not the doer The main seat advises, routes, synthesizes, and holds gates. Heavy work leaves the seat. Workers execute. They do not advise you, rewrite process, or own taste and route choices. That split is the same idea as renting a conductor and swapping the orchestra: expensive judgment stays central; parallel labour fans out. Here the labour is design pressure, not implementation. ### Aggressive dispatch Default to fan-out when multi-seat exists. Keep work inline only when it is small and local. Ask: will this flood my window? Flood triggers include large output, large read sets, long focused execution, isolation needs (parallel design legs that must not share mid-work state), and capability mismatch. When in doubt and multi-seat is available, fan out. ```text DISPATCH-FIRST (default) SERIAL FALLBACK (floor) ------------------------ ----------------------- multi-seat / multi-tab one seat, stages in order same-turn spawn when ready same digests, same gates true peer critique possible mode: serial_fallback mode: dispatch never fake peer quality ``` Serial success is required for LLM-agnostic honesty. Serial-as-default doctrine is rejected. Dispatch-first is the practice whenever parallel capacity exists. ### Sibling triangle Three related skills. Pick by job, not by habit. ```text +----------------------+ | brainstorming swarm | | many seats on DESIGN| | stop at written spec| +----------+-----------+ | +----------------+----------------+ | | v v +------------------+ +------------------+ | solo brainstorm | | build swarm | | one seat, design | | many seats on | | until approval | | IMPLEMENTATION | +------------------+ +------------------+ ``` If one seat and one pass is enough, use solo brainstorm. If design is already locked and you need implementation fan-out, use build swarm. This pack is the middle of that triangle: parallel pressure on the design itself. ## How I made it I already had a solo brainstorm discipline: one question at a time, a hard gate before code, a written design as the terminal state. That skill stops the agent from building the wrong thing with confidence. It does not give you competing frames under time pressure. What I needed next was the design equivalent of a build fan-out. Multiple lenses on the same goal. Competing approaches that do not leak into each other mid-flight. Critique that can kill a frame without killing the whole chat. Digests that keep the conductor window readable. So the pack is protocol-shaped, not product-shaped: - **Stages and hard gates** so the run has a spine and humans stay in the loop at Gate A and Gate B - **Roles** (conduct, gather, draft, judge, synth) so cards are portable across harnesses - **Lenses and axioms** as replaceable cards, not hard-coded opinions about your domain - **Digest schemas** with word caps so workers cannot flood the seat - **Fan-out doctrine** with an honest serial fallback so the method still works on a single tab Everything is plain markdown. Drop the tree into a skills directory. Invoke it. No package manager. No telemetry. No vendor lock as the spine. Member distribution is deliberate: community members on aris.space get the versioned zip. You load it, run it, and keep the design artefact in your repo. The site is the front door. The skill is the method. ## How to use it ### 1. Get the pack Members download the zip from the CTA at the bottom of this page (or from the community skill surface once your seat is live). Unzip and place the `brainstorming-swarm` folder where your agent loads skills. ### 2. Invoke Point a capable seat at the skill and the problem: ```text Read SKILL.md and run brainstorming-swarm on: . Prefer dispatch-first. Use serial fallback only if multi-seat is impossible. Stop at a written design. Do not build. ``` ### 3. Run the stages 1. **S0** Frame the goal and hard locks. Bound the context. Digests only if the read set is large. 2. **S1** Fan discovery lenses. Collect digests. Compress a short summary for yourself. 3. **Gate A** Redirect or approve before approaches start. Do not skip this. 4. **S2** Fan competing approaches under different axioms (defaults: mvp-first, risk-first, portability-first). 5. **S3** Critique. Kill, keep, or salvage per approach. 6. **Gate B** Pick a winner or hybrid. That choice is yours. 7. **S4** Present the design for approval. 8. **S5** Write the approved design. **Halt.** Do not start implementation from this skill. ### 4. Hand off The written design is the contract for whatever comes next. A build session, a build swarm, or a quiet week of solo coding. Continuity tools (for example Save For Later) can hold decisions and rejections around that design. They do not replace the gate. ### When not to use it - One seat, one pass, small problem: solo brainstorm is enough. - Design already locked: go straight to build work or a build swarm. - You want the agent to start coding "while we think": stop. That is the bug this family of skills exists to prevent. ## Get the skill pack --- ## ODVM: query your footage without re-seeing it URL: https://aris-space.com/documents/tools-and-plugins/odvm-video-memory Date: 2026-08-03 import { DensitySliderFidget, QueryPlaygroundFidget } from '@/components/blocks' ## Narration Every clip walks the same four stages. Sample picks the moments worth looking at. Observe looks at them once and writes sidecars. Index turns sidecars into search. Query answers in time spans without ever re-running vision. ## Search what was said, lose what was shown Every clip on my drives used to be searchable by exactly one thing: its filename. The transcript pipelines fixed half of that. They index speech, so anything somebody said out loud became findable. But the moments I actually go hunting for are the ones nobody narrated. The take where the red jacket walks left. The quiet screen moment in the middle of a stream. The beat the chat scrolled past. None of those survive a transcript, because nobody said them out loud. The fix is not a better transcript. It is a second memory, built from the pictures, that sits next to the first one. ## Narration The same clip, indexed two ways. The transcript row only lights up where someone talks. The video memory row lights up where something happens, spoken or not. You want both rows. This isn't magic, and it isn't cloud. Everything runs on my own hardware, the footage never leaves the disk it lives on, and the first release candidate proves plumbing before it promises understanding. ## Sample the moments, not the frames The naive move is to caption every frame. At twenty-four frames a second that is a pile of redundant work describing a static shot hundreds of times. ODVM samples instead. Scene cuts anchor the timeline. A motion signal densifies coverage where something actually moves. A floor guarantees even a locked-off static shot gets looked at occasionally. A five-second clip might earn a handful of keyframes; a busy minute earns more. ## Narration Keyframe density follows activity. Cuts always land a keyframe. Motion pulls neighbours in. Static stretches coast on the floor. The budget goes where the information is. ## Observe once, then never again Here is the whole trick: the vision model runs exactly once per clip. Observe takes the sampled keyframes and asks a local vision model what is happening in each. The answers land in versioned sidecar files next to the project, keyed by which model wrote them. Swap the model later and the old observations stay put; the new ones version alongside. Audio is first-class on the same pass. A local speech model writes utterances with start and end times, fused onto the same timeline as the visual observations. Not bolted on later: fused by time from the start. ## The index is the memory Sidecars are durable but slow to search. Index reads them once and builds the fast layer: SQLite full-text search over every observation and utterance, plus embeddings for the queries that phrase things differently than the captions did. Delete the index and re-run `odvm index`: it rebuilds from sidecars alone. The sidecars are the truth. The index is a cache you can always regenerate. ## Narration Observations and utterances live as plain sidecar files. Index reads them into SQLite: full-text search for the literal queries, embeddings for the fuzzy ones. Lose the index, rebuild it, lose nothing. ## Query without re-seeing Query never touches the vision model. It searches the index and returns ranked time spans: this clip, from here to here, because these observations matched. That is the property the whole design bends towards. Asking "when does the handheld walk-and-talk start" costs a database lookup, not a GPU minute. An agent with a token budget asks `odvm pack` for a sized context bundle and gets text chunks with times, ready to cite. ## Narration The query path has no vision model in it. Ranked spans come back from the index alone. That is what makes the hundredth query as cheap as the first. The model is replaceable. The memory you build is the asset. ## The release candidate ODVM v0.1.0-rc1 is a real CLI, not a demo. Four commands carry a clip from file to answer: ```bash odvm sample --project myproject --asset clip.mp4 --job edit_shoot odvm observe --project myproject odvm index --project myproject odvm query --project myproject "the red jacket walks left" ``` Two job profiles ship in the box. `edit_shoot` weights visual rank for takes and plates. `stream_personal` weights transcript for long recordings, while still indexing the silent beats a transcript-only tool would drop. One schema, one pipeline; the profile only moves the defaults. A gold harness ships too, so quality is a number you can check instead of a vibe you trust. Change a prompt pack or a rank weight, re-run the gold queries, read the recall. The download is gated to ARCHITECT members while it is a candidate. Break it, and tell me where it broke: that is what a release candidate is for. ## What I would steal from this Even if you never install ODVM, the shape transfers. Pick the moments instead of the frames. Run the expensive model once and keep its answers in files you own. Treat the index as a cache, never the truth. Make the hundredth query as cheap as the first. If the memory angle lands, the sibling post is [A second brain for taste, not for notes](/documents/tools-and-plugins/lens): same discipline, pointed at style instead of footage. Local first. Query without re-seeing. The discipline beats the tool. --- ## Generative Memories: killed ideas that keep teaching URL: https://aris-space.com/documents/memory/generative-memories Date: 2026-08-04 import { Pullquote, GenerativeMemoriesPipeline, CounterfactualMemoryCard, FourGatesCaught, } from '@/components/blocks' # Generative Memories: killed ideas that keep teaching The count from my own bench on the day this shipped: three full designs for one system, all three killed by my own AI judge panel. Unanimous verdicts. That should have been the end of it. It became the most useful thing I built this month. I call them **Generative Memories**. On a schedule, no human in the loop, the system takes one killed approach from a past brainstorm, expands the old sketch into a mini-spec, builds it as a throwaway ghost, and distils what the build taught into my knowledge system. Tagged, always, as counterfactual. This build never shipped. The build is the instrument. The memory is the product. Without the build, the memory is hallucination wearing a dead idea's name. Without a typed distil schema, the build is noise. Both ends of that sentence are load-bearing. --- ## The goal, before the mechanism The goal is not "more memory." The goal is progressive creative force. Verbatim, the brief that locked the design: > Essentially the goal of this is to make something where we're progressively thinking creatively and taking creative approaches to solving problems. Every brainstorm I run kills two ideas for every one that ships. The winner is usually the safe pick. The kills are where the creativity was hiding. If those kills only live as discarded prose in a digest, the knowledge system never gets the experience of the road not taken. Future brainstorms only recall what won. That is how a system gets more efficient and less creative at the same time. Generative Memories reverse that asymmetry. The safe pick still ships. The kill still dies as product. The kill's *build experience* survives as a marked memory. Next time a related problem lands, recall can surface not only what worked, but what building the discarded path would have taught. --- ## Methodology: swarm, kill, salvage, hybrid, gate This system was designed by the same discipline it feeds. Six discovery legs mapped the real landscape. Three draft approaches proposed shapes. Three judge legs attacked those shapes. **All three approaches were killed with salvage.** The shipped design is the hybrid the judges left standing: - **Spine** from the risk-first draft: provenance proof before any timer, executor probe before any real ghost, one end-to-end run before unattended cadence. - **Body** from the mvp-first draft: single-file pipeline, one ghost per run, typed memory schema, cheapest expand before paid build. - **Armor** from the portability-first draft: substrate names only in config, sink that refuses to write where real memories live, no auto-cleanup of ghosts (disk stays hands-off). - **Heart** from the goal reframe above: creativity compounds; the product is insight, not code. That is not committee design. It is kill-with-salvage. The judges were not a rubber stamp. They destroyed three coherent proposals and left a pile of reusable parts. The synthesis step is where the creative mass from the kills becomes the winner's skeleton. Risk-ordered milestones, each gating the next: 1. **Recon**: verify what the knowledge system actually does today, not what the docs claim. (The old distiller path was a dead stub. Live ingest is a file scan over a path-to-layer map. Recall has no layer filter. Killed digests already enter as raw fact. These four facts shaped every later decision.) 2. **Provenance proof**: hand-write one mock counterfactual memory, prove it ingests under a dedicated synthetic layer, prove the banner is visible in recalled chunks. No timer before this passes. 3. **Executor probe**: one trivial headless build under the real unattended runner, no terminal attached. Exit code and logs to a file, always. Invisible process death is how autonomous work rots. 4. **Single ghost end to end**: one real kill, human-scored memory quality against the schema. 5. **Timer on**: unattended cadence. Success stays silent. Failures surface in status. Budget cap blocks further runs rather than bleeding. The order is the design. A prettier pipeline that writes unmarked fiction into a trusted memory store is worse than no pipeline. --- ## The design problem was provenance, not scheduling A fake experience in a trusted memory store is worse than no memory. Recall has no filters today. Synthetic notes will sit next to real ones. Marking only in metadata is not enough: if a chunk is retrieved, the reader (human or model) must see the mark *in the chunk*. Defence in depth: 1. **Dedicated layer** for synthetic memories in the ingest map, so the index records the class even when query APIs do not filter by it. 2. **Sink pre-flight** that refuses any emit path an existing ingest glob would claim under a non-synthetic layer. 3. **Frontmatter** with an explicit counterfactual provenance field and a filename prefix that never collides with human notes. 4. **Body banner as line one**, verbatim, so every retrieved fragment carries the warning even when frontmatter is stripped. The schema is the other half of the heart. Required sections, fixed order, each validated for substance (not empty, not generic filler): 1. **What surprised**: unexpected findings from actually building it. 2. **Technique emerged**: novel methods or tricks the build surfaced. 3. **Transfers to**: the problem class future brainstorms should recall this against. 4. **Kill verdict: confirmed or refuted**: did the ghost validate the original kill reasoning? 5. **Build shape**: what got built, rough size, how far it got. 6. **Open questions**: what a real attempt would still need to answer. A rehash of the original kill digest fails `What surprised`. Digests already reach the knowledge system as semantic fact. The whole point of the ghost is *new* signal that only appears when you force the idea into code. --- ## The pipeline One run, one killed idea, oldest unledgered first. **Intake.** Scan past brainstorm digests for kill verdicts only. Multiple corpus shapes exist (schema-declared digests, prose synthesis tables, older flat files). Parse all of them or starve silently. Dedup by a stable key over slug, approach id, and normalised sketch text. Salvage verdicts stay out of v1 intake on purpose. **Expand.** One local pass turns the ~250-word kill sketch plus its refutations into a buildable mini-spec, with the kill reasoning attached. Local first so the paid budget buys build, not planning. **Build.** One headless coding seat against the mini-spec, working directory = the ghost. Cost checked before the call. Cap per run. Timeout backstop. Spend recorded in an append-only ledger. **Distil.** Structured pass over mini-spec + build transcript + kill refutation → memory markdown matching the typed schema. Optimise for transferable creative insight, not a build summary. **Validate.** Every required field non-empty with substance. Empty means the run fails validation. Failed keys retry once on a later run, then park and surface. No silent burns. No infinite retries. **Emit.** Sink pre-flight, then write only into the synthetic memories directory. Ledger the result. Cadence is every three days, one ghost per run. Rough ceiling is on the order of ten runs a month under the per-run cap. The timer is the driver. Manual seats exist for status and dry-run; they are not required for operation. Automation stays event-triggered. What v1 deliberately does **not** build: multi-executor support beyond a config seam, salvage intake, auto-cleanup of ghosts, brain-side recall filters, remote push of anything. The open threads are distil quality dial, a stronger stamp lane if the layer mark proves insufficient, a morning-panel line for failures, and salvage-verdict intake later. --- ## Benefits: why the kill is the creative mass **Creativity compounds.** Each ghost adds experience the winner path never generated. The knowledge system gains roads not taken, not only roads shipped. **Killed ideas stop being waste.** A kill used to mean: write the refutation, move on, lose the build experience forever. Now the kill is a scheduled job. The sketch becomes a teacher on a delay. **The safe pick bias gets countered.** Brainstorm winners skew conservative because judges optimise for ship risk. The creative mass often lives in the options that failed a constraint. Generative Memories harvest that mass without putting the failed option into production. **Gates earn trust.** Autonomous write into a long-lived memory store is a red-zone operation if provenance is soft. Risk-ordered gates + typed schema + human score on the first real memory make the timer a promotion, not a leap of faith. **Transfer is first-class.** The `Transfers to` field is the retrieval key future work needs. Without it, you get build diaries. With it, you get a technique library indexed by problem class. --- ## The four-bug saga (why the gates exist) M3, the single-ghost end-to-end gate, did not pass on the first try. It took four runs. Each run failed for a different reason. Each gate caught exactly one bug. **Run 1: silent non-build.** The coding seat described the project in prose and never wrote files. The distil stage had nothing real to chew on. Fix: force file-writing acceptance checks into the mini-spec and treat "no artifacts" as build failure, not as a soft miss. **Run 2: escape noise.** Terminal control codes and status chrome polluted the transcript. The distil model tried to make meaning from junk. Fix: strip and normalise build output before distil; log the raw separately. **Run 3: validator harder than the model.** Schema validation rejected output the model almost got right: too strict on section shape, too loose on substance. Fix: validate required section presence and minimum substance length, not brittle formatting that fights the model. **Run 4: preamble leak.** Chain-of-thought framing rode into the memory body. The banner and sections were fine; the voice was contaminated. Fix: strip known preamble patterns; re-validate. Fourth run emitted the first real memory. I scored it myself before the timer earned trust. Real insight, not a rehash of the kill digest. That saga is the proof the methodology works. The gates are not ceremony. They are the reason an unattended writer is allowed near a trusted store. --- ## First memory: what the ghost taught Source kill: a "define work, not agents" approach from a work-not-people doctrine brainstorm. Judges killed the template shape. The ghost built a small validator instead. Highlights that earned the human score: - **What surprised:** the "How" axis is a Trojan horse for persona language. People naturally personify the mechanism ("the researcher finds…") instead of stating the work ("extract data from…"). The concept needs linguistic policing, not only structural guidance. - **Technique emerged: Linguistic Linting.** Negative constraints (banned keyword lists) as a primary architectural driver. More effective to punish persona-drift than to suggest a new style in a template. - **Transfers to:** agentic orchestration frameworks. Decoupling task definition from agent identity lets you hot-swap models without rewriting the instruction set. - **Kill verdict: confirmed as template, salvaged as validator.** A template alone cannot prevent human or model drift. As a linter with programmable enforcement, the pattern is resilient. The idea died as a template. It survives as a validator. That sentence is the whole product category: counterfactual experience that refines how you kill and how you salvage next time. --- ## Stage of development **v1 is live.** Not a design doc. Not a dry-run theatre. | Surface | State | | --- | --- | | Pipeline CLI | single-file, tests green | | Provenance path | synthetic layer verified end to end; banner visible in recalled chunks | | First ghost | emitted, human-scored | | Cadence | unattended timer every three days | | Cost | hard per-run cap; pause on breach | | Intake | kill verdicts across multiple digest shapes | | Open | distil quality dial, stamp lane, morning panel, salvage intake | What "live" does and does not mean: the system will keep emitting on schedule. Quality of distil is the remaining soft risk. If local expand or distil proves weak, the paid seat moves, or distil routes to a stronger model. That dial is deliberate and not yet burned. The first unattended fires after ship are the real soak. Status is the surface. Cap-pause is sticky on purpose; clearing it is a human act, not a silent retry. --- ## Thought process: what I refused to optimise away Several instincts fought the design. Naming them is part of the methodology. **"Just summarise the kill digests."** Rejected. Digests already enter the knowledge system. A summary of a summary adds no build experience. Without the ghost, you are laundering prose into the authority of memory. **"Write synthetic notes without building."** Rejected harder. That is how you poison a zero-loss store. The catastrophic failure mode is not wasted compute. It is a model that treats fiction as lived experience. **"Human approval every emit."** Rejected for v1. Hands-off was a locked decision. Trust moves into gates and schema, not into a queue Ari will ignore at 4am. The human score on the first real memory is the promotion ceremony for the timer, not a permanent approval loop. **"Clean up ghosts automatically."** Rejected forever under disk-is-hands-off. Status reports total ghost disk. Ari prunes. Autonomy does not get a delete path. **"Multi-executor from day one."** Rejected. Config seam only. One coding seat until headless reliability is boring. The through-line: **the product is creative insight under counterfactual provenance.** Everything else is instrument design. --- ## What you can steal tonight You do not need my pipeline. You need the law. 1. **Keep every rejected option in one place.** Kill digests, not chat scrollback. 2. **Schedule a cheap job that builds one and writes what it taught.** One is enough. Cadence beats backlog heroics. 3. **Mark those notes as fiction that teaches, forever.** Banner in the body. Dedicated class in the store. Sink that refuses to blur the line. 4. **Type the memory.** Surprise, technique, transfer class, kill confirmed or refuted. If those fields are empty, the run failed. 5. **Gate before unattended write.** Provenance proof, executor probe, one human-scored emit, then the timer. Killed ideas aren't waste. They're unexplored territory. Explore on schedule. The roads not taken keep teaching. The safe pick still ships. The knowledge system gets both. //A{'<3'} --- ## Context Is King URL: https://aris-space.com/documents/outcomes-and-systems/context-is-king Date: 2026-08-04 # Context Is King This cluster is about **how I approach a problem**. Not the pipeline. Not the tool. Not the seat as a law shelf. Two spines. One tone. ## Spine one: define the outcome If you can't say what "done" looks like in checkable terms, you're not ready to run a model. You're ready to write a brief. A prompt without an outcome is a slot machine. Pull. Hope. Pull again. The work is the brief: taste at the gate, evidence you'll accept, and the failure modes you refuse. Checkable done is a contract, not a vibe. If a stranger couldn't mark pass or fail from your definition, the definition isn't done yet. ## Spine two: systems thinking A problem isn't a chat turn. It's a system: inputs, constraints, feedback, state that outlives the window, and where judgement sits. Chat forgets. Disk remembers. When I hold a problem as a system, I stop asking the model to invent structure. I give it a room: what feeds in, what must stay true, how we know we moved, and who says yes. The model can fill a room. It can't invent the room you need. ## Tone: context is king, not the prompt Models swap. Prompts are cheap. Context is the moat: references, constraints, taste, prior decisions, the workspace you packed. If the output is thin, don't start with a cleverer prompt. Start with what you failed to bring into the room. ## What this cluster is (and is not) **Is:** approach and mentality. Teachings branch from the two spines above. **Is not:** a second syllabus of the ordered course. Library orients how you think. The course trains how you practise product building in sequence. For that ordered practice, take [Define outcomes, then build digital products](/courses/define-outcomes-build-products). Shared thesis. Separate jobs. No lesson dump here. **Is not:** workflow recipes (those live under workflows), pure laws (doctrines), or day-to-day process hygiene (discipline and process). ## Where to go next - [Define Done as Thinking](/documents/outcomes-and-systems/define-done-as-thinking): outcome as approach. - [Hold the System](/documents/outcomes-and-systems/hold-the-system): systems and context as approach. - [Stop Prompting. Start Defining Outcomes.](/documents/thoughts-and-scribbles/stop-prompting-start-defining-outcomes): the historical flagship essay (same thesis, older home on the graph). --- ## Define Done as Thinking URL: https://aris-space.com/documents/outcomes-and-systems/define-done-as-thinking Date: 2026-08-04 # Define Done as Thinking Done is not the last box on a checklist. Done is the first thinking move. Before you open the chat, before you name a model, before you polish a prompt: you decide what must be true when the work is finished. If you skip that, you're not running a session. You're spinning a wheel and calling the lucky stop "progress." This essay is about that move as an approach. Not a form. Not a pipeline recipe. Not a dump of the ordered course. For practice in sequence, take [Define outcomes, then build digital products](/courses/define-outcomes-build-products). Here we stay on how you face the problem. ## The first move Most people start with a wish. "Write me a landing page." "Fix the auth." "Make it feel premium." A wish is not done. A wish is a direction of travel without a destination you can mark. I treat **define done** as the first act of craft. Same as a director who will not call "action" until the shot list can fail or pass on set. The thinking is the contract. Everything after it is labour against that contract. If you cannot say what done looks like in checkable terms, you're not ready to run a model. You're ready to think harder. That is not a delay. That is the work. ## What "done" means Checkable done answers three questions a stranger could use without your private intent. **What must exist.** The observable thing: a file, a route, a render, a shipped behaviour. Not a vibe. Not "better." Something you can point at. **What evidence counts.** Tests, screenshots, a click path, a measurement, a diff you inspect. Evidence is what you accept as proof. Without it, "done" is a story the session tells itself. **What you reject.** Failure modes that block completion even when the output looks plausible. Wrong audience. Voice that is not yours. A green report with a black screen. Scope that quietly grew. If you never name reject criteria, the model invents success for free. Exists. Evidence. Reject. That triad is enough to hold the approach. You do not need a longer ritual to start thinking this way. You need the habit of refusing to run until the triad is clear enough to grade. ## Outcome as approach, not paperwork People hear "define the outcome" and reach for a template. Templates can help later. They are not the point. The point is a stance: **I will not buy labour until I can accept or reject the result.** Paperwork is what happens when you fill fields after you already opened the chat and need something that looks organised. Approach is what happens when the definition shapes what you ask for, what you pack into the room, and when you stop. An outcome is how you decide what the work is. It is not a form you attach so the session feels professional. When the definition is sharp, the prompt gets short. When the definition is soft, the prompt gets long and still fails. Length is not the fix. Clarity of done is. ## Failure: the prompt as substitute for done The common failure is substitution. You feel the missing definition as unease. Instead of writing the brief, you write a longer prompt. More adjectives. More "make sure." A system message that tries to carry the whole contract. Then another model. Then another pull. That is the slot machine. A prompt without done is a wish with better grammar. The model will fill gaps. It fills them with averages. Averages look finished until you hold them against reject criteria you never wrote down. Then you burn a cycle "refining the prompt" when the real miss was never stating what success and failure are. Scar pattern I trust: ambiguous instruction, reasonable model interpretation, wasted evening. The junior on set would have made the same wrong shot. Fix the definition. Do not blame the hands. ## How this sits in the cluster This is **spine one** of [Context Is King](/documents/outcomes-and-systems/context-is-king): define the outcome before you touch the prompt. The sibling spine is systems and context: hold the problem as a room that outlives the chat. That branch is [Hold the System](/documents/outcomes-and-systems/hold-the-system). The older public home of the same thesis is [Stop Prompting. Start Defining Outcomes.](/documents/thoughts-and-scribbles/stop-prompting-start-defining-outcomes). Historical essay. Same bloodline. This page is the library branch for done-as-thinking. **Library here. Course there.** Mentality and free roam in outcomes-and-systems. Ordered product practice at `/courses/define-outcomes-build-products`. Shared thesis. Separate jobs. No lesson dump on this page. ## The move, one line Define done first. Make it checkable: what exists, what proves it, what you refuse. Then run labour. If you skip the thinking, the prompt is only a substitute, and substitutes do not pass when the work has to land. --- ## Hold the System URL: https://aris-space.com/documents/outcomes-and-systems/hold-the-system Date: 2026-08-04 # Hold the System Done answers **what**. Systems thinking answers **what I'm standing inside**. You can name a checkable finish line and still run the work as a lonely chat turn. Wish in. Text out. Hope the window held enough truth. That is not holding a problem. That is renting a room for one conversation and throwing the key away when the tab closes. This essay is about the other spine: treat the problem as a system before you ask a model to labour inside it. Not a pipeline checklist. Not a tool tour. An approach to the room. ## Done is not the room [Define Done as Thinking](/documents/outcomes-and-systems/define-done-as-thinking) is spine one of this cluster. Exists. Evidence. Reject. That contract tells you what success and failure are. It does not tell you where the state lives, what feeds the work, how you know you moved, or who is allowed to say yes. Those are system questions. If you only define done, you still drop the model into fog and hope clarity arrives in the reply. I hold a problem as a system so the model fills a room I already designed. I do not ask it to invent the room. ## A small honest map You do not need a diagram library. You need four answers you can write in plain language. **Inputs.** What must enter the work: briefs, references, constraints, prior decisions, the files that already exist. If an input is missing, you are not "under-prompted." You are under-packed. **State outside the chat.** Chat forgets. Disk remembers. What must outlive this window: notes, boards, folders, decisions logged where the next session can read them. If the only memory is the transcript, the system resets every time you open a new thread. **Feedback.** How you know you moved: a test, a screenshot, a review pass, a measurement, a human gate that can fail. Feedback is the signal loop. Without it, labour is motion without proof. **Seat of judgement.** Who says yes. You, a second model with a narrow brief, a checklist, a client, a QC bar that is not optional. If judgement is "the model seemed confident," you have no seat. You have a vibe with credentials. Inputs. State outside chat. Feedback. Seat of judgement. That is enough of a map to stop treating a problem as one clever message. ## Context is the system you pack [Context Is King](/documents/outcomes-and-systems/context-is-king) is not a slogan for longer prompts. It is the tone of this cluster: models swap, prompts are cheap, context is the moat. Context is the system made portable. The references you bring. The constraints you refuse to re-negotiate every turn. The taste and prior decisions the labour must inherit. The workspace shape that keeps state readable. When people say "context engineering," I hear "pack the room," not "inflate the system message." If the output is thin, do not start with a cleverer prompt. Start with what you failed to bring into the room. Thin output is a packing failure before it is a wording failure. That is why context is king is not "paste more." Pasting more without a map is still a slot machine with a fatter ticket. Packing means the four answers above live where agents and future-you can find them, not only in the scrollback of one chat. ## Approach, not pipeline People hear "systems" and reach for a flowchart: step one, step two, handoff, deploy. Pipelines have a job. This page is not that job. Approach is a stance: **I will not buy labour until I know the room.** What feeds it. What outlives the window. How we know we moved. Who judges. Pipeline is sequence. Approach is how you face the problem before sequence matters. Workflow recipes live under workflows. Workspace layout lives under essays like [Build Your Workspace Once](/documents/workspaces/build-your-workspace-once). Here we stay on mentality: hold the system so labour has somewhere honest to stand. When the map is clear, the prompt gets short. When the map is missing, the prompt tries to smuggle architecture into adjectives. Architecture does not travel well as adjectives. ## How this sits in the cluster This is **spine two** of [Context Is King](/documents/outcomes-and-systems/context-is-king): systems thinking and the room you pack. The sibling spine is outcome as approach: [Define Done as Thinking](/documents/outcomes-and-systems/define-done-as-thinking). Done first. Then the room. Then labour. **Library here. Course there.** Mentality and free roam in outcomes-and-systems. Ordered product practice at `/courses/define-outcomes-build-products`. Shared thesis. Separate jobs. No lesson dump on this page. ## The move, one line Hold the problem as a system: inputs, state outside the chat, feedback, and the seat of judgement. Pack that room. Then run labour. If you only define done and skip the room, the model invents structure you never agreed to. --- ## Lock the still. Move one action. (MiniMax H3) URL: https://aris-space.com/documents/workflows/minimax-h3-lock-the-still Date: 2026-08-04 import { Pullquote } from '@/components/blocks' import { S7Frame, S7Window } from '@/components/blocks/s7window' ## I did not win MiniMax H3 by prompting harder I locked the still first. Then I moved one action. Then I fixed one variable. That is the whole craft story. ## Conduct: Terra ran the desk This run was **orchestrated in Codex**. I call that session **Terra**. Terra did not paint the final frames alone. It ran the chain: 1. Build still references with **GPT Image 2**. 2. Lock the vehicle with front and rear identity plates. 3. Send short, controlled motion jobs to **MiniMax H3**. 4. Review, kill, correct, keep the dailies. The intelligence is the stack and the loop. Not a single lucky prompt. ## The locks (conduct + five craft locks) | Lock | What it does | |------|----------------| | Conduct | One orchestrator (Codex / Terra) owns the chain | | Product plates | Front + rear identity so the black performance SUV survives every angle | | World keyframes | GPT Image 2 locks composition, light, and world | | One-action motion | H3 gets one verb and one camera or subject move | | One-variable fix | When it breaks, change only the broken axis | | Delivery | Keep native **21:9**, **2944 by 1248**, **24 fps**, **H.264** | ## What MiniMax H3 felt like H3 is **shot-scoped**, not film-scoped. - Strong image refs beat a giant sequence prompt. - Narrow shot language beats a multi-beat screenplay in one box. - Pretty mid-frames lie. Check first, mid, and end of every take. - Identity can hold for a Defender-class silhouette and still lose a rear spare or paint lock. That is a QC problem, not a vibe problem. I am not selling H3 as magic. I am reporting what held under an automotive identity test in ultrawide. ## Proof strip (raw H3 selects) These are **raw selects**, not a finished ad with approved music. 1. **Ice wall:** product clarity under cold light. 2. **Glacial river:** kinetic water and body solidity. 3. **Controlled data rupture:** front half solid, rear dissolves on purpose. 4. **Basalt arches:** world scale at 21:9. 5. **Reality exit:** rear geometry + spare held. ## Fail to fix (one variable) First splat attempt tried too many state changes at once. Camera jumped. Body lost. **Fix:** lock the camera. One controlled dissolve from the rear. Front stays solid metal. That single constraint is the difference between a morph accident and a readable thesis beat. ## Delivery truth I did not invent an upscale story for this pack. What shipped from the motion model: - **21:9** - **2944 by 1248** - **24 fps** - **H.264** Keep the ultrawide. Do not treat a phone crop as the creative act. There is an assembled 30 second study in the archive. It is **reference only**. Music and voiceover experiments are **not selected**. ## What I am not claiming - Not manufacturer work. Independent AI production proof. - Not "one prompt, whole commercial." - Not a finished sound mix. - Not a mystery finish pipeline. This post is stills to H3 to QC to native delivery. ## Closer Lock the still. Move one action. Fix one variable. Lock the still. Move one action. Fix one variable. --- ## Deep dive: the desk, the locks, the QC The skool cut is the craft thesis. Below is the same run with desk views, identity plates, fail pairs, and native delivery proof. ### G1 · Conductor One orchestrator owns the chain. Still build, plates, motion, and QC do not negotiate ownership mid-run.
Codex / Terra
GPT Image 2
Plates
MiniMax H3
QC
### G2 · Still stack Lock composition and product identity before any motion job leaves the desk.
Keyframe
Ice wall world keyframe with the black performance SUV
Plate front
Front identity plate of the black performance SUV
Plate rear
Rear identity plate including spare tyre geometry
### G3 · One-action card H3 gets one verb and one camera or subject move. Multi-beat language is the failure mode.
subject black performance SUV
verb hold / advance
move slow push along body axis
duration short take
aspect 21:9
multi-beat drive in, pan, dissolve, exit, cutaway
### G4 · Correction dial When a take breaks, change only the broken axis. Do not re-roll the whole brief.
identity
motion
light
crop
### G5 · Fail to fix · splat First splat tried multi-state change. Camera jumped. Body lost. The fix is one controlled dissolve with a locked camera.
FAIL multi-state
Failed splat take with multi-state collapse
FIX one dissolve
Controlled splat with front solid and rear dissolve

one variable: camera locked · rear dissolve only

### G6 · 21:9 delivery Keep the native ultrawide. Phone crop is not the creative act.
2944 × 1248 · 21:9 · 24 fps · H.264
native delivery from the motion model crop to 16:9 = damage zones
--- ## Lock 1 · Product plates Front and rear identity plates keep the black performance SUV stable across angles. Without them, H3 invents rear geometry and loses the spare.
Front identity plate of the black performance SUV
Plate front. Identity lock before motion.
Rear identity plate of the black performance SUV with spare tyre
Plate rear. Spare and rear geometry must survive every take.
## Lock 2 · World keyframes GPT Image 2 locks composition, light, and world before H3 sees a motion job. The ice wall keyframe is the still the first select answers to.
Ice wall world keyframe still used as motion reference
World keyframe · ice wall. Composition and light locked first.
## Lock 3 · What H3 held under test Shot-scoped models reward narrow language and strong refs. Under an automotive identity test in ultrawide: - Product silhouette held when plates were present. - Pretty mid-frames still failed end-frame QC on spare and paint. - Multi-beat prompts collapsed body or camera. One-action cards held. That is the operating envelope I am reporting. Not a brand claim for the model. ## Lock 4 · Fail pairs (splat + exit) ### Splat: multi-state fail → one dissolve fix First splat tried too many state changes at once. The fix is one variable: camera locked, rear dissolves, front stays metal.
### Exit: no spare fail → rear geometry held Identity can look solid in a mid-frame and still drop the rear spare. QC first, mid, and end.
Thumbs for the same pairs:
Thumb of multi-state splat fail
fail splat multi
Thumb of controlled splat fix
splat controlled
Thumb of exit fail without spare
fail exit no spare
Thumb of reality exit with spare held
reality exit
## Lock 5 · Delivery restatement What shipped from the motion model, without an invented upscale story: - **21:9** - **2944 by 1248** - **24 fps** - **H.264** Keep the ultrawide. Crop to 16:9 is a damage zone on this pack, not a refinement. --- ## Feature gallery · raw H3 selects These are **raw selects**, not a finished ad. ### 01 · Ice wall Product clarity under cold light. Thumbnail of ice wall select